Mentirinhas #2344
Fábio Coala 09/10/2026 | Source: Mentirinhas
09/10/2026 | Source: Blog do Dunossauro
Esse texto é um desabafo bastante pessoal, fala sobre assuntos muito sensíveis como violência sexual, saúde mental e suicídio. Sei que ele pode ser um gatilho para quem estiver lendo. Talvez nesse momento você não queira continuar e está tudo bem.
É engraçado pensar, às vezes é. A vida vai acontecendo, o tempo vai passando… Os cortes vão ficando para trás, criando um delta cada vez maior dos eventos traumáticos. E isso não vem acompanhado de um impulso de otimismo, menos ainda de uma fé no futuro. É uma coisa hautonlógica1, como aquele apud em dentes amarelos2 de aprender a ser quem se é. Uma coisa talvez nietzschiana “Ecce homo”3 do “Bom… é o que tem pra hoje, sigamos”.
E é incrível a quantidade de referências jogadas ao vento toda vez que tento falar sobre essas coisas. Afinal, elas me ajudam a racionalizar o trauma. É aquela vozinha do David Foster Wallace dizendo: “Isso é água, isso é água” em loop4. Claro, só sentar e chorar, muitas vezes já seria o suficiente, no lugar de vomitar esse monte de palavras com notas de rodapé para, pelo menos em algum lugar, alguém entenda toda essa merda desconexa na minha cabeça. Mas… se não botar esse EPI, acabo furando meus próprios olhos.
Em alguns textos atrás (acho que antes do fugazzi) alguém me mandou por email “acho que entenderia mais se soubesse de onde as referências vem”. Então, vou tentar “catalogar” o caos.
Não queria que isso virasse uma “breve entrevista com um homem hediondo”5, mas talvez dizer que a pessoa que me “fodeu”6 na infância7 não me assusta mais tanto. Claro, essa porra ainda vive em mim, vai me assombrar pra sempre e talvez o trauma tenha me feito tomar decisões tão ruins durante a vida que são irreparáveis. Não é como se o demoníaco Pacheco8 estivesse correndo atrás de mim as 24hs do dia, embora tenha dias em que, inegavelmente, sim!
É como se sobreviver fosse ser K. no Castelo9. Os dias passam, as coisas acontecem, a gente ama, conhece pessoas, tudo normal. Mas alguma coisa não se encaixa, tem uma parte do “ser quem se é” que não pode ser dita, porque sinceridade é um taboo. E mesmo se falasse, ninguém realmente se importa. Os fantasmas alheios também existem… “Isso é água”. Escrever sobre isso é como estar na “coitadolândia”: “Nossa que sofrido esse garoto”. Ao mesmo tempo que a dualidade vem do “se eu não falar sobre isso pra mim mesmo, ninguém o fará”. Mas o velho safado raramente está errado nesse ponto “arranje uma grande máquina de escrever (…) e bata na máquina, bata forte”10.
Por muitos anos, essa coisa me fez ter duas percepções sobre as pessoas, e isso era como pêndulo, vendo agora em retrospecto. “Se eu não valia nada, então qualquer pessoa podia fazer o que quissse comigo”, o que me meteu em lugares sombrios por tempo muito maior do que o necessário. Intercalando com “A vida não vale nada, então foda-se como trato as pessoas”, o que me fez machucar gente que não merecia e permitir ser machucado sem entender o que de fato aquilo era. E sempre que me dava conta do “to fazendo uma coisa muito errada” a autoflagelação vencia. Nesses momentos se abriam fendas, distorcendo o tempo, como se pudesse ver as atrocidades na minha mente em 4k.
Às vezes, o que me vinha era só Wherter11 e a súbita vontade de não estar mais nesse plano. Um negativismo magnético, como se Alexander Search12 tivesse parado de procurar. Um Drummond encarando de frente um “Silencioso cubo de treva”13. Sem perceber, fui embora. Não tirando a minha própria vida. Mas saindo daquele lugar fisicamente. Isso não foi proposital, foi uma situação. Mas me mudei pra longe, não que os fantasmas tenham ficado pra trás, mas pude ver que existia outra vida, outras pessoas, outro mundo.
Entenda que isso não quer dizer que, quando cheguei lá, não era um completo imbecil. Ainda era “estranho para mim mesmo”, mas todas as pessoas eram estranhas para mim também. O que torna tudo igual, porque a gente nunca conhece ninguém profundamente, mas diferente, pois nenhum conceito sobre ninguém me era dado. Ah… mas como eu chorei… sozinho, envergonhado, escondido. Mas, no momento em que decidi deixar as outras pessoas entrarem, elas simplesmente entraram. De forma honesta, branda, sem querer minha alma em troca de nada. Embora isso não seja nenhuma forma de cura, me deu um óculos novo da realidade. Nem todo mundo é a minha família.
Esses óculos foram ganhando funcionalidades com o passar do tempo. Filtro de luz azul, lentes fotocromáticas, proteção UV. É quase um “They live”14. Eles me davam dimensão de onde eu podia pisar. Embora, eles não tenham me dado a habilidade de olhar pra mim mesmo. Isso me colocava perto de coisas legais, de pessoas incríveis, mas que continuei machucando. Porque, embora elas fossem boas, eu não era. E essa sensação, não trouxe aquele medo paralisante de antes, nem mesmo pensamentos autodestrutivos. Me trouxe duas coisas que eu não havia experimentado ainda, não de forma tão explícita. Ódio e nojo. Ódio do meu futuro destruído, sem tijolos amarelos15 para caminhar, ódio da pessoa em que tinha me tornado, ódio de quem fez isso comigo. Ao mesmo tempo que enojava pensar em mim mesmo, eu era “sujo”. Reproduzia os padrões pendulares.
E não sejamos hipócritas… Esse padrão pendular se repete até hoje. Menos, muito menos do que no passado. O tempo não curou merda nenhuma. Ele só me deu mecanismos pra me abrir mais e me odiar menos. É… é sufocante dizer isso, mas talvez eu não me odeie mais tanto.
No sentido Mark Fisher da coisa. ↩︎
Faixa do Dead fish em Labirinto da memória. ↩︎
Ecce homo é um livro do Nietzsche onde ele descreve “Amor Fati” e também a apresentação de Pôncio Pilatos ao apresentar Jesus Cristo. ↩︎
Discurso de paraninfo de 2005 no Kenyon College. ↩︎
Trocadilho com livro do DFW ↩︎
Literal e figurado ↩︎
Conto do Jan Potocki sobre um homem que acorda num lugar estranho, com 3 mortos que são fantamas que o seguem pela cidade. ↩︎
Livro de Franz Kafka (longo) onde o protagonista nunca chega onde foi designado para estar, embora esteja exatamente onde deveria estar ↩︎
Poema de Charles Bukowski “Como ser um grande escritor” ↩︎
Personagem de “Os sofrimentos do jovem Wherter” de Goethe ↩︎
Heterônimo jovem de Fernando Pessoa que escrevia em inglês ↩︎
Poema de O sentimento do mundo chamado “Turno a janela do apartamento” ↩︎
Filme de John Carpenter ↩︎
No mágico de OZ, Dorothy encontra o caminho usando a estrada de tijolos amarelos ↩︎
Eli Bendersky 08/10/2026 | Source: Eli Bendersky's website
Monte Carlo simulations (or methods) is the technique of applying randomness and the Law of large numbers to the solution of various scientific and engineering problems. One of its first documented uses was by Stanislaw Ulam and John von Neumann for nuclear weapon simulations after WWII [1].
In this post I want to provide examples of some simple uses of Monte Carlo simulations. We'll start with the classical example of calculating the value of by throwing darts.
Suppose we take a square board and inscribe a quarter of a circle into it. We then proceed to throw darts at the board and record whether each dart hits inside or outside the quarter circle. Having thrown many such darts, we calculate the ratio of the darts inside the circle to the total number thrown.
Assuming our darts are distributed uniformly over the square, by the Law of large numbers this ratio should approach the ratio of areas of the quarter circle to the full square .
With a square side length of 1, we have:
Therefore:
Here's a visualization:
π ≈ —
Change the number of samples (dart throws) and click "Run" to regenerate. The code is very simple - here's a slightly sanitized version:
const total = Number(samples.value);
let inside = 0;
for (let i = 0; i < total; i++) {
  const x = Math.random();
  const y = Math.random();
  const inCircle = x * x + y * y <= 1;
  if (inCircle) inside++;
}
estimateValue = 4 * inside / total;
You'll notice that the estimate is relatively poor - even with 1000 samples - if you click "Run" several times, some numbers will be way off mark. While this method does estimate , it's not a particularly good estimate. I find that running ~10 billion samples is necessary to estimate it to 4 digits after the decimal with reasonable reliability.
In general, for independent trials like these, the typical sampling error decreases in proportion to , where N is the number of trials. This means that halving the error requires four times as many samples.
While the estimation may seem whimsical, it's an example of an important class of problems to which Monte Carlo simulation is applied: numerical integration. Our simulation estimates the area under the quarter-circle curve, which is a definite integral.
Many integrals are very difficult to solve analytically, and much research has been done in the area of numerical analysis to develop methods to calculate integrals. Monte Carlo methods are particularly useful for high-dimensional integrals, where other numerical methods can become prohibitively expensive.
A common use of Monte Carlo methods is estimating complex combinatorial calculations. These often don't have analytical solutions, and enumerating all options is intractable due to the scale of the numbers involved. As an example, let's consider the game of SET. Each SET card has four attributes:
And the goal is to find a "set" - three cards that are either all different or all the same for each attribute separately. As an example, here's a hand with a single set; see if you can find it [2]:
And the next hand doesn't have any sets:
Here's a question: given a freshly shuffled SET deck, what are the odds that the first 12 cards drawn will have no sets among them? This question is difficult to answer without using a computer.
It's easy to calculate the number of ways to deal a 12-card hand from a deck of 81:
But how many of these hands have no sets? Enumerating 70 trillion SET hands and checking each one can take quite a while, and there is no straightforward counting formula to answer this question. Some clever methods can be employed to leverage symmetries and other mathematical properties of SET to cut down this search space considerably. Donald Knuth himself worked on this problem and came up with a neat program (setset-all on his programs page) that found 2,284,535,476,080 such hands. Therefore, the answer to our question is:
There's a 3.23% chance that a randomly drawn hand of 12 cards from a full deck of SET will have no set in it.
Let's see how we can use a Monte Carlo simulation to answer this question with relatively small effort, without deep knowledge of the mathematical properties of SET that enable cutting down the search space Knuth-style. We can use the following pseudo-code:
C = 0
run N times:
  draw a random 12-card hand from a fresh deck
  count sets in the hand
  if no sets:
    C += 1

Estimated probability = C / N
After running 10 million simulated draws, I got an answer of 0.0323, which matches the real answer very closely.
The Monte Carlo approach lets us solve rather complicated problems in a very simple way. Suppose we want to answer the same question for a hand of 15 cards; this would blow up the search space considerably - there are about 100x more ways to select 15-card hands than there are to select 12-card hands. But for a Monte Carlo simulation, we adjust one small parameter and get a very reliable [3] answer (about 0.00037, in case you were wondering).
One domain where Monte Carlo simulations are ubiquitous is projections for retirement portfolios. Suppose someone prepares to retire with a total sum of 1 million dollars in their portfolio; they'd like to be able to draw $30,000 a year from the portfolio for their living expenses. Would that work?
There's a large number of factors to take into account when analyzing this question, but for simplicity let's focus on just two: portfolio return and inflation. We can run a naive estimate, assuming average values: suppose an average yearly portfolio return of 4%, and average yearly inflation of 2% [4]
Let's denote our portfolio return as , and inflation as . Then the real return each year is:
Starting with $1,000,000, at the end of the year we'll have $1,019,600 and then draw $30,000 for living expenses [5], ending with $989,600. If we continue this way, the money runs out after ~55 years, which means that a person retiring at the age of 65 should be reasonably safe, right?
But this is very simplistic; assuming just average returns is risky, because they do a poor job of representing reality, and many factors have uncertainty. For example, the sequence of returns matters a lot; a bad year (-10%) followed by a great year (+18%) would still count as "4% on average" but produces significantly less money than two consecutive +4% years. Inflation is also unpredictable, and sometimes correlated with portfolio returns; there could be bad years of high inflation and low / volatile returns that can wreak havoc on a portfolio.
As we add factors (variance in yearly draws, mixed portfolios of stocks, bonds, real estate, life expectancy, unexpected events, changing tax laws etc.), relying on a single average estimate becomes increasingly more fraught. This is why Monte Carlo simulations are very popular in this domain: by drawing from reasonable distributions based on historical data, a Monte Carlo simulation can easily run a million different scenarios and provide estimates: for example, what are the odds of money running out before death.
Here's a useful chart from a simulation I ran:
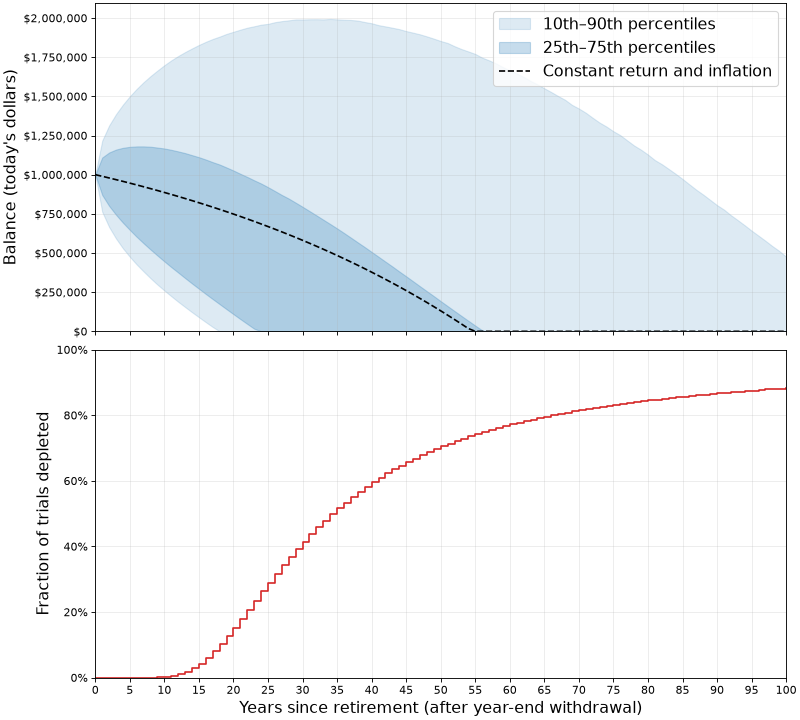
In the top chart:
In the bottom chart:
Looking a this simulation, under the current assumptions the plan sounds much riskier than the average assumption makes it appear. Assuming that a 65-y.o. person would plan for 25 years of retirement until death, the ~30% odds of not having sufficient funds for this duration of time are sobering. Perhaps a change in plans is needed (such as a more frugal lifestyle or securing additional funds in some way).
Retirement projection is only one of may ways in which Monte Carlo simulations are used for financial and economical applications; given the high uncertainty of these domains, it's very difficult to plan using analytical calculations. Company sales projections, growth projections, stock offering prices and much more uses Monte Carlo simulations to arrive at estimates with reasonable error bars.
All the code for the explorations in this post is available on GitHub.
| [1] | While these techniques were conceptually understood much earlier, it's not surprising that their first real applications coincided with the development of the first digital computers. As we'll see later in the post, Monte Carlo simulations benefit from running large numbers of trials to get reasonable accuracy. |
| [2] | The answer is: three empty red diamonds, three solid purple ovals, three striped green squiggles. Note that for each of the 4 SET attributes, these three cards are either all the same or all different. |
| [3] | For the same number of trials, this estimate has greater relative uncertainty than the 12-card estimate, because we encounter far fewer hands without a set. |
| [4] | For the examples in this post, we'll be using real dollars, or today's value of the money. We'll assume that the $30,000 yearly draw doesn't change and will instead apply inflation to the portfolio itself. |
| [5] | More sophisticated simulations would let us control these parameters; for example, are the expense funds drawn at the beginning or end of each year, or distributed on a monthly basis? |
Armin Ronacher 06/10/2026 | Source: Armin Ronacher's Thoughts and Writings
More than a year ago I wrote a few posts here that recommended people not to load custom tools into their context (or MCP servers) but to just use more scripts. Most importantly I wrote that Code Is All You Need and I wrote about that MCP needs code. With Pi 1.0 we now added MCP support via Codemode which in some ways is a long time coming, but then also maybe somewhat surprising to some. So I want to share some updated thoughts on this blog on what this all means.
When a harness like Pi provides tools for an LLM to call, it does so by supplying some tool definitions which then translate into some token structure on the server side. Whether a model is encouraged to call a tool is the result of the reinforcement learning process. Something I wrote about before if you want to learn more.
One of the reasons we strongly lean towards CLI and bash is because it allows
easy composition of calls, and because the model also learns how the file system
works when it’s trained. So when it invokes a tool like echo foo > /tmp/test.txt the model also learns that after that tool call, there is now a
file called test.txt in /tmp.
However bash has one fundamental limitation which is that it can only compose programs that run. And there are some things, which are not programs, but native tools to the LLM and they sort of have to be.
The most obvious example here is read or view_image. If a multimodal model
needs to read an image, it cannot use cat for that because the harness needs
to inject the actual image payload into the protocol of the LLM.
Another quite vivid example are sub agents. In order to spawn and orchestrate sub agents, it’s tricky to avoid tools that are provided by the harness. While in theory the agent could provide a CLI tool that talks to the outer harness via environment variables and Unix sockets, it’s a rather crude process. It however has another issue, and that is where the code runs.
To better understand that, it’s important to think a bit more about where all the bits and pieces run. There really usually are two different systems involved. The first is the brain, the harness: it runs on one machine. It’s trusted. The second is often the same machine, but it’s really where the tools are executing: the hands. In Pi we now call this the execution environment, but you can think of it as the target of all the operations.
Crucially what is important for us, is that there is a dividing line between the harness brain and the target environment that runs bash and executes the tools.
And splitting this in half has some really important consequences. For a start it means that they are running on different file systems and they have different levels of trust. If you for instance use a sandboxing solution like Gondolin your bash stuff will be sandboxed just fine, but the harness itself will not be.
Which brings us to what Codemode really does: it’s a way for the LLM to express and orchestrate complex operations on the harness side, but not the execution environment side. Codemode runs in the harness, in its own sandbox. In case of Pi it’s running in QuickJS within a WASM runtime with intentional limitations: no network, no file system, no timers, limited RAM. The only way is to call more tools. You could also imagine that Codemode could run Scheme or some other language as well.
If you are not familiar with Codemode, it’s basically just a way to issue tool calls from within some language, in our case JavaScript. That allows you to compose those calls without necessarily going through the LLM’s context. Credit for naming goes to our friends at Cloudflare who coined it.
For instance if you issue a bash call as a regular tool call in the LLM, then we only throw the trailing 2000 lines into the context and if the agent wants more, it needs to look at the overflow file itself. If however the agent issues that invocation via Codemode, then the Codemode side gets larger outputs sent structurally.
Most importantly, because Codemode is JavaScript the agent can express concurrent operations and basic workflows. A common way in which you see agents now use this, is to first probe at 5-10 items from some tool response to see what it looks like, and to then write a Codemode script that processes the next n items.
Codemode also allows you to throw state into the transcript! That means that one Codemode invocation can stash away data, that the next call in the session can load again. And remember: this is on the harness host, not the sandbox.
In case of Pi, Codemode also allows you to issue calls that naturally do not make any sense in Pi’s traditional interface. For instance if you want to generate images with an image model or you want to classify some text with a one shot classifier model, those Pi APIs are exposed via Codemode, but not via regular tools where they would just waste context.
So now that we talked a bunch about it, it’s probably worth being a bit more explicit about it. Let’s walk ourselves through some invocations of Codemode of recent Pi sessions of mine. Note that none of this code is human written. It’s from real sessions of Pi, just re-indented for your viewing pleasure. The agent starts using Codemode automatically either because it’s a task where the model already naturally picks up that tool, or because a user asked it to.
Note that Codemode is by default only enabled in Pi when MCP is enabled, but you
can turn it on with "defaultTools": ["+codemode"] in the settings. Just ask
Pi to enable it for you.
Let’s start simple with image generation. Image generation is a feature that Pi supports in the AI SDK core, but it’s not a tool that the agent can use. In the past the only way to use image models has been to write a bespoke extension or to have the agent run node itself and use the internal image APIs. However because we expose quite a few of the internal model APIs within Codemode, it means that the agent can use it:
const [painter] = await models.getAvailableOfType("image");
const result = await models.generateImages(painter, {
  input: [{ type: "text", text: "A cute little puppy sitting on a grassy " +
    "lawn, soft natural light, photorealistic" }],
});
if (result.stopReason !== "stop") return result.errorMessage;

for (const block of result.output) {
  if (block.type === "image") image(block);
  else text(block.text);
}
Note that the call to image() sends the image back as image content to the
LLM. On the harness side it feeds it directly into both the agent, as well as
onto disk as a temporary artifact in case the agent wants to be able to pass
that image back to bash.
Similar things apply to classifier models such as Jev. They also do not fit well into the workflows of an agent through the typical tools. But rather than making a bespoke tool available, Codemode just allows the agent to reach into the AI SDK and invoke those directly. Here you can see how Jev is used to mass process GitHub issues for a quick sentiment analysis:
const jev = await models.getModelOfType("classifier", "typesafe", "jev-latest");
const r = await tools.bash({
  command: "gh issue list --state open --limit 100 " +
    "--json number,title,body,comments",
});
const issues = JSON.parse(r.output);

const results = await Promise.all(issues.map(async (issue) => {
  const res = await models.classify(jev, {
    state: {
      title: issue.title,
      body: (issue.body || "").slice(0, 4000),
      comments: issue.comments.slice(-5).map(c => c.body.slice(0, 800)),
    },
    questions: {
      sentiment: {
        type: "choice",
        instructions: "What is the overall sentiment of the author towards pi?",
        criteria: {
          positive: "Appreciative, happy, constructive praise",
          neutral: "Matter-of-fact report or request without emotion",
          negative: "Frustrated, annoyed, upset, or angry",
        },
      },
      frustration: {
        type: "score",
        instructions: "How frustrated is the reporter?",
        criteria: ["not at all", "mildly", "clearly frustrated", "very angry"],
      },
      kind: {
        type: "choice",
        instructions: "What kind of issue is this?",
        criteria: {
          bug: "Bug report or regression",
          feature: "Feature request or enhancement",
          question: "Question or support request",
          other: "Docs, discussion, meta, spam",
        },
      },
    },
  });
  if (res.stopReason !== "stop") {
    return { n: issue.number, title: issue.title, error: res.errorMessage };
  }
  return { n: issue.number, title: issue.title, ...res.answers };
}));

store("sentiment_results", results);
return results
  .filter(r => !r.error)
  .sort((a, b) => b.frustration.score - a.frustration.score)
  .slice(0, 12)
  .map(r => `#${r.n} ${r.frustration.score.toFixed(2)} [${r.kind.choice}] ${r.title}`);
Note how in that above example we also call store() which dumps the result of
that execution into the session transcript. A future invocation of Codemode can
thus read back that result if it wants to.
The Promise.all here is fine, because Pi limits the total number of concurrent
tool executions itself to four and maintains a queue for the rest.
A more adventurous example is to use Jev to drive a game engine for debugging purposes:
Here it knows about my tankctl command and it built itself quickly a minimal
harness around it to drive a game loop to assist a user with debugging a
problem. Note how it built a 30 step loop in which each step goes back to both
the game engine to get a text dump of what’s going on, and then to Jev to
determine what to do next:
const jev = await models.getModelOfType("classifier", "typesafe", "jev-latest");
const tank = async (cmd) =>
  (await tools.bash({ command: `tools/tankctl "${cmd}"` })).output;
await tank("start --map assets/maps/night_arena.map");

const questions = {
  action: {
    type: "choice",
    instructions: "You control the tank '@' in a top-down tank game. " +
      "Choose the best next action.",
    criteria: {
      attack: "an enemy has line of sight to you and you can fire at it",
      approach: "no enemy has line of sight; drive toward the nearest enemy",
      dodge: "an enemy shot is heading at you and will hit soon",
      powerup: "a powerup is close and no enemy threatens you",
    },
  },
};

function commandFor(choice, st) {
  const p = st.player;
  const enemy = st.enemies.filter(e => !e.dead)
    .sort((a, b) => (b.los - a.los) || (a.dist - b.dist))[0];
  if (choice === "attack" && enemy) {
    return `fire_at tank ${enemy.id}; frames 30 until clear,damage,kill`;
  }
  if (choice === "dodge") {
    // move perpendicular to the closest incoming shot
    const s = st.projectiles.filter(s => !s.yours)
      .sort((a, b) => a.eta - b.eta)[0];
    const dir = s && Math.abs(s.vel[0]) > Math.abs(s.vel[1])
      ? (p.pos[1] > s.pos[1] ? "+down" : "+up")
      : (p.pos[0] > (s ? s.pos[0] : 0) ? "+right" : "+left");
    return `input ${dir}; frames 20 until damage; input stop`;
  }
  const powerup = st.powerups.filter(u => u.available)
    .sort((a, b) => a.dist - b.dist)[0];
  if (choice === "powerup" && powerup) {
    return `goto ${powerup.pos[0]} ${powerup.pos[1]} 180`;
  }
  return enemy ? `goto ${enemy.pos[0]} ${enemy.pos[1]} 90` : null;
}

const log = [];
for (let step = 0; step < 30; step++) {
  const st = JSON.parse(await tank("state"));
  if (st.state !== "playing") break;
  const threats = st.projectiles
    .filter(s => !s.yours && s.miss_dist < 1.5 && s.eta < 1.5)
    .map(s => `incoming shot dist ${s.dist} eta ${s.eta}s`)
    .join("\n") || "no incoming shots";
  const r = await models.classify(jev, {
    state: { map: await tank("view 8"), threats, hp: st.player.hp },
    questions,
  });
  if (r.stopReason !== "stop") {
    log.push(`#${step} classifier error: ${r.errorMessage}`);
    break;
  }
  const choice = r.answers.action.choice;
  const cmd = commandFor(choice, st);
  if (!cmd) break;
  log.push(`#${step} hp=${st.player.hp} ${choice} -> ${await tank(cmd)}`);
}
return log.join("\n");
Lastly, Codemode obviously is great for calling MCP servers. And because we do not actually expose any of the MCP tools to the LLM, the agent first uses provided APIs to issue a tool search within Codemode to discover what it might be able to do with the connected servers. This form of progressive discovery makes the whole MCP business work well enough for a lot of use cases today.
Here for instance you can see the agent reach for the Sentry MCP straight away, even without discovering the tools, presumably because it has learned during the RL process already about what the Sentry MCP looks like. But it learns from what we inject into the system prompt, that the Sentry server is available to begin with. It’s not completely guessing here.
const orgs = await tools.mcp__sentry__find_organizations({});
const { organizations } = orgs.structuredContent;
const results = await Promise.allSettled(organizations.map(org =>
  tools.mcp__sentry__find_projects({
    organizationSlug: org.slug,
    regionUrl: org.regionUrl,
  })
));
return organizations.map((org, i) => {
  const r = results[i];
  if (r.status !== "fulfilled") return { org: org.slug, error: String(r.reason) };
  if (r.value.isError) return { org: org.slug, error: r.value.content };
  return {
    org: org.slug,
    projects: r.value.structuredContent.projects.map(p => p.slug),
  };
});
I really don’t want to talk too much about MCP here, but MCP is in fact a protocol that greatly benefits from Codemode. The problem in parts is that MCP in practice often targets harnesses that do not (yet?) use Codemode. But the tide is shifting. In the meantime, a temporary crutch has been to do what Cloudflare did, and do Codemode within the MCP server. But now we have Codemode in Codemode which is pretty bad. It means double JSON escaping, easy for smaller models to get confused by and the inner code cannot call the outer tools. So if you for instance use the Cloudflare MCP servers in Pi, the agent needs to write JavaScript and funnel it through more JavaScript. This is really not optimal, but it’s also understandable that this is happening:
const accRes = await tools.mcp__cloudflare__execute({
  code: `async () => {
    const r = await cloudflare.request({ method: "GET", path: "/accounts" });
    return r.result.map(a => ({ id: a.id, name: a.name }));
  }`,
});
const accounts = JSON.parse(accRes.content.map(c => c.text).join(""));

const out = [];
for (const account of accounts) {
  const r = await tools.mcp__cloudflare__execute({
    account_id: account.id,
    code: `async () => {
      const r = await cloudflare.request({
        method: "GET",
        path: \`/accounts/\${accountId}/workers/scripts\`,
      });
      return r.result.map(s => ({ id: s.id, modified: s.modified_on }));
    }`,
  });
  out.push({ account: account.name, workers: r.content.map(c => c.text).join("") });
}
return out;
So to end things off: how well does Codemode work with MCP today? Well … not amazingly well. That’s because MCP servers are not really targeting harnesses that use Codemode yet (though at this point I think most harnesses support it).
For this to work well some recommendations:
outputSchema system in MCP is great for that.So where does this leave us? Is this a reversal of what I wrote a year ago where I encouraged CLIs? I don’t think so. In fact, the MCP ecosystem from my perspective picked up on exactly what we pointed out a year ago works: code. But Codemode goes beyond MCP in that it can act as a capable mechanism within the harness to express more freedom for the agent.
There are however also some things that we still need to figure out. For one, durability with Codemode is trickier. We might have to adopt some ideas from durable workflow engines here to snapshot invocations. Or maybe, something like Starlark is a better composition language than JavaScript given its deterministic nature.
Images, binary data and just the inability of this pattern to work with smaller models is also something that needs to be fleshed out. So it’s for sure not a perfect solution yet, but it’s quite a useful pattern that I expect us to leverage more.
Anonymous 03/10/2026 | Source: Matheus Fidelis - Engineering Blog
Esse post é uma tentativa de ilustrar minha forma de liderar. Eu utilizo o modelo adaptado de Liderança Situacional para me auxiliar a trafegar e estar presente em diversas frentes ao longo da minha semana e uso suas referências como uma régua para me adaptar a cada caso e agir de forma assertiva. Sei que esse tipo de post pode parecer um pouco arriscado, mas é o método que eu utilizo. Nada mais transparente do que isso. Ele pode mudar, mas não hoje.
Há quem considere esse framework de liderança datado. Eu realmente acho que existem muitas outras referências sobre como liderar. Mas o diferencial, na minha experiência prática, está em como ele facilita minha adaptação rápida entre diversos assuntos que evoluem em ritmos diferentes, conduzidos por pessoas com diferentes níveis de conhecimento, maturidade e senioridade. Vai fazer sentido quando eu começar a explicar. Confia.
A atuação de profissionais Staff+ raramente fica restrita aos limites de um único time. À medida que a senioridade aumenta, também aumenta a abrangência dos problemas sobre os quais se espera influência desse tipo de profissional. Nesse contexto, liderar deixa de significar acompanhar continuamente uma única equipe ou projeto e passa a envolver uma atuação mais “cross” entre temas que conectam diferentes iniciativas e direcionamentos mais estratégicos dos times de engenharia.
Essa mudança de escopo exige uma forma diferente de pensar a liderança técnica. A forma tradicional de liderança não condiz com o que se espera, na prática, desse papel. É humanamente impossível que um profissional Staff participe de forma ativa e profunda de todos os problemas técnicos de uma organização. E, fazendo um paralelo com alguns feedbacks que recebi nos últimos anos, mesmo que isso fosse possível, provavelmente não seria desejável. Quanto maior a dependência criada em torno de uma única pessoa, menor tende a ser a autonomia da organização.
A atuação cross-team precisa, portanto, ser seletiva para que a qualidade de vida do profissional também seja preservada. O objetivo não é estar presente em todos os lugares, mas identificar os pontos em que seu conhecimento, sua influência ou sua capacidade de decisão têm mais valor naquele momento.
Talvez uma das decisões mais difíceis na atuação cross-team seja entender quando entrar em uma discussão e, principalmente, quando sair dela. Para profissionais Staff+, disponibilidade não pode ser confundida com presença constante. Quanto maior o escopo de atuação, mais importante se torna escolher conscientemente onde investir tempo, profundidade e capacidade de decisão.
Entrar em todas as discussões não escala e, em muitos casos, reduz justamente a autonomia que deveríamos ajudar a construir. Eu costumo pensar que a entrada acontece quando existe uma diferença relevante entre a complexidade do problema e a capacidade atual do grupo de resolvê-lo sozinho, ou quando um risco precisa ser avaliado sob uma perspectiva diferente.
Um incidente crítico, por exemplo, pode justificar uma entrada rápida e bastante diretiva. Uma decisão arquitetural que atravessa diferentes domínios pode exigir Orientação para conectar contextos que um único time não possui. Uma RFC tecnicamente madura pode demandar somente Apoio para destravar uma decisão. E uma iniciativa conduzida por um time que já demonstrou domínio e autonomia talvez não exija nenhuma intervenção além da disponibilidade para um eventual cafezinho.
Entrar, portanto, não significa necessariamente assumir o controle de algo. E isso é difícil para profissionais mais resolutivos e técnicos, como é o meu caso. Significa, sim, aplicar a intervenção correta, com escopo suficiente para melhorar determinado cenário.
Sair, por sua vez, não significa abandonar, mas reconhecer que a presença deixou de gerar valor proporcional diante das outras demandas. Alguns sinais ajudam a perceber que chegou a hora de sair: o time passa a antecipar perguntas que antes precisavam ser feitas por alguém de fora, apresenta alternativas acompanhadas de trade-offs, consegue discordar com argumentos e identifica riscos sem depender de supervisão.
Saber ler o ambiente para fazer essas duas movimentações de forma constante e sem atrito é uma habilidade que vale a pena desenvolver.
Um mesmo comportamento pode ser eficiente em determinado contexto e completamente inadequado em outro. Uma equipe enfrentando um incidente crítico talvez precise de decisões rápidas, responsabilidades claras e direcionamento explícito, sem muita margem para ambiguidades. A mesma postura, aplicada continuamente a um grupo mais sênior, pode ser percebida como uma limitação de autonomia. A Liderança Situacional propõe, portanto, que o estilo de liderança seja ajustado de acordo com o nível de capacidade e disposição das pessoas diante de uma determinada tarefa ou responsabilidade. Essa flexibilização permite uma transição mais leve entre diferentes contextos.
Alguém pode possuir alta senioridade, ampla experiência de carreira e enorme autonomia em determinado domínio de negócio e, ao mesmo tempo, precisar de orientação diante de um problema completamente novo. Um Principal Engineer com experiência em sistemas distribuídos pode ter alta maturidade para discutir particionamento, consistência e resiliência, mas baixa maturidade ao assumir, pela primeira vez, uma responsabilidade relacionada a Machine Learning, compliance ou outro domínio com o qual ainda não tenha familiaridade. Trocamos a pergunta “qual é a senioridade desta pessoa?” por algo como “qual é o grau de autonomia dessa pessoa diante de determinado assunto?”.
Eu, por exemplo, posso participar de fóruns estruturantes, com profissionais de alta senioridade, sobre padrões de sistemas distribuídos, orquestração de containers, cloud providers, avaliação de risco e trade-offs técnicos complexos de consistência e, ao mesmo tempo, ser totalmente ouvinte em um fórum sobre otimizações de frontend. Essa alternância evita dois extremos totalmente “chatos”: tratar todos como se precisassem de supervisão ou tratar todos como se já estivessem prontos para operar sozinhos em qualquer cenário.
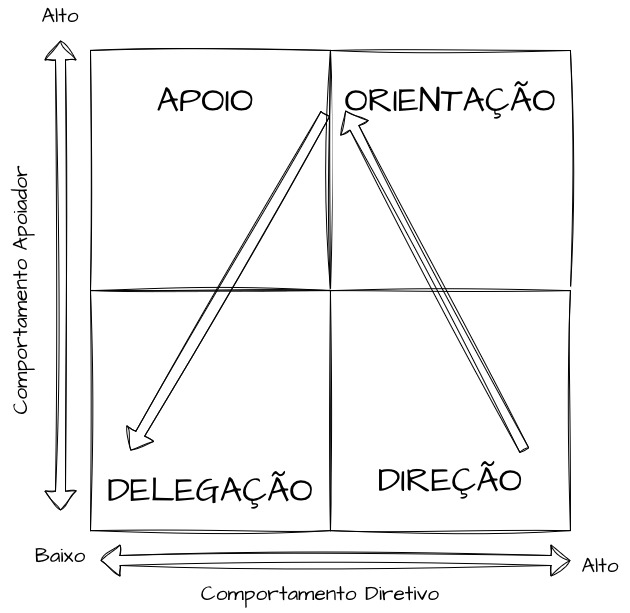
A Liderança Situacional combina quatro níveis possíveis de atuação do líder com quatro níveis de maturidade dos times ou liderados, adaptados a diferentes necessidades e situações. Um Staff precisa conseguir ler o ambiente, a pauta ou o fórum para saber como se posicionar diante das necessidades do momento. É aqui que entra a clareza do método.
Os níveis de atuação variam desde direcionamentos fechados e diretos até modelos de delegação ampla. São eles: Direção, Orientação, Apoio e Delegação.
Independentemente do modelo escolhido, o objetivo é conseguir trafegar entre todos eles sem autoridade formal ou imposição. O pior modelo de liderança do mundo ainda é melhor do que uma “carteirada”.
Direção é o nível de atuação mais prescritivo e imediato.
Nesse estágio, existe pouca capacidade ou pouco contexto para que a pessoa ou o time consiga tomar determinadas decisões de forma orgânica. Esse tipo de atuação geralmente é aplicado em cenários em que o tempo é valioso e não podemos lidar com divergências ou ambiguidades. Isso pode significar definir objetivos, estabelecer prioridades, determinar limites técnicos, dividir um problema em etapas ou até indicar diretamente uma abordagem inicial.
Em engenharia, esse tipo de atuação pode aparecer durante um incidente crítico envolvendo um time pouco familiarizado com determinado sistema. Em vez de iniciar uma discussão aberta sobre todas as alternativas possíveis, um profissional experiente pode direcionar explicitamente:
“Vamos interromper o rollout, voltar para a versão anterior, validar a estabilização das métricas e somente depois investigar a causa raiz.”
Nesse tipo de cenário, em que existe impacto para um cliente, há pouco espaço para discussão. O custo da indecisão é alto.
Uma atuação diretiva não deve ser confundida, em hipótese alguma, com autoritarismo. É preciso cuidado para que essa abordagem situacional não se torne permanente e crie um gargalo de decisão por medo ou comodidade. Sua função é reduzir a distância entre a complexidade do problema e a capacidade atual de quem precisa resolvê-lo, encurtando a tomada de decisão quando falta maturidade às pessoas envolvidas naquele contexto.
Orientação é o nível de atuação em que a decisão ainda é conduzida por quem lidera a sala, mas deixa de ser unilateral e fechada. Times e iniciativas mais adequados a uma liderança orientativa já possuem um nível de execução confiável, porém ainda apresentam alguma lacuna de maturidade, entendimento ou contexto. Aqui, já existe margem para questionamento, experimentação e erro, mas ainda é necessário um direcionamento formal e claro sobre objetivos e riscos.
Nesse estágio, a pessoa ou equipe já demonstra alguma disposição e possui um contexto inicial, mas ainda não acumulou capacidade suficiente para sustentar sozinha as decisões técnicas daquele domínio. Diferentemente da Direção, aqui existe espaço e tempo para explicar o raciocínio por trás de cada escolha e gerar divergências pontuais, não apenas comunicar uma decisão. O objetivo deixa de ser “resolver pela pessoa” e passa a ser “resolver junto, explicitando o porquê”, para que a capacidade real comece a se formar.
“Vamos precisar salvar os logs das aplicações de cartão de crédito em dois locais. Vamos ingeri-los e consultá-los de forma quente para a operação diária no Elasticsearch, mas também iremos armazená-los no S3, em uma camada mais fria. Teremos uma retenção de 7 dias na stack de observabilidade para troubleshooting e uma retenção de 5 anos no Deep Archive para auditoria. Esse requisito não é negociável, pois é uma exigência regulatória das auditorias ISO.”
Os times serão parte ativa da solução, elaborando, questionando e debatendo os requisitos e a implementação de fato. Porém, as lacunas que impediriam um entendimento mais profundo são preenchidas de forma explícita por quem orienta.
O maior risco da liderança orientativa é tratá-la como uma aula unidirecional, fazendo com que ela retorne a um perfil diretivo ou pouco se diferencie dele. Se quem orienta apenas explica, sem abrir espaço real para perguntas, discordâncias ou rodadas de entendimento, a atuação regride para Direção — o pior cenário possível. A função desse nível é reduzir o risco imediato da decisão e, ao mesmo tempo, investir na formação de autonomia futura sobre aquele contexto específico.
Apoio é o nível de atuação em que a competência técnica já não é o problema. A decisão sobre o que fazer e como fazer já está clara para quem vai executar. O que falta não é capacidade, mas confiança suficiente para sustentar essa decisão sozinho, segurança diante da visibilidade da mudança ou, simplesmente, alguém para validar o raciocínio antes de seguir adiante.
Esse tipo de liderança funciona bem em iniciativas nas quais o time já implementa sem gargalos técnicos, mas ainda trava na hora de decidir. Elabora propostas e RFCs, debate e compara alternativas, mas hesita em “bater o martelo” entre várias opções. Colocando os níveis em uma régua imaginária, talvez esse seja o tipo de liderança no qual ocupo cerca de 80% do meu tempo. O objetivo aqui é prestar apoio somente quando necessário, dando mais segurança sem aumentar o nível de supervisão.
“Revisei o plano de migração e a estratégia de rollback está correta. Não mudaria nada. Pode publicar a RFC. Se surgir alguma objeção, respondemos juntos.”
“A alternativa de utilizar cache-aside com um TTL baixo me pareceu mais atrativa e segura do que a alternativa de aplicar um Bloom Filter com TTL alto. Prefiro seguir por esta. Se errarmos, voltamos rápido e sem impacto.”
Nesse cenário, a pessoa ou o time precisa continuar com a autoria da decisão. O apoio apenas reduz a distância entre o que ela já sabe e a segurança necessária para seguir adiante.
Delegação é o nível de atuação em que o Staff se retira da tomada de decisão do dia a dia. Não porque abandonou o time, mas porque a capacidade técnica e a confiança para agir e tomar decisões já são altas o suficiente para que qualquer intervenção deixe de agregar valor e passe a atrapalhar.
Em engenharia, esse tipo de atuação aparece quando um grupo já assumiu autonomia total sobre um sistema, contexto ou iniciativa, incluindo decisões de arquitetura, priorização e resposta a incidentes. Nesse cenário, ao ser chamado para opinar sobre uma mudança de modelagem no domínio, o profissional Staff conscientemente devolve a decisão:
“Essa decisão é de vocês. Hoje, o time conhece esse domínio melhor do que eu. Sigam com o que fizer mais sentido. Me chamem se aparecer algum risco que fuja do domínio de vocês ou que não consigam resolver sozinhos.”
A atuação aqui se resume a confirmar, de forma explícita, que a decisão pertence a quem já demonstrou repertório para sustentá-la sozinho — sem necessidade de transferir conhecimento ou validar pontualmente.
O maior risco da Delegação está em dois extremos. O primeiro é usá-la como desculpa para negligência: delegar e desaparecer, sem manter nenhum canal real de escalada, tratando “confio no time” como sinônimo de “não preciso mais acompanhar nada daquele contexto”. O objetivo é confiar, não deixar o time desamparado.
O segundo, mais sutil, é delegar a responsabilidade sem, de fato, abrir mão do controle: seguir revisando cada decisão nos bastidores, questionando escolhas já tomadas ou reincorporando-se ao processo a todo momento.
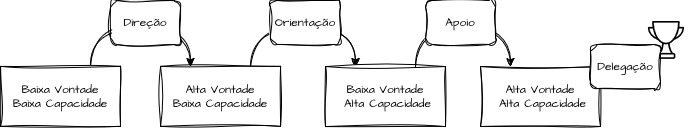
Agora que o modelo está claro, vamos aplicá-lo a cenários hipotéticos de times de engenharia. A cada situação, a forma de liderança precisa se adequar às características de maturidade envolvidas — a régua e o termômetro são sempre o quórum e o contexto das pessoas envolvidas.
Esse é o perfil de menor prontidão diante de um assunto específico: pouco domínio técnico do problema e, ao mesmo tempo, pouca disposição real para lidar com ele. Não é necessariamente preguiça. É comum essa combinação aparecer quando o assunto é novo, quando a pessoa nunca teve contato direto com aquele tipo de desafio ou quando já existe uma experiência ruim recente relacionada àquele contexto — o tipo de situação que gera hesitação antes mesmo da tentativa.
Esse é exatamente o cenário em que Direção funciona melhor: reduzir a ambiguidade ao mínimo possível, porque não há capacidade nem confiança suficientes para sustentar uma decisão autônoma sem risco. Um exemplo comum em engenharia é herdar a manutenção de um sistema legado, escrito por alguém que já saiu da empresa e sem nenhuma documentação viva, depois de ter visto colegas tentarem manutenções ou evoluções e causarem problemas graves em produção.
Diante disso, o caminho mais eficaz não é abrir espaço para exploração, mas indicar exatamente o próximo passo e reduzir o raio de manobra até que exista repertório mínimo para operar com mais liberdade.
Aqui, as pessoas ainda não têm domínio técnico sobre o assunto, mas carregam motivação e vontade de aprender. Existe curiosidade real, disposição para errar, perguntar e se engajar, mesmo sem saber exatamente por onde começar. É um perfil mais fácil de conduzir do que o anterior, porque a resistência não está na vontade, mas na falta de repertório. Esse é o cenário ideal para uma liderança de Orientação, em que existe energia suficiente para sustentar um processo de aprendizado.
Um exemplo comum é o de um engenheiro que nunca trabalhou com mensageria e eventos, mas se oferece para investigar por que um consumer está acumulando atraso. Ele lê a documentação por conta própria e chega com hipóteses, mesmo que estejam erradas. Ignorar essa disposição e simplesmente entregar a resposta pronta desperdiça o que esse perfil já tem de mais valioso: a vontade de aprender fazendo, talvez uma das melhores partes da engenharia de software.
Esse cenário de maturidade aparece em profissionais que, por si sós, já sabem o que fazer e como fazer, mas têm dificuldade para agir e tomar decisões estruturantes sozinhos. Às vezes, é insegurança pontual ou falta de autonomia; em outros casos, desmotivação ou excesso de cautela diante da exposição da decisão. Medo de agir sem alguém por perto. Normal.
É exatamente aqui que a liderança de Apoio entra, gerando segurança para destravar a decisão. Um exemplo comum é o de um Tech Lead que sabe exatamente como corrigir um memory leak em um serviço crítico, mas hesita em aplicar o fix em produção porque uma tentativa anterior, meses atrás, gerou um pico de latência e violou os SLOs do produto. A solução técnica já está pronta há dias; só falta alguém validar que ela está certa e dizer “pode seguir”.
Esse tipo de cenário também pode esconder algo mais preocupante: profissionais extremamente seniores desmotivados, o que gera risco real para o time e para a empresa. Vale ir além da leitura mais básica de liderança, entender os motivos por trás disso e exercitar uma liderança mais humana, atenta ao momento profissional da pessoa.
Esse é o perfil de maior prontidão, em que o time já tem domínio técnico consolidado e confiança suficiente para agir sem depender de validação. Diferentemente dos outros três níveis, aqui qualquer intervenção constante deixa de ser ajuda e passa a ser gargalo e ruído. A resposta adequada é Delegação, e ela só é sustentável quando esse nível de maturidade já foi demonstrado de forma repetida.
Um exemplo é uma squad que administra sozinha um pipeline de dados essencial para outras áreas da empresa, decidindo particionamento, escala e SLA sem precisar de aprovação prévia e recorrendo a alguém de fora somente quando o risco genuinamente ultrapassa o domínio do time. Tratar esse perfil como se ainda precisasse de Apoio ou Orientação é limitar a autonomia de um perfil raríssimo.
Essa adaptação que utilizo da liderança situacional me ensinou na prática que, não é possível estar presente em todas as mesas e decisões, e me deu uma forma simples de entender qual tipo de intervenção cada contexto realmente precisa. Em alguns momentos, será necessário direcionar. Em outros, orientar, apoiar ou simplesmente sair do caminho pra um time fazer algo de uma forma muito melhor do que se eu estivesse presente.
Quanto maior o escopo de atuação, mais importante se torna reconhecer que liderança não significa centralizar assuntos, decisões e avais para que as pessoas “possam trabalhar”. O objetivo sempre deve ser reduzir dependências, aumentar a autonomia e melhorar a capacidade dos times de resolver problemas sem depender constantemente de uma única pessoa.
No fim, uma boa atuação Staff talvez seja justamente essa: saber quando entrar, como contribuir e, principalmente, quando deixar de ser necessário.
Eli Bendersky 01/10/2026 | Source: Eli Bendersky's website
Re-reads:
Armin Ronacher 29/09/2026 | Source: Armin Ronacher's Thoughts and Writings
Serde is an amazing serialization library for Rust and it has been a huge reason why I felt productive with it for years. However already while at Sentry I got quite frustrated with some of the limitations with it but actually replacing Serde is tricky because of the might that it has in the ecosystem. Also because it’s quite hard to actually do better without also making some potentially painful compromises.
Here are three examples of Serde corner cases that show poor interactions of Serde features or unexpected limitations:
An internally tagged enum, with serde_json‘s arbitrary_precision feature
turned on:
#[derive(Deserialize)]
#[serde(tag = "type")]
enum Shape {
    Circle { radius: f64 },
}

serde_json::from_str::<Shape>(r#"{"type": "Circle", "radius": 1.5}"#)
// error: invalid type: map, expected f64
Serde’s data model has no place for arbitrary precision numbers, so serde_json
uses in-band signalling with a map with a magic key. The enum has to buffer the
fields until it has seen the tag, and the buffer does not know about the magic
key. Because Cargo features are unified, it’s enough for any crate in your
dependency graph to turn the feature on.
#[derive(Deserialize)]
struct Stats {
    scores: HashMap<u32, u32>,
}

#[derive(Deserialize)]
struct Report {
    name: String,
    #[serde(flatten)]
    stats: Stats,
}

serde_json::from_str::<Report>(r#"{"name": "x", "scores": {"42": 23}}"#)
// error: invalid type: string "42", expected u32 at line 1 column 35
Stats on its own parses {"scores": {"42": 23}} just fine. JSON keys are
always strings, and serde_json only turns them into integers if the type asks
for one. However once flatten buffers the value, "42" is just a string.
The error also points at the end of the document rather than at the key.
fn from_hex<'de, D: Deserializer<'de>>(d: D) -> Result<u32, D::Error> { ... }

#[derive(Deserialize)]
struct Theme {
    #[serde(deserialize_with = "from_hex")]
    primary: u32,
    #[serde(deserialize_with = "from_hex")]
    accent: Option<u32>,
}

//error[E0308]: `?` operator has incompatible types
//  |
//  |     #[serde(deserialize_with = "from_hex")]
//  |                                ^^^^^^^^^^ expected `Option<u32>`, found `u32`
//  |
//help: try wrapping the expression in `Some`
//  |
//  |     #[serde(deserialize_with = Some("from_hex"))]
//  |                                +++++          +
A function cannot be passed as a type parameter, so there is no way to apply
from_hex to the inside of an Option, a Vec or a map. You write another
function for every wrapper, and once you have from_opt_hex the field is no
longer optional unless you also remember to add #[serde(default)].
None of these are bugs that are easy to fix in Serde. They fall out of its design, and that design is protected by Serde’s stability guarantees.
Back in 2022 I started an experiment called Deser. It’s a serialization library for Rust that takes the user experience of Serde and puts it on top of a completely different architecture inspired by miniserde. I never really finished it and it sat around for a few years. I picked it back up, and it has now reached a point where I think it’s worth looking at. Even just to inspire others to see if they want to explore the space.
The name is Serde with its two halves swapped. Deser is Serde but the other way
around. In Serde, a type drives the deserialization process: a Deserialize
impl asks the deserializer for the kind of value it expects, the format calls
back into a visitor. Every nested value is handled by recursion which makes
Serde deserialization inherently grow the stack with each level of nesting.
Deser on the other hand turns this around and the format tells the type of the next value and pushes events into a sink. When a sink hits the start of a nested value, it doesn’t call into it but hands back a new sink to a driver, which keeps all state on the heap (in fact, in an arena). On the way out, emitters return their nested values instead of recursing into them.
That also means that Deser cannot support formats like protobuf that are not self describing. They are in fact quite intentionally left out of the design entirely. Which is one way to say: if you want to “fix” Serde, you need to make some other compromises.
Most of the reasons for Deser’s ideas go back to Sentry Relay, which processes enormous amounts of untrusted JSON. Over the years when I was at Sentry we ran into the same set of problems again and again, and many of them are not really bugs in Serde but consequences of its design. Serde’s stability guarantees mean that a lot of them cannot be fixed without breaking every format and every hand written implementation. Most of these problems come from three decisions:
One set of traits for all formats. Serde serves both self describing formats (JSON, YAML, TOML, …) and formats where the reader has to know the type upfront (postcard, bincode, protobuf, …). That is incredibly useful, but it means that some features only work with some formats, and you find out at runtime. In case of Serde it also has some odd wrinkles where a derived struct quietly accepts an array in place of an object in JSON for instance.
A fixed data model that loses information when buffering. Internally
tagged enums, untagged enums and flatten need to buffer values before
they know what to do with them. The buffer can’t hold everything the format
knew, errors lose their location and extensions to the ecosystem rely on
in-band signalling to express things such as arbitrary precision numbers.
Recursion on the call stack. Every level of nesting uses stack space. Formats protect against this with a recursion limit, but the moment you go through a code path that doesn’t have one (writing, dynamic values), deeply nested data can take down your process. It also means that a deserialization cannot be paused while you wait for more input.
Many of the corresponding Serde issues have been open for years, and I wrote about abusing Serde before. People have tried different angles on this over the years. Some went minimal and dropped most features to get fast compiles and no recursion. dtolnay’s own miniserde is the best example of that, and deser’s trait design was originally modelled after it. Other recent attempts went for runtime reflection, or for a new data model with a focus on binary formats.
If you want to read up on all of the collected challenges with Serde’s design, I maintain a lengthy list here.
First of all I don’t think it’s likely that one can replace Serde. The orphan rule entrenches Serde incredibly well in the ecosystem. But some things are within the reach of a crate author’s control. In case of Deser it’s completeness.
Deser today implements all important self describing formats from YAML, JSON, TOML, CBOR, JSON5 and the likes, but also XML and plist to really close the gap. XML in particular is something Serde has declined to support, and it shows (more on that below). At the very least format support should not be the reason not to use Deser.
The second problem usually is that actually solving Serde’s issues comes at a significant cost in compile time and/or runtime performance. Deser is no different. While Deser’s compile times are a bit better than Serde’s, the binary bloat is quite a bit worse and the runtime performance is mixed. It’s roughly comparable if you look at the numbers but depending on the format structure you are losing significantly from some of the tradeoffs.
That said, it’s now in a state where it’s at least in principle a drop-in replacement where the tradeoffs might work well for users.
Deser does not try to be significantly different than Serde on the surface
level. For most uses you derive Serialize and Deserialize and then start
using it with your format implementing crate of choice. Most attributes are
very similar, though they are taking Rust expressions instead of strings.
use deser::{Serialize, Deserialize};

#[derive(Debug, Serialize, Deserialize)]
#[deser(rename_all = "camelCase")]
pub struct Account {
    id: u64,
    account_holder: String,
    #[deser(default)]
    is_deactivated: bool,
}

let account: Account = deser_json::from_str(json)?;
The difference in the design would become more apparent if you implement a serializer or deserializer yourself. Instead of visitors that call into each other recursively, deserializing a type creates a sink which receives events that are directly emitted by the parser, and serializing produces emitters that hand out values. Nested sinks and emitters are handed back to a driver, which keeps them on the heap. This design, which is entirely stolen from miniserde, gives some interesting consequences:
Send, so it can move between
threads while you wait on IO which makes it much nicer to use with tokio.
Formats like JSON, CBOR and MessagePack can be parsed as a stream if you
so desire.DateTime,
Uuid, etc.) that also all carry a fallback for formats that don’t understand
them. Unlike Serde this means it does not rely on in-band signalling of
objects with magic keys to smuggle values through.On top of that are a lot of things that I just wanted to have:
as = Option<Vec<DisplayFromStr>>)Here is a small configuration type that shows a few of these together:
use deser::adapters::DisplayFromStr;
use deser::de::Recording;
use deser::{Deserialize, Serialize};
use deser_encoding::Hex;
use deser_validate::{Check, NonEmpty, Range};
use ipnet::IpNet;

#[derive(Debug, Serialize, Deserialize)]
pub struct Config {
    // at least one 256-bit key, each written as hex
    #[deser(as = Check<NonEmpty, Vec<Hex>>)]
    secret_keys: Vec<[u8; 32]>,
    // `IpNet` knows nothing about deser, but has `FromStr` and `Display`
    #[deser(as = Option<Vec<DisplayFromStr>>)]
    allowed_networks: Option<Vec<IpNet>>,
    listeners: Vec<Listener>,
}

#[derive(Debug, Serialize, Deserialize)]
#[deser(tag = "type", rename_all = "snake_case")]
pub enum Listener {
    Unix { path: PathBuf },
    Tcp {
        host: IpAddr,
        #[deser(as = Check<Range<1, 65535>>)]
        port: u16,
    },
    // types this version does not know are kept and written back
    #[deser(other)]
    Other(#[deser(tag)] String, Recording),
}
Adapters are types, so Hex can go inside a Vec, and DisplayFromStr inside
a Vec inside an Option. Validators are adapters too, so
Check<NonEmpty, Vec<Hex>> decodes the keys and then checks that there is at
least one. The catch-all variant keeps the tag and a recording of everything
else in case someone wants to process it later.
Errors are something I care a lot about, so here is what happens when a value is wrong:
secret_keys = ["9f86d081884c7d659a2feaa0c55ad015a3bf4f1b2b0b822cd15d6c15b0f00a08"]
allowed_networks = ["10.0.0.0/8", "fd00::/8"]

[[listeners]]
type = "unix"
path = "/run/app.sock"

[[listeners]]
host = "127.0.0.1"
port = 0
type = "tcp"

[[listeners]]
type = "quic"
host = "::1"
alpn = ["h3"]
let config: Config = deser_toml::Deserializer::from_str(input)
    .deserialize_with(|driver| driver.push_layer(PathLayer::new()))?;
Note that here the tag of the internally tagged enum comes last which means that the values have to be buffered until the tag is known. In Serde this is tricky and we would lose the location if we used some tricks to add it. With Deser however, with the path layer enabled Deser you where in the structure the problem is:
Unexpected: invalid value: must be between 1 and 65535 at line 10 column 8 (path: listeners[1].port)
Deser really wants to be extensible, and XML is a more extreme example of the differences between Deser and Serde. Here is an Atom entry that mixes in Dublin Core for the authors:
use chrono::{DateTime, Utc};
use deser::Deserialize;
use deser_value::Value;
use deser_xml::DeserializerConfig;

deser_xml::namespace!(
    atom = "http://www.w3.org/2005/Atom",
    dc = "http://purl.org/dc/elements/1.1/",
);

#[derive(Debug, Deserialize)]
struct Entry {
    #[deser(rename = atom!("title"))]
    title: String,
    #[deser(rename = dc!("creator"))]
    creators: Vec<String>,
    #[deser(rename = atom!("updated"))]
    updated: DateTime<Utc>,
}

// entries we understand, and everything else is kept as it is
#[derive(Debug, Deserialize)]
#[deser(untagged)]
enum Item {
    Entry(Entry),
    Other(Value),
}

let item: Item = DeserializerConfig::new()
    .resolve_namespaces(true)
    .from_str(r#"
        <entry xmlns="http://www.w3.org/2005/Atom"
               xmlns:d="http://purl.org/dc/elements/1.1/">
          <title>Deser</title>
          <d:creator>John</d:creator>
          <updated>2026-09-29T21:00:00Z</updated>
          <d:creator>Jane</d:creator>
        </entry>
    "#)?;
XML uses namespaces which means that names need to be matched by their namespace,
not by the prefix the document happens to use. Here the document says d: and
the type says dc!. atom!("title") is just the string
{http://www.w3.org/2005/Atom}title, which works because attributes are
expressions. The two creators are collected into one Vec even though there is
another element between them, and the text of updated goes straight into a
chrono datetime. Because the enum is untagged, the entry has to be buffered
before a variant is picked, and deser’s buffer keeps both creators. So the
result is an Entry with John and Jane.
quick-xml, the most popular XML crate for Serde, drops the prefixes and ignores
namespaces entirely, so a <x:title> from some other namespace is happily
accepted as the title of the entry. The split list part though is considerably
worse. A plain Entry fails with a duplicate field error for creator, unless
you turn on the overlapped-lists feature (which, remember, is a global
additive flag that any crate could set). That feature makes quick-xml read
ahead to the end of the element and buffer everything in between, without a
limit unless you set one.
But the feature only helps when quick-xml is hooked up to the struct directly
and no buffering is taking place. Wrap the struct in the untagged enum and
Serde buffers the entry itself. Read from that buffer, Entry sees creator
twice and fails again. The fallback is a map, which keeps only the last
creator, and there is no error. With or without the feature you get this:
Other({"creator": {"$text": "Jane"}, "title": {"$text": "Deser"}, ...})
Notice how John is gone.
Format specific extension types such as TOML datetimes are another case. TOML
has them natively, Serde’s data model does not, so the toml crate passes them
on as a map with a magic key. In Deser a datetime is an extension value, which
formats that know it keep and all others write as a string:
let value: Value = deser_toml::from_str("released = 2026-09-29T21:00:00+02:00")?;

deser_json::to_string(&value)?;
// {"released":"2026-09-29T21:00:00+02:00"}
deser_toml::to_string(&value)?;
// released = 2026-09-29T21:00:00+02:00
The same with serde_json::Value gives you
{"released":{"$__toml_private_datetime":"2026-09-29T21:00:00+02:00"}}, and
reading the value into a chrono::DateTime fails outright with invalid type: map, expected an RFC 3339 formatted date and time string.
So now that you know Deser is at least in theory cool, at what cost?
It is not free. The design relies on dynamic dispatch and on sinks and emitters
that live on the heap, and that has considerable runtime overhead. In my own
measurements for JSON, Deser reads somewhere between 33% faster and 60% slower
than serde_json depending on the data. On average it’s about 10% slower for
reading. Writes are between three times as fast and 70% slower and a wash on
average. For YAML and TOML it’s noticeably faster than the Serde based crates,
but that is more about the format implementations than the architecture.
Compile times slightly are better, but not dramatically so. Because it doesn’t monomorphize everything, release builds of derived code are about 2.3 times as fast as with Serde and that get a tiny bit better in practice for your own code as less recompilation is necessary.
To make Deser’s design work at all, it also uses unsafe internally. Most of
this is to keep the chain of borrowed sinks on the heap. I feel like this is
fine in the days of Miri and agents, but I know it makes some folks uneasy.
And well, the biggest cost is that it’s just not Serde.
Quite a lot actually which might be surprising. In addition to the core there is support for derive.
It supports all flavorts of JSON you can think of: JSON, JSONC, JSON5 and HJSON. (Fun fact here: they are all generated out of one shared parser template) For binary handling it supports CBOR and MessagePack. Additionally it does YAML 1.1 and 1.2, TOML, XML and all three flavors of Apple’s plist as well as CSV/TSV, urlencoded data and environment variables. For more crazy contraptions you can attach path info or capture location data as well as support for debug printing. You can perform validation as you parse, opt into different binary encodings in addition to base64, you can bridge to serde or capture dynamic values, transcode between formats or hook it up with tokio.
For documentation see docs.rs/deser and the code itself is on GitHub alongside many examples.
Julia Evans 27/09/2026 | Source: Julia Evans
Hello! Recently I needed bike lights for my bike. And I remembered that I already had rechargeable bike lights that I bought ten years ago, that I hadn’t tried in a long time. I tried to recharge them, but after fully charging them, they only worked for maybe 5 minutes before they turned off again.
I don’t know much about electronics, but I’ve been curious about whether it’s possible to fix old electronics for a long time, and this seemed like the perfect repair project because I might just need to replace the battery.
So I went to the local queer makerspace where I’m a member to use the soldering iron and try to do it! I don’t know much about electronics and this post does not contain any safety advice because I don’t know much about safety. I think it’s nice to do projects in a community space where you can get help.
The bike light felt like it was made of silicone, so I cut open the silicone in a haphazard way along something that vaguely looked like a seam.
I definitely ripped some silicone in the process and it was pretty messy but I got it open and found the circuit board.
I don’t know the model number of the bike lights but there’s a photo of them at the end of the post.
There were some screws attaching things together so I removed them so I could get the circuit board out.
Mostly I tried to remove as few screws as possible because I was worried about losing them or not being able to put them back after. I probably put the screws in a bag or something.
I took out the circuit board. Here’s what it looked like:
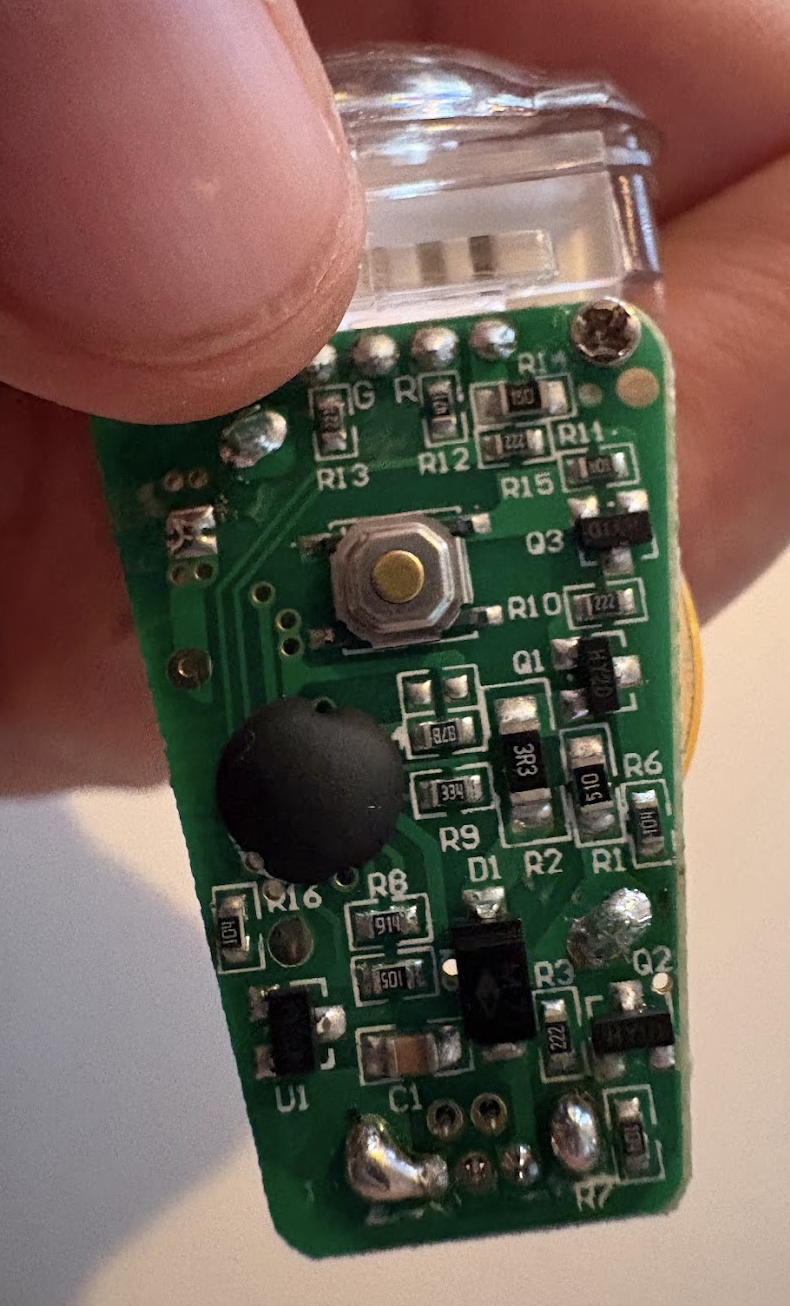
You can see where the battery is attached, I think it’s left of RI3 and above Q2.
Here’s what the battery looked like:
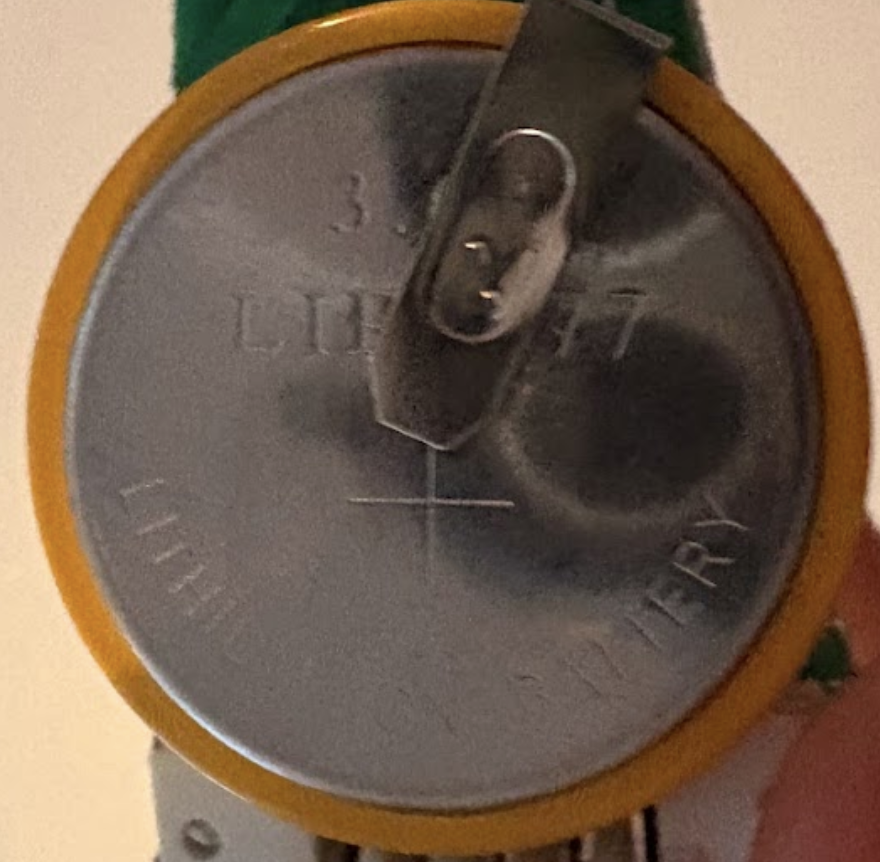
I’d never desoldered anything before, so I found the iFixit guide to desoldering and read it. Also I asked my friends Lee and Lauria for advice.
Here were the steps I ended up following based on the guide & the advice I got:
In the picture of the battery in Step 3, you can see it says something like “3” and “LI???77”. There’s a piece of metal that I think is welded or something to the top of the battery. It seemed impossible and also maybe not smart to try to remove so I wasn’t sure how to find out what an “LI????77” was or how to order another one.
I’ve been trying to avoid using LLMs (though I will not get into that because I am exhausted by LLM discourse and I’m sure you are too), but I really had no idea how to figure out what the battery was so I asked an LLM. It gave the response “LIR2477”, which (when I looked it up) looked exactly the same as my battery so I figured that was plausible.
I would be interested to learn non-LLM ways to figure this out though. There must be a way. Lauria showed me how to use DigiKey’s search which was very cool though DigiKey didn’t have that part.
(edit: someone in the replies told me that this kind of coin cell battery is named according to its dimensions, and you can use plastic calipers to measure the dimensions of the battery. So I guess a non-LLM way would be to measure the battery with calipers and try to match it to something on the List of battery sizes Wikipedia page, though that page only mentions CR 2477 and not LIR 2477. It’s a good example of what’s fun for me about trying to avoid LLMs, this “List of battery sizes” page is super interesting and if I use an LLM I might never find it)
I went to AliExpress and ordered:
I think the batteries were $3 each and the glue was $8.
The parts took maybe 2 weeks to arive, and once they arrived, I went back to the makerspace and:
Then after waiting some amount of time for the glue to dry I took it home and waited 24 hours for the glue to cure.
Also I took the old batteries to somewhere nearby that accepts old batteries.
The lights work! I have used them to bike at night! I still haven’t needed to recharge them (and tragically I had to order a new Mini USB cable because I got rid of all my Mini USB cables, so I’m still waiting for that), so I still don’t know for sure how long the lifetime of the new battery will be.
Here’s what the light looks like after re-gluing. You can see that I didn’t glue very carefully. It didn’t really go back together that well but I’m hoping it’ll be good enough.
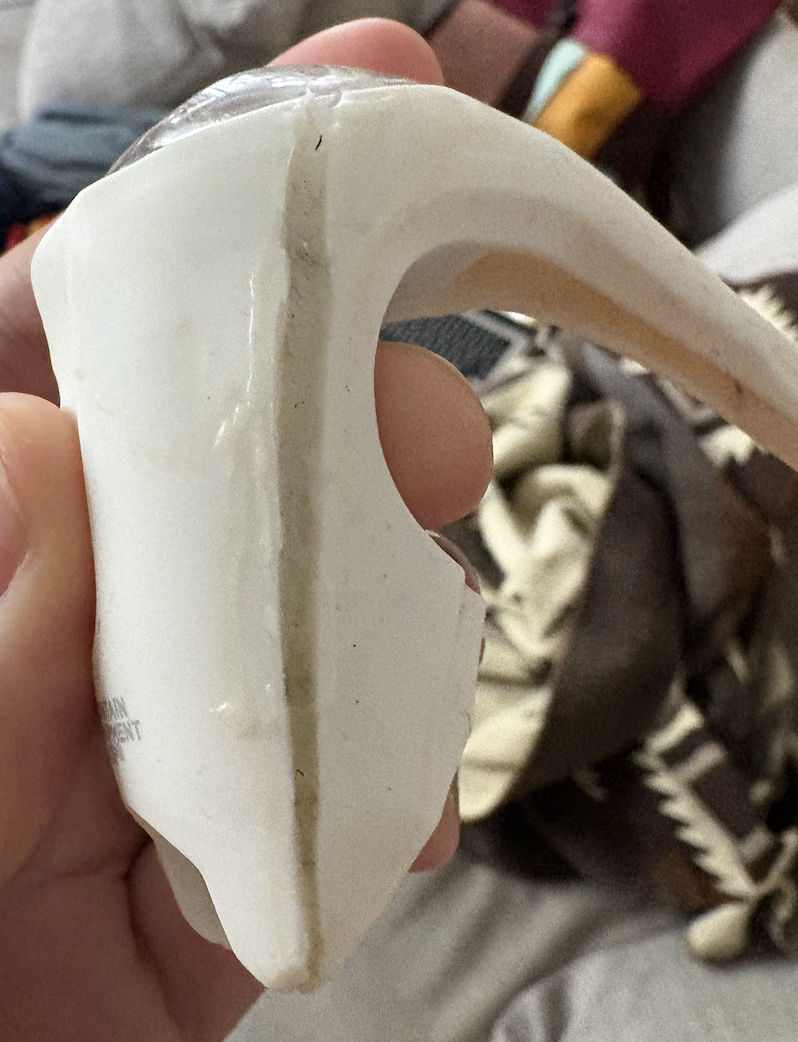
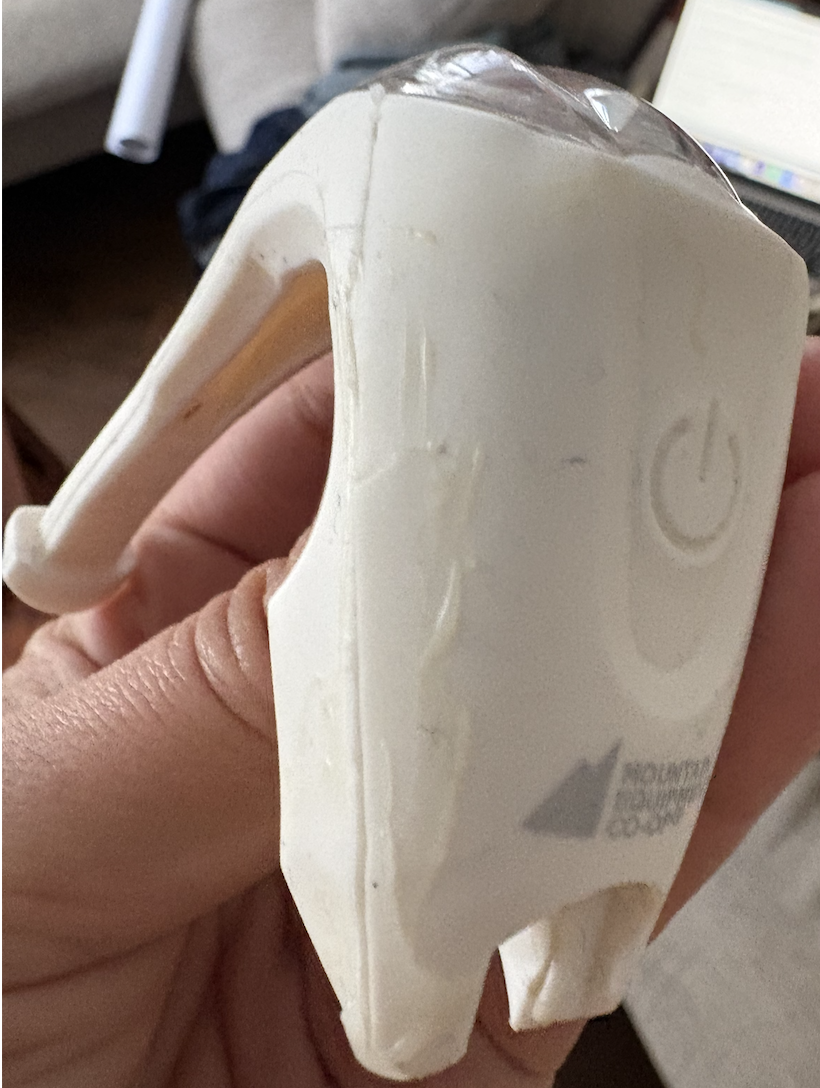
I thought it was really cool that I was able to do this with extremely minimal electronics skills! It cost about $20 CAD to buy the parts, and (whether or not the repair holds up, I’ll try to update this post in the future!), it was fun to try to repair something and learn something new.
Ken Shirriff 26/09/2026 | Source: Ken Shirriff's blog
I hope you're not tired of the 8087, because I have another article about Intel's floating-point chip.1 In 1980, Intel introduced the 8087, making floating-point operations much faster in the IBM PC and other systems. In this article, I look at the algorithm behind the chip's tangent instruction. One popular approach for trigonometric functions is an algorithm called CORDIC. Another approach is a polynomial approximation. The 8087 combined the two to obtain both high accuracy and high performance. The 8087 provided an enormous speedup over the 8086 microprocessor, computing a tangent in 90 microseconds rather than 13,000 microseconds.2
By examining the circuitry and microcode of the 8087,
I can explain the algorithm behind the tangent instruction, called FPTAN.
To explore the 8087's circuitry, I popped the lid off a chip with a chisel
and created a high-resolution image with a microscope.
The microcode ROM is the large rectangular region in the center of the die, holding the 1648 micro-instructions that control the chip.
The bottom half of the chip (red box) is the datapath, the circuitry that performs floating-point calculations on 80-bit values.3
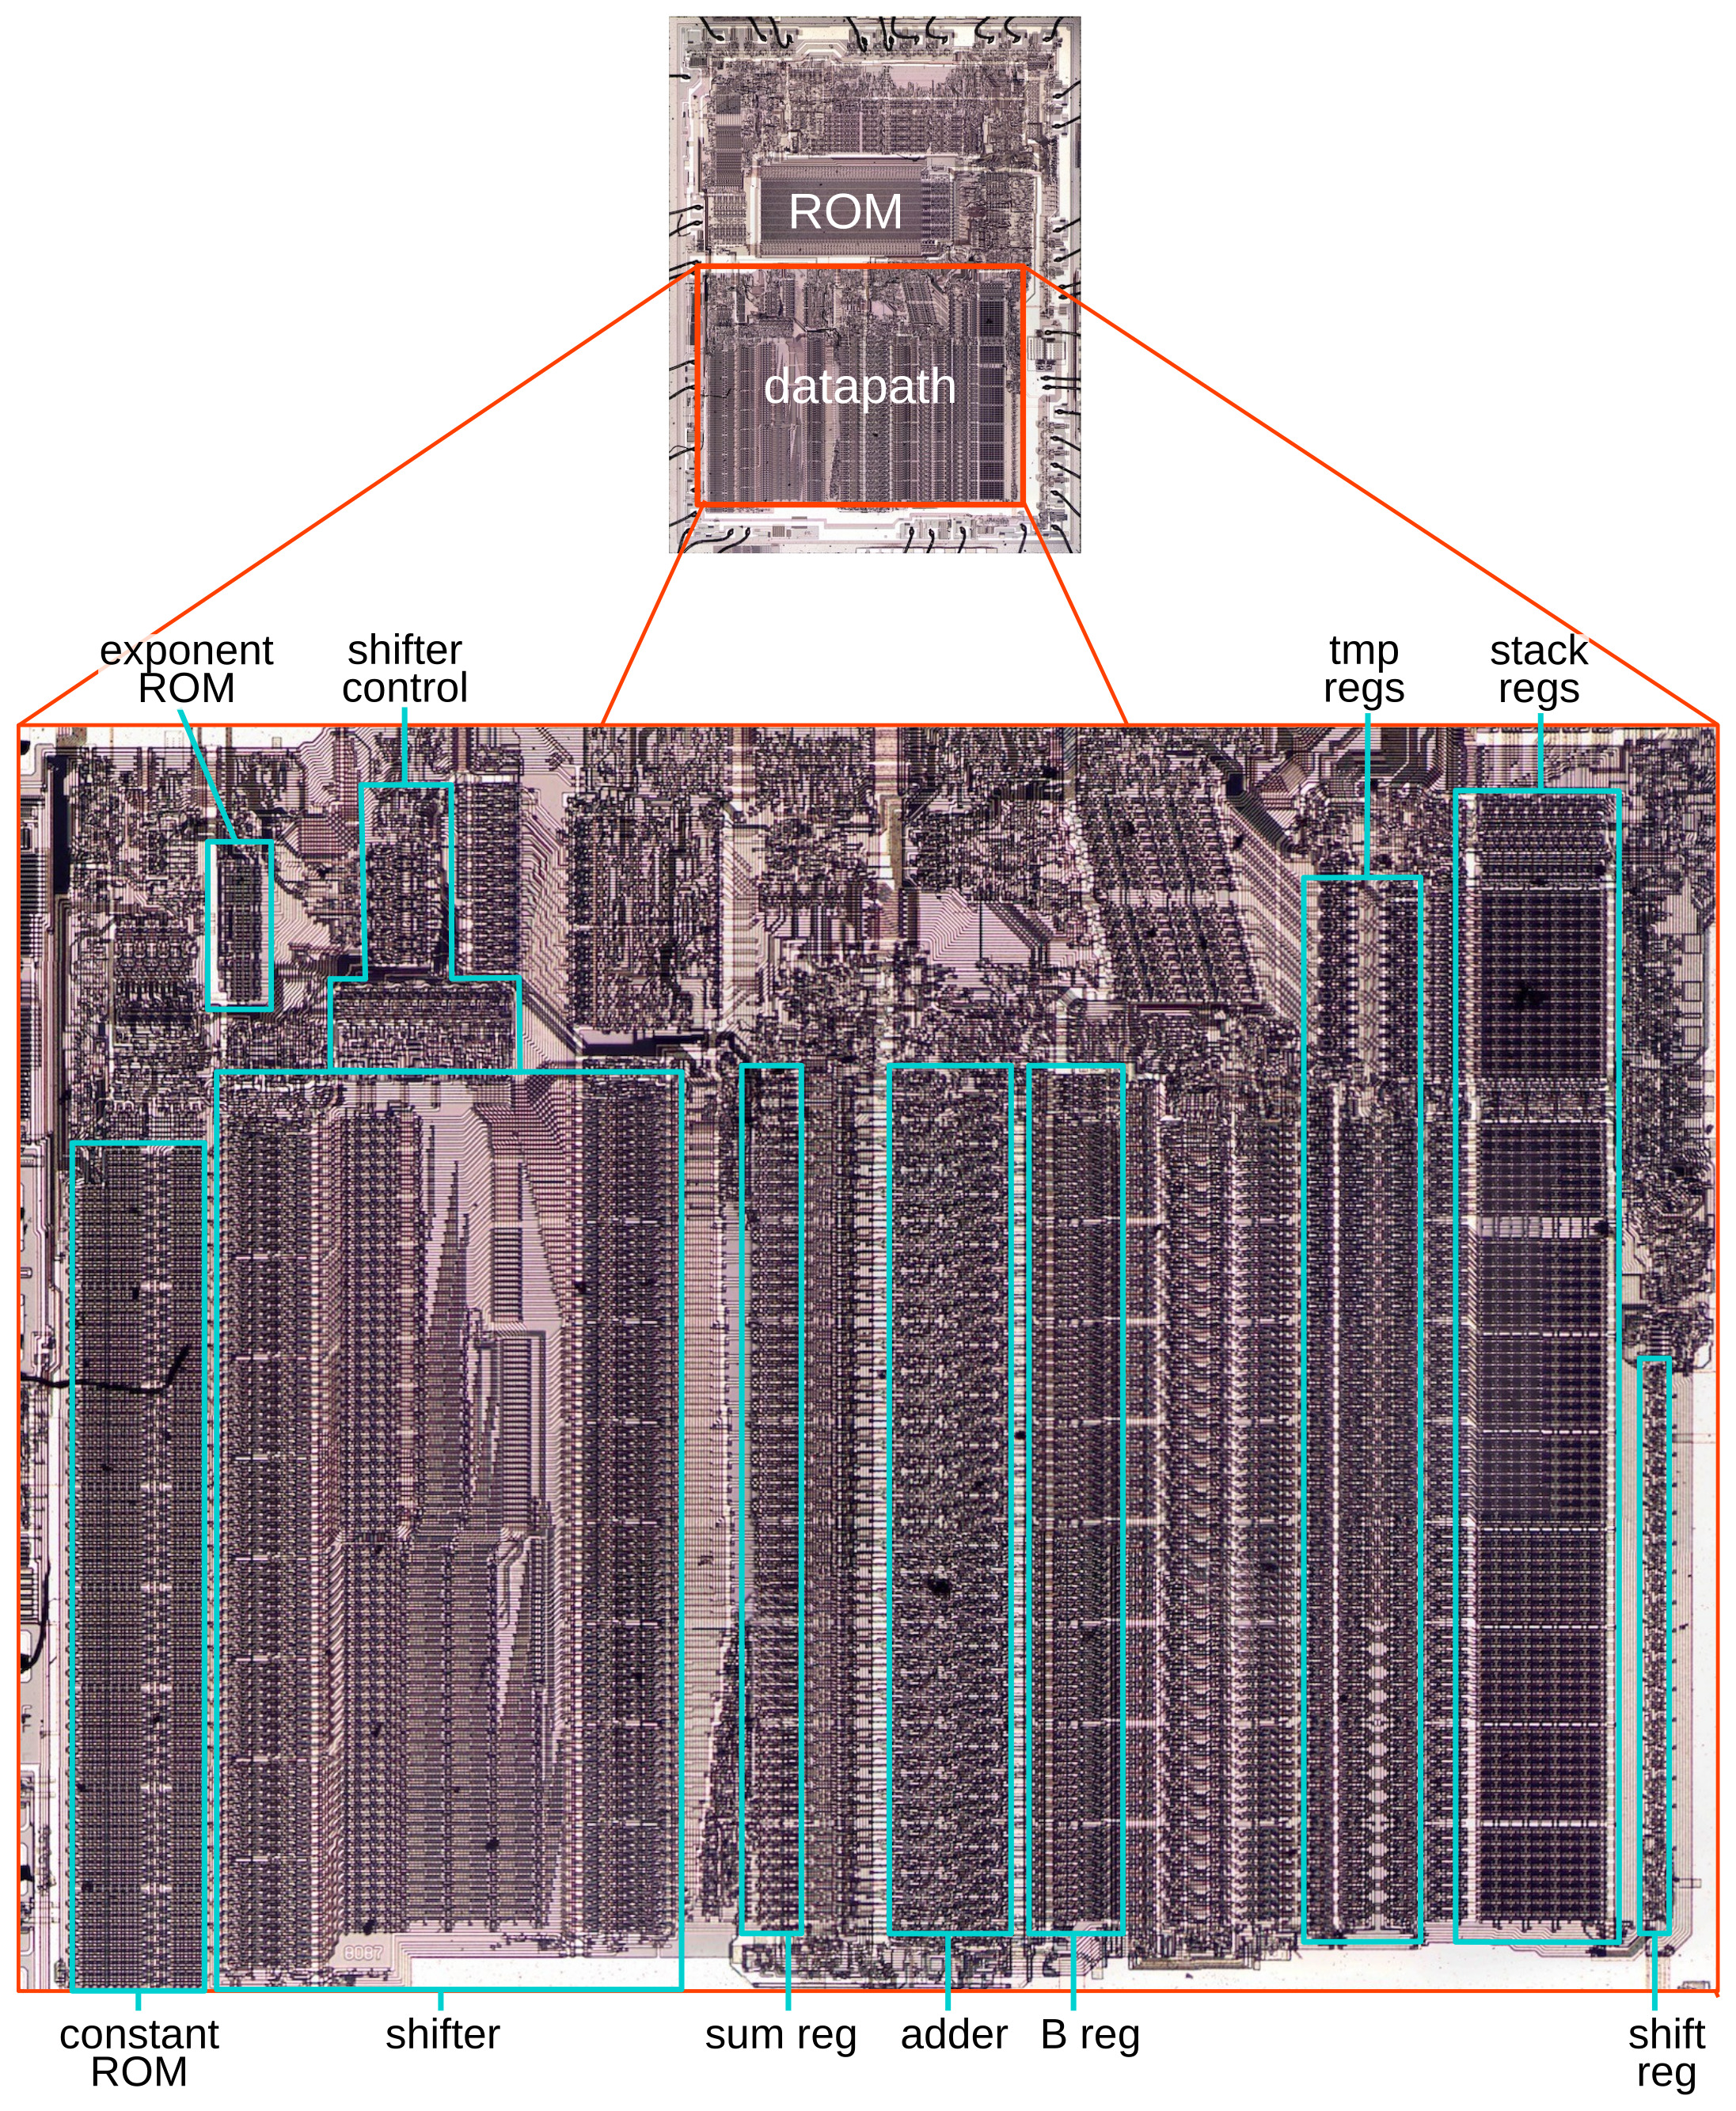
FPTAN. Click this image (or any other) for a larger version.Zooming in on the datapath shows the relevant functional units. The exponent ROM holds fixed exponent values that the algorithms need. The constant ROM holds constants, including the constants used by the CORDIC algorithm. The shifter is a large component; it shifts a 64-bit value left or right by arbitrary amounts. The adder is the heart of the 8087's calculations; as well as providing addition and subtraction, it is used in a loop for multiplication, division, and square roots. The B register holds one input to the adder, while multiple sources can provide the other input. The sum register holds the adder's output. The eight stack registers and the temporary registers hold floating-point numbers. Finally, the shift register holds 16 status bits for the CORDIC calculations.
CORDIC is a clever algorithm for quickly computing transcendental functions with simple hardware: it uses shift and add instructions along with table lookups, but doesn't need multiplication or division. This algorithm dates back to 1956, when it was developed for the B-58 Hustler, the first bomber capable of flying at Mach 2. The aircraft had an analog navigation computer, but analog components provided limited accuracy. Engineer Jack Volder was given the task of designing a digital computer to replace the analog computer.7 One key problem was that an analog computer can easily generate sines and cosines with an electromechanical device called a resolver. But trigonometric functions are difficult to produce digitally, especially with the slow transistors of that era.
Jack Volder came up with a fast way to calculate trigonometric functions with simple hardware. He called the algorithm—and the computer that implemented it—CORDIC: "COordinate Rotation DIgital Computer". CORDIC converts an angle to a vector, where the vector's coordinates provide the necessary trig functions. The trick is to break down the angle into a sequence of special angles, angles that make vector rotation easy. These special angles are precomputed and stored in a table, so the CORDIC calculation can be performed quickly, even on 1950s hardware. Each CORDIC iteration provides an additional bit of accuracy, so the algorithm converges rapidly. CORDIC became popular, including in scientific calculators, which used decimal CORDIC instead of binary.
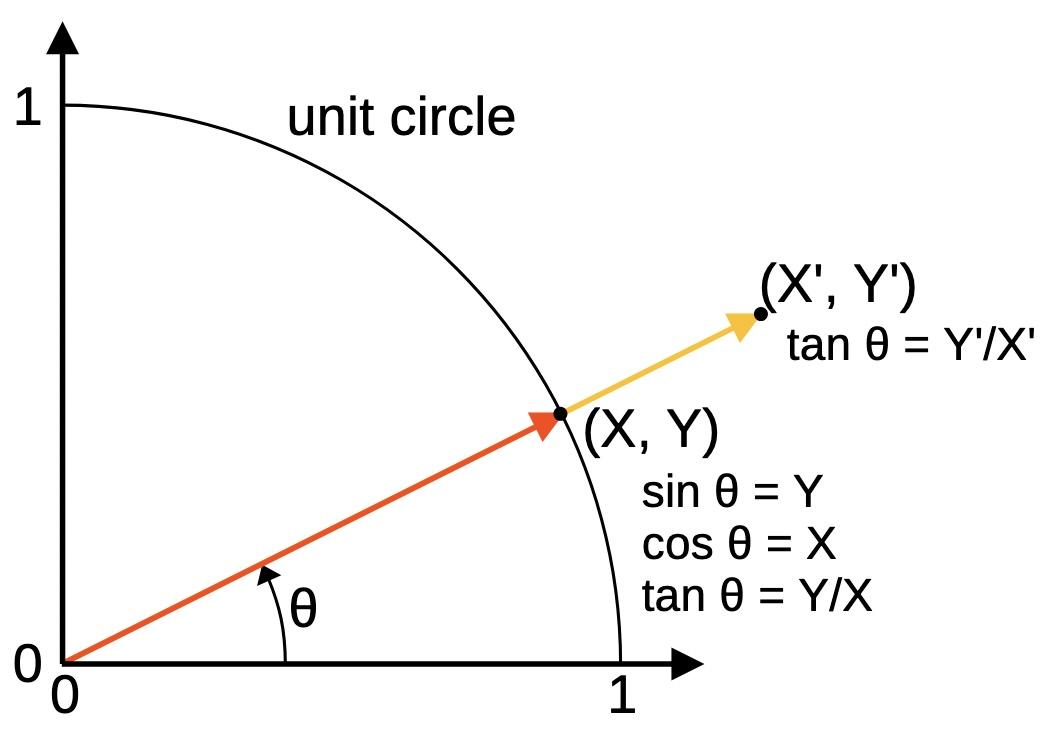
I'll try to keep the math to a minimum, but in this section I'll give a quick explanation of how CORDIC works. The diagram below reviews how trig functions are related to the coordinates of a point. Suppose you have an angle θ; it specifies a point (X, Y) on the unit circle. The basic formulas are X=cos θ, Y=sin θ, and Y/X = tan θ. Thus, if you can determine the coordinate (X, Y), then you can determine the value of the trig functions. If the point is not on the unit circle, e.g. (X', Y'), then you can still easily determine tan θ. (Spoiler: this is what the 8087 does.) However, sin θ and cos θ become messy.4
If you've done any computer graphics, you've probably seen how a rotation matrix can rotate a point by an angle. (If you're not familiar with rotation matrices, you can read about them here or just trust that it works.) Multiplying a point (X, Y) by the rotation matrix yields the new point (X', Y') as shown below.
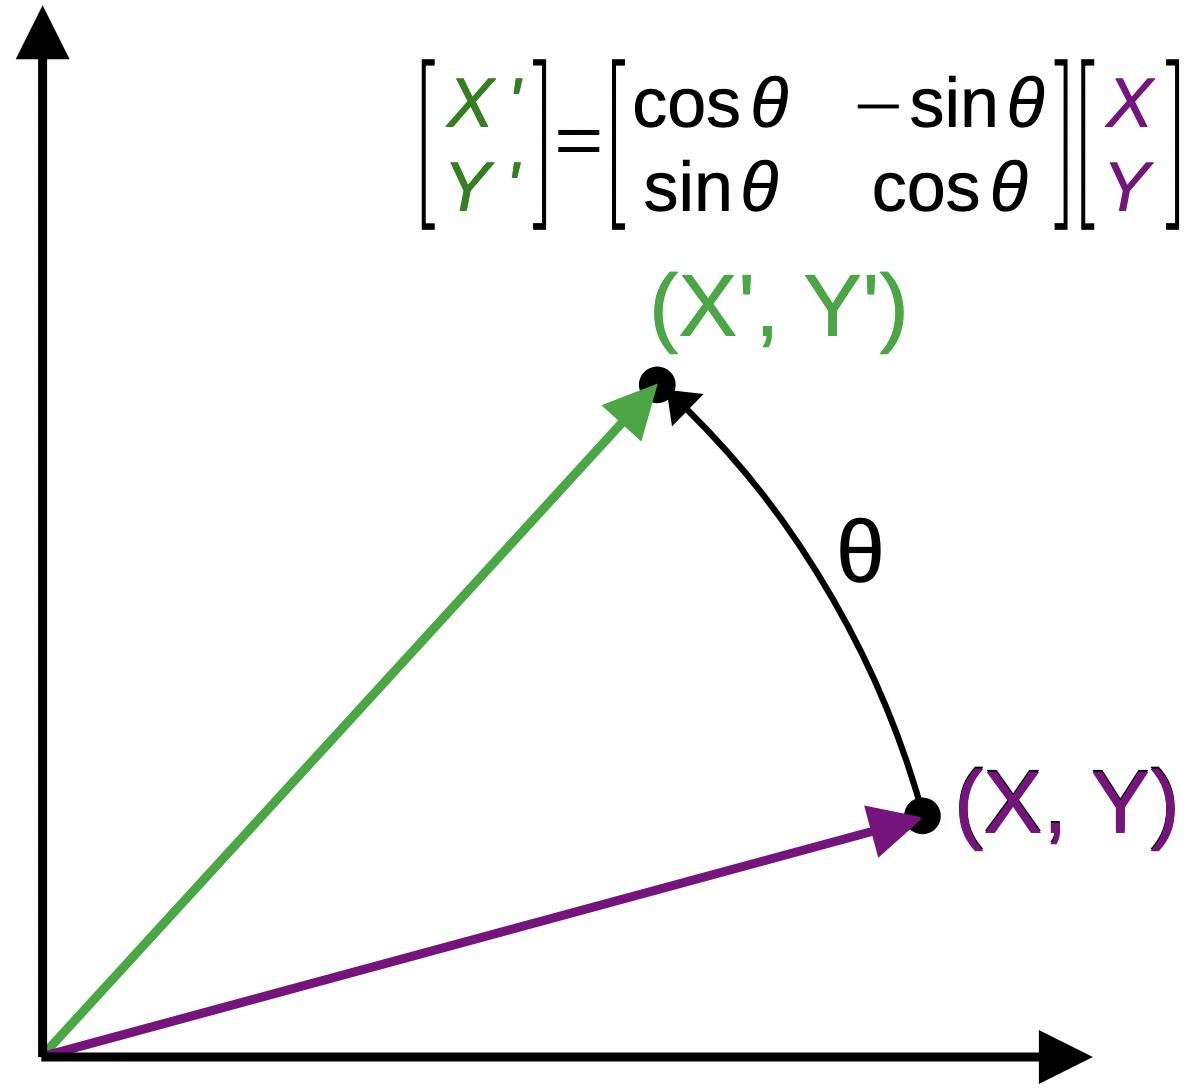
Unfortunately, since the rotation matrix (1, below) requires sin and cos, it doesn't seem like it helps solve our problem. However, we can divide the matrix by cos θ; this seems even less helpful since now the matrix (2) needs tan, which is what we want to evaluate. (Moreover, the vector's length will grow.) But the key to CORDIC is to use special angles, αn = arctan(2-n). When we substitute one of these special angles into the matrix, we get matrix (3), which is easy to evaluate in hardware: multiplying by a power of 2 can be done by shifting the bits.
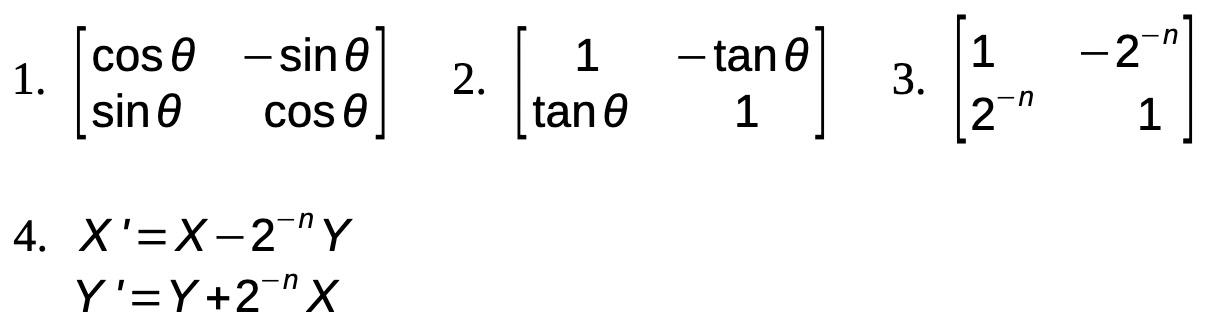
Applying matrix (3) to the point (X,Y) gives the equations (4). These are key equations for the CORDIC process. The important thing is that these equations are fast and easy to compute in machine language or hardware, as the only operations are addition, subtraction, and binary shifting.
With that background, we can see how CORDIC works. First, we break down the desired input angle into a combination of special angles that adds up to the desired angle.5 Then we apply the rotation formula above for each special angle, starting with the unit vector (1, 0). The result is a point (X, Y) at the desired angle, and then the desired tangent is simply Y/X.6 Since the table of special angles is precomputed, the arctan operations don't slow down the process. As an aside, after the first few terms, the special angles approach 2-n, so they shrink by roughly a factor of 2 at each step.
To summarize, the CORDIC algorithm consists of looping through a table of stored angles. If the stored angle is less than the desired angle, the stored angle is subtracted from the desired angle to yield a new desired angle and the equations above (shifts, add, and subtract) are applied to yield a new vector. At the end, the tangent of the original angle is given by Y/X.
The accuracy of CORDIC depends on the number of terms that are used. With 16 terms, the accuracy is approximately 2-16, or 16 bits of accuracy. To get 64 bits of accuracy would require calculating 64 terms (and a table of 64 special angles). To get an answer faster, the 8087 uses 16 bits of CORDIC and uses another algorithm for the remaining angle. (The remaining angle is the gap between the sum of special CORDIC angles and the desired angle, so it is very small, around 2-16.)
For the remaining angle, the 8087 uses a Padé approximant, which is the ratio of two polynomials.
There's a whole family of Padé approximations, depending on the order of the polynomials.
The 8087 uses a simple formula: 3x/(3-x2).8
Although this approximation is simple, it is very accurate for small values; its error is proportional to x4.
Since x<2-16, the error will be less than 2-64, meeting the 64-bit accuracy
requirement for the 8087.
Moreover, the 8087 doesn't need to perform the division in the rational polynomial since
FPTAN returns a separate numerator and denominator. Thus, the division is "free".
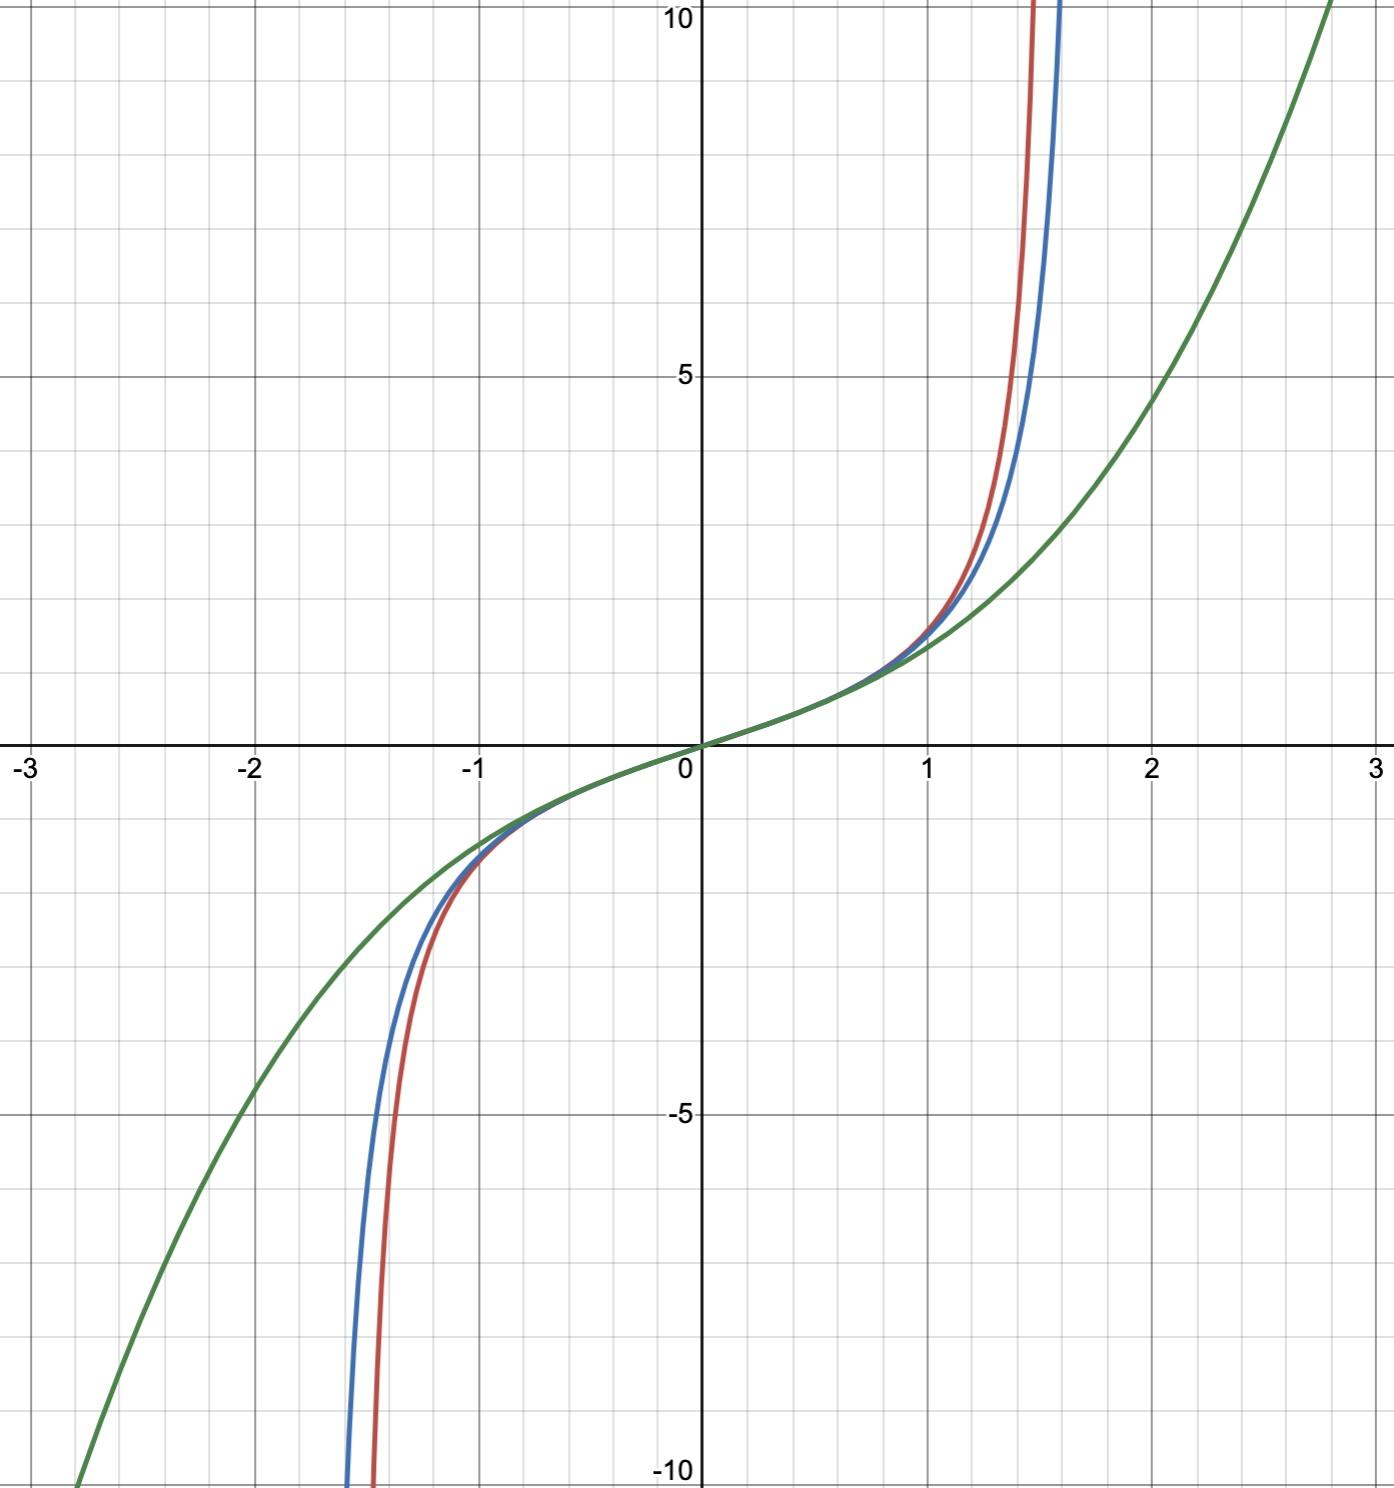
If you've studied calculus, you might think that a Taylor series polynomial is the way to go, but the ratio of two polynomials is better. (One reason is that tangent blows up to infinity at π/2. A polynomial won't blow up, but the ratio of polynomials can, so it fits the tangent function better.) The graph above compares the tangent function (red), the rational approximation (blue), and the third-order Taylor series (green).
The 8087's tangent algorithm has three parts: determining the CORDIC decision bits (called pseudo-division), computing the rational approximation, and applying the rotation equations based on the CORDIC decision bits (called pseudo-multiplication).
In more detail, the first step determines which special angles to add to approximate the input angle. Each special angle is compared to the remaining input angle and subtracted if it is smaller. If the angle is subtracted, a 1 is recorded; otherwise, a 0 is recorded. Since this process is similar to how long division subtracts (or doesn't subtract) successive shifted versions of the divisor, generating 1s or 0s for the quotient, the process is known as pseudo-division. Note that the rotations are not applied in this step. Instead, this step decides which rotations to apply later.
The diagram below shows this process applied to the input angle 0.95 radians.10 The process generates the sequence of bits [1,0,0,1,0,1,0,1,0,0,1,0,0,1,1,1], where the leftmost bit indicates arctan(20) and so forth. The angle is reduced by roughly a factor of 2 at each step, so the residual angle is very small.
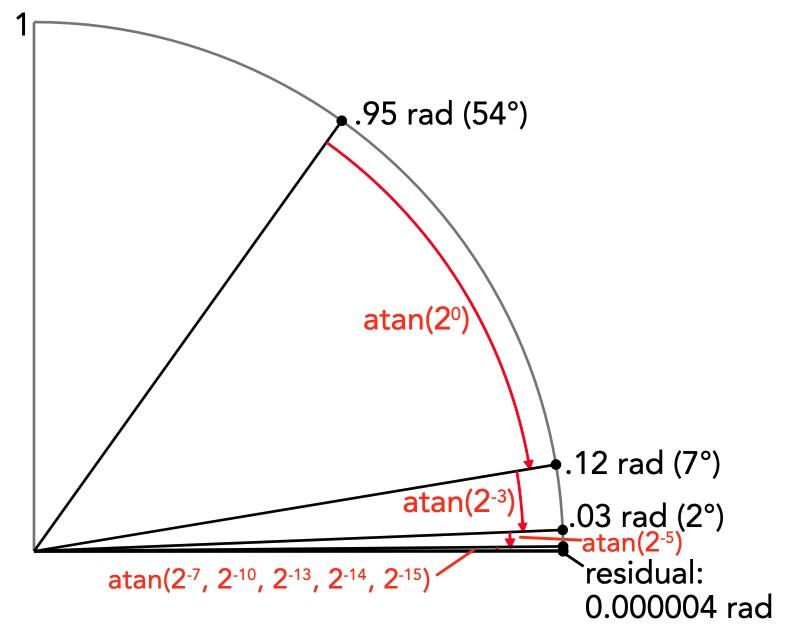
Next, the tangent of the remaining angle is calculated with the rational approximation function, 3x/(3-x2). The result is used as the initial vector for the next step. The division is not performed here; instead, the numerator becomes Y in the initial vector and the denominator becomes X. Thus, the expensive division step is avoided, since it happens implicitly in the answer. Multiplying by 3 is easy (shift left and add), so the only expensive operation at this step is squaring the angle, which requires a full 64-bit multiplication.
The final step applies each CORDIC rotation if the corresponding decision bit from the first step is 1. Since this is somewhat analogous to binary multiplication, which adds the multiplicand at each step if the multiplier bit is 1, this step is known as pseudo-multiplication. As described earlier, each rotation is computed with shifts, addition, and subtraction, so each rotation is inexpensive. Each rotation in this step corresponds to an angle reduction in the first step. The rotations are applied in reverse order—the smallest one first—to reduce rounding error. To accomplish this, the decision bits are stored in a 16-bit shift register in the first step, and shifted out in opposite order in this step.
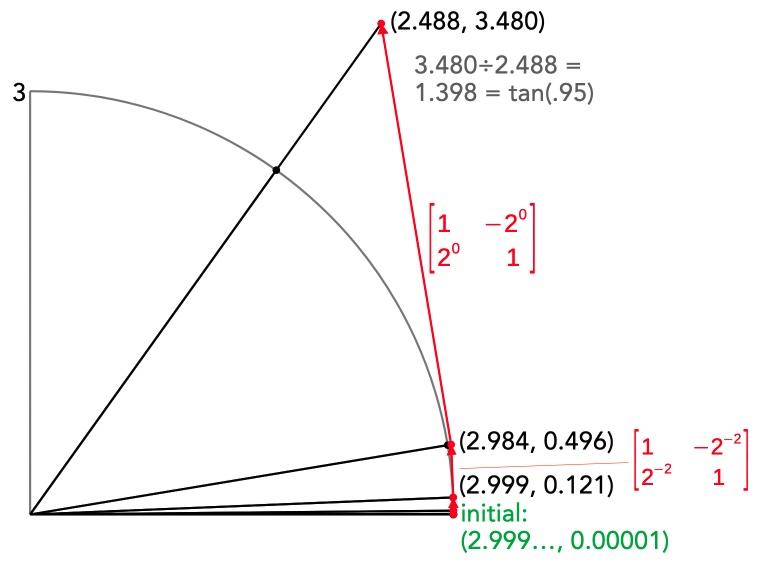
The diagram above shows the process applied to the input 0.95. The initial vector (green) comes from the rational approximation function; it is very close to (3, 0), but slightly rotated due to the tiny residual angle. Each rotation step generates a new vector that matches the angle from the corresponding step in the first part; I show two of the rotation matrices. Note that the vectors diverge from the circle—a consequence of dividing each matrix by cos θ—but this doesn't affect the tangent.
The FPTAN instruction is somewhat peculiar as it doesn't return the tangent directly.
Instead, it returns the Partial Tangent: the two coordinate values
(X and Y) that can be divided to produce the tangent.
One might wonder why the chip didn't do the division automatically.
The motivation was that division
was slow back then, and omitting the division allowed for optimizations in some cases.
In this section, I'll explain some features of the 8087 that are important for the microcode implementation of FPTAN.
The 8087 supports a variety of data types,
but internally, everything is stored as an 80-bit floating-point number called a "temporary real".
A number has three parts: a sign bit, a 15-bit exponent, and a 64-bit significand (the fractional part),
In most cases, a floating-point number is represented by sign × significand × 2exponent.
The advantage of floating-point numbers is that the exponent allows them to cover a huge range, from very small to very large.
The significand is a 64-bit binary number of the form 1.bbb…:
a leading 1, followed by the binary point (the binary equivalent of the decimal point) and the rest of the bits.11
One important detail is that the exponent is stored with a "bias" of 16383 added to it. Thus, the stored exponent is always positive, even if the real
exponent is negative. For instance, an exponent of 1 is stored as 0x4000, and an exponent of -16 is stored as 0x3fef.
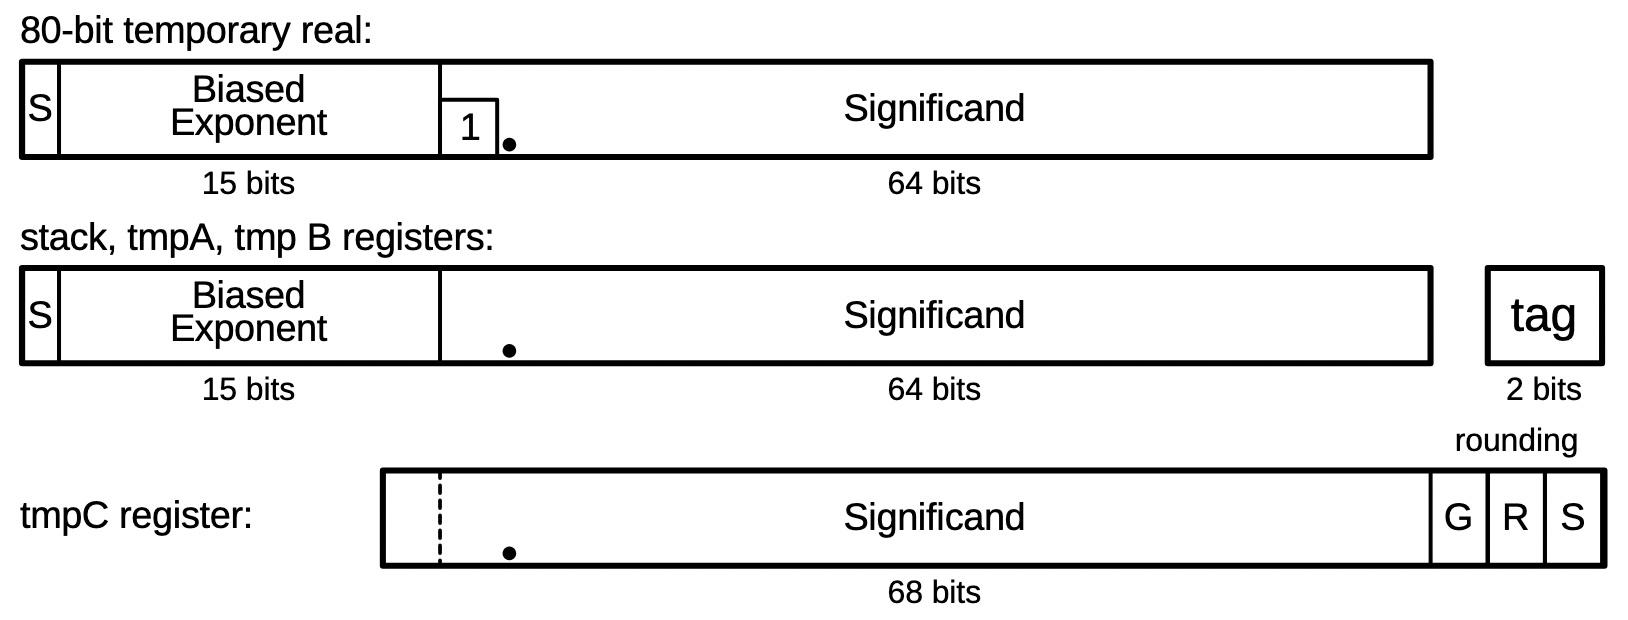
To use the 8087, a programmer stores values in its eight internal registers, organized as a stack. Each register holds an 80-bit floating-point number. To optimize performance, each value in the register stack also has an associated "tag" value: zero, valid, special, or empty. A value of zero is tagged as zero. A "normal" floating-point value is tagged as valid. If the value is infinity, Not a Number (NaN), or a denormalized value, then it is tagged as special. Finally, an empty tag indicates that a register does not hold a value; this allows detection of stack underflow (reading an empty register) or stack overflow (storing to a non-empty register).
The 8087 also has temporary registers that it uses internally: tmpA, tmpB, and tmpC.
(These registers are heavily used for the tangent calculation.)
tmpA and tmpB are 80-bit registers, along
with two tag bits.
However, tmpC is different: it doesn't have a sign, exponent, or tag.
Moreover,
the significand is 68 bits; tmpC has an additional
bit to prevent overflow and three additional low-order bits for rounding, known as
guard, round, and sticky.
In the microcode, each 16-bit micro-instruction performs one low-level operation. Many of the operations move data from one register to another. Other operations provide conditional jumps, subroutine calls, and returns. A bit shift operation takes two micro-instructions: the first moves a value to the shifter and configures the direction and amount of shift. The second micro-instruction (which may be a distance after the first) moves the result from the shifter to a destination.
Similarly, addition takes two micro-instructions. The first micro-instruction
specifies the first argument to add and selects various options such as
carry and rounding.
(For subtraction, an option complements the second argument.)
The second argument always comes from the B register, which confusingly is
unrelated to the tmpB register.
The second micro-instruction moves the result from the sum register to a destination.
In this section, I'll discuss some highlights of the tangent microcode. The listing below shows the 8087's microcode, along with my comments. Each line indicates a 16-bit micro-instruction. The control flow is a bit complicated, so I've put a flowchart in the footnotes.12
FPTAN:
#1039 st(0) -> tmpA        store argument in tmpA
#1040 stackPtr--           check if room on stack to push result
#1041 stack overflow?
#1042 jmp #1022 if tmp empty/special/overflow/div exit if bad argument or stack overflow
#1043 jmp #1045 if tmpA:tag ZERO is argument 0?
#1044 except:precision     precision exception except for 0
#1045 expconst 0x3ff0      Test if exponent >= -16
#1046 adder: tmpA:exp + 0 cin=1 argument exponent + 1
#1047 expConst -> Breg
#1048 adder: sumreg:frac - Breg cin=1 subtract -15
#1049 jmp #1061 if adder pos CORDIC if exponent >= -16
#1050 expconst 0x3fff      non-CORDIC path:
#1051 tmpA:exp -> Breg     check original exponent
#1052 expConst -> tmpB:frac against exponent 0
#1053 adder: tmpB:frac - Breg cin=1 subtract
#1054 sumreg:frac -> expConv 3fff - exp (i.e. -exp unbiased)
#1055 sumreg:frac -> shiftcount
#1056 jmp #1082 if exponent[6:14] != 0 if exp > -64 goto rational approximation
#1057 high bit -> tmpB:frac otherwise return original argument
#1058 expConst -> tmpB:sign,exp push 1 for X (denom): result is orig angle
#1059 tmpB -> st(0)
#1060 RNI
#1061 expconst 0x0010      CORDIC path
#1062 sumreg:frac -> loopcounter loopcounter = exp + 16
#1063 tmpA:frac -> tmpC    tmpC = original angle
#1064 trig const -> Breg/rnd
#1065 adder: tmpC - Breg cin=1, roundmode subtract first CORDIC angle
#1066 adder sign -> cordic, shl save bit  in shift register
#1067 jmp #1079 if not adder pos
#1068 sumreg:frac,rnd -> tmpC
#1069 adder: tmpA:exp + 0 cin=1 increment exp if first angle used
#1070 sumreg:frac -> tmpA:exp
#1071 jmp #1079
#1072 shift tmpC L 0 bytes, 1 bits top of CORDIC scan loop
#1073 shift L -> tmpC      shift angle left
#1074 trig const -> Breg/rnd
#1075 adder: tmpC - Breg cin=1, roundmode subtract CORDIC angle
#1076 adder sign -> cordic, shl save decision bit in shift register
#1077 jmp #1079 if not adder pos
#1078 sumreg:frac,rnd -> tmpC
#1079 jmp #1072 if not const latch zero bottom of CORDIC scan loop
#1080 tmpC -> tmpA:frac    update tmpA, tmpB
#1081 expConst -> shiftcount 16 -> shiftcount (otherwise based on exponent)
#1082 tmpA:frac -> tmpB:frac Padé approximation
#1083 tmpA:frac -> Breg    tmpA = ang
#1084 call SQUARE          square the angle
#1085 shift sumreg:frac R count byte bit
#1086 shift R -> sumreg:frac shift twice to scale square
#1087 shift sumreg:frac R count byte bit
#1088 shift R -> Breg      Breg = ang^2
#1089 1.1 -> tmpB:frac     3 (with exp 1)
#1090 adder: tmpB:frac - Breg cin=0
#1091 sumreg:frac -> tmpB:frac tmpB (X) = 3-ang^2
#1092 shift tmpA:frac R 0 bytes, 1 bits
#1093 shift R -> Breg/rnd
#1094 adder: tmpA:frac + Breg cin=0, roundmode ang + ang/2
#1095 sumreg:sign,frac,rnd -> tmpC tmpC (Y) = 3×ang with appropriate exponent
#1096 expconst 0x3ff0      exponent -15
#1097 expConst -> Breg
#1098 adder: tmpA:exp - Breg cin=1
#1099 jmp #1118 if not adder pos skip if exponent too small
#1100 shift tmpC R 0 bytes, 1 bits CORDIC pseudo-multiplication path
#1101 #15 -> loopcounter
#1102 shift R -> tmpC
#1103 jmp #1113 if not cordic[0] CORDIC: if saved decision bit...
#1104 shift tmpC R loopcount send tmpC (Y) to shifter
#1105 tmpC -> Breg/rnd     send tmpC to adder
#1106 adder: tmpB:frac + Breg cin=0, roundmode tmpB (X) not shifted because tmpC scaled
#1107 sumreg:sign,frac,rnd -> tmpC tmpC = tmpC + tmpB (implicit >>n)
#1108 shift R -> sumreg:frac,rnd shifted old tmpC to sumreg
#1109 shift sumreg:frac,rnd R loopcount shift right again because tmpC scaled
#1110 shift R -> Breg/rnd  and send to B reg
#1111 adder: tmpB:frac - Breg cin=1, roundmode
#1112 sumreg:frac,rnd -> tmpB:frac tmpB = tmpB - tmpC>>n
#1113 cordic shr           shift out shift register bit
#1114 shift tmpC R 0 bytes, 1 bits start shift of tmpC (Y)
#1115 jmp #1118 if cordic==0 done if shift register empty
#1116 shift R -> tmpC      shift tmpC (Y) right
#1117 jmp #1103 if not const latch zero done if counter at zero
#1118 expconst 0x3fff      CORDIC done
#1119 tmpB:frac -> sumreg:frac Test top bit of tmpB (X)
#1120 jmp #1124 if reg bit 63 If set, use exponent 0
#1121 expconst 0x3ffe      Otherwise, use exponent -1 and
#1122 shift sumreg:frac L 0 bytes, 1 bits shift left one bit to normalize
#1123 shift L -> tmpB:frac
#1124 expConst -> tmpB:sign,exp store exponent in tmpB
#1125 tmpC -> tmpA:frac    store tmpC (Y) in tmpA
#1126 tmpC -> sumreg:frac,sign
#1127 jmp #1132 if not sumreg[64] test overflow bit
#1128 shift tmpC R 0 bytes, 1 bits if set, normalize by shifting right
#1129 shift R -> tmpA:frac
#1130 adder: tmpA:exp + 0 cin=1 and increment exponent by 1
#1131 sumreg:frac -> tmpA:exp
#1132 tmpB -> st(0)        tmpB to top of stack: X (denom)
#1133 stackPtr++
#1134 tmpA -> st(0)        tmpA to st(1): Y (numerator)
#1135 stackPtr--
#1136 RNI                  End of FPTAN
The FPTAN microcode starts at address #1039 (decimal).
The microcode starts by moving the argument from the top of the stack to the tmpA register.
If the top value is empty, this indicates a stack underflow. If the next element on
the stack (the position that will hold the result) is not empty, this indicates a stack
overflow. In either case, the microcode indicates an "invalid" exception and ends the instruction.
One peculiar feature of the 8087 is that it flags a result with a "precision" exception if
the result is not exact. (This happens very frequently, even for, say, 1/10.)
The only tangent that the 8087 can compute precisely is tan(0), so all other inputs
result in a precision exception (#1044).
Next, the argument's exponent is tested, splitting the execution into three paths.
If the exponent is -64 or less, the argument is so small that
the tangent equals the argument, within the accuracy of the system.13
In this case (#1057), the original argument is returned unchanged (with the denominator 1 pushed), and the code ends.
The second case is if the argument's exponent is -17 or less. In this case,
the CORDIC step is skipped, and the routine jumps directly to the rational approximation (#1082).
The most interesting case is the CORDIC path (#1061), taken if the exponent is between -1 and -16.
Conceptually, the code performs 16 CORDIC steps, using 16 stored angles.
However, the code is optimized, skipping the large angles for smaller
inputs.
Specifically, the loop counter is initialized based on the
exponent of the input angle (#1062).
The CORDIC pseudo-division loop (#1061-#1080) tests the angles, subtracting ones that aren't too big.14
The decision results are recorded in a 16-bit shift register, located on the far right side of the die. Presumably, this is where the layout had some unused space. Since the shift register is loaded and unloaded serially, it doesn't need access to the internal fraction bus, just two lines to shift the bits in and out, so the shift register could be located in otherwise unused space.
The code is optimized to use 64-bit integer arithmetic rather than floating-point arithmetic. This makes it tricky to understand the code since values must be viewed more as fixed-point numbers with implicit exponents. These exponents are not stored anywhere, but can be determined by analyzing the algorithm. Even the angle constants in the ROM do not have explicit exponents.15 Moreover, the implicit exponents change for each step through the loop to preserve accuracy. Roughly speaking, each cycle of the loop reduces the values by a factor of 2, and the angle constants shrink accordingly. If the values had a fixed exponent, they would end up with 16 leading zeros, wasting precision. But by scaling the values each cycle (with a left shift), the numbers continue to use the full 64 bits. In other words, the hardware is performing fast integer arithmetic, but mathematically you can think of it as fixed-point with exponents that don't physically exist in the chip. See the table in the footnotes16 for details on how the implicit exponents change through the loop.
After the CORDIC pseudo-division loop, the microcode calculates the rational polynomial
approximation (#1082).
The small-angle path rejoins the execution flow here.
The microcode to calculate the polynomial approximation has a few interesting features.
The most time-consuming part is the SQUARE routine, which multiplies a fixed-point number by itself.
Multiplication is complicated, so I'll give the details in a later post.
But in brief, the 8087 uses Booth's Algorithm to
multiply by two bits at a time (radix 4), so it is twice as fast as regular binary
multiplication.
The loop to perform the shifts and adds is implemented in hardware, rather than microcode.
That is, one microcode instruction performs 32 additions: the hardware tests the
bits, does the appropriate add or subtract, updates the loop counter, and loops.
For performance, the shifting is done with specialized shifters, not the 8087's general-purpose
shifter.
Except for the square, the polynomials are calculated with additions rather than multiplications. The constant 3 doesn't come from the constant ROM, but from special-purpose transistors that set the top two bits of the significand; this is usually used to supply an NaN. (If the implicit exponent is 1, this corresponds to 3.) Subtracting the square yields the numerator. For the denominator, the angle is shifted right (i.e. divided by 2) and added to itself. This performs a multiplication by 3 (technically by 1.5, but increasing the implicit exponent to 1 turns this into 3). It would be expensive to divide the numerator by the denominator; instead, the numerator and denominator are used as the initial Y and X values for the following CORDIC steps.
Next is the CORDIC loop where the rotations are applied to the vector (#1100).
The rotations are applied in the reverse order from how they were computed in the first step:
the smallest rotations are applied first to preserve accuracy.
Bits are shifted out of the shift register to indicate if the rotation should be applied or
not. As soon as the shift register is all zeros, the loop stops.
In other words, smaller angles go through the loop just a few times, not the full 16 times.
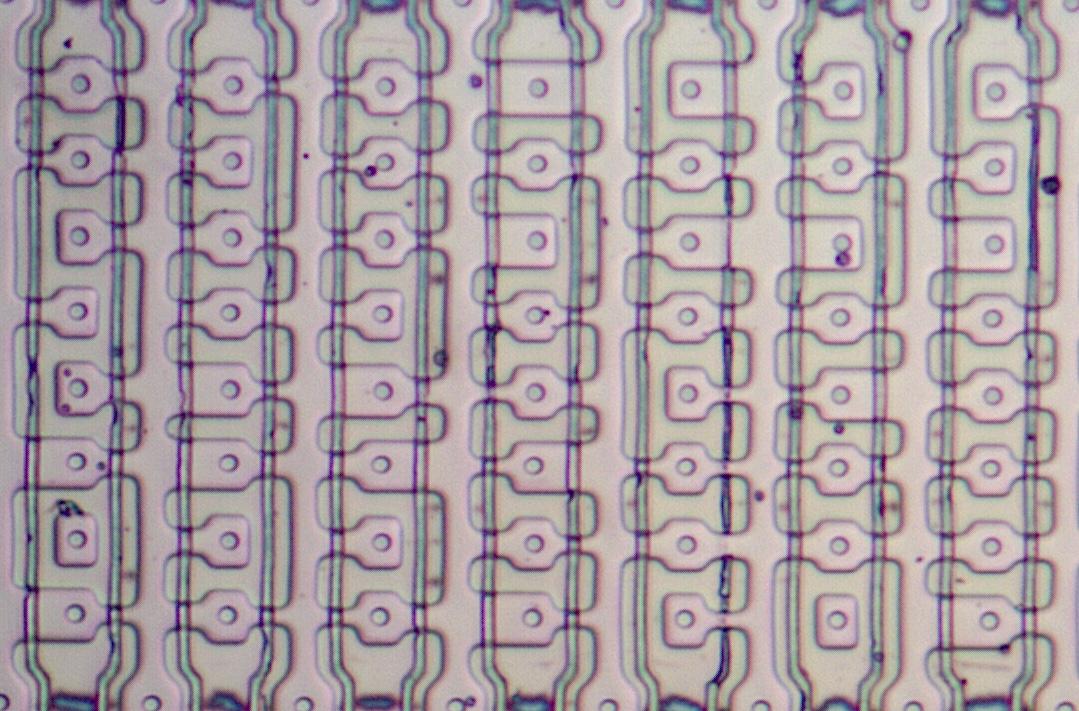
The rotations are applied by shifts and adds (or subtracts), but keeping track of the
implicit exponents is a bit tricky.
Since the vector starts almost horizontal, the X value is approximately 3, and the Y value
is around 2-16.
As the vector rotates, X remains roughly 3, but Y potentially increases by a factor of 2
each time.
To provide the maximum accuracy for each number,
the exponent for X (tmpB) is 1, while the exponent for Y (tmpC) starts off at
-14 and increases by 1 each loop as Y is shifted right.
(Remember that these exponents are not stored anywhere but are implicit.)
Since the two registers have different (implicit) exponents, the values must be shifted
before adding.
The shift amounts aren't intuitive; the table16 in the
footnotes may help clarify.
After the CORDIC loop,
the final part of the code (#1118) normalizes the X and Y values, creating the floating-point
values that are returned from the instruction.
Recall that these aren't "real" floating-point values at this point, so they
may need adjustment.
Specifically, if X doesn't have a
leading 1, it is shifted left one position, while if Y has two leading digits, it
is shifted right one position. In either case, the exponent is adjusted accordingly.
The X and Y values are put on the stack (#1132) to complete the instruction.
The FPTAN instruction is fairly slow as 8087 instructions go, due to its complexity.
The documentation says that it takes typically 450 clock cycles.
(The time has a large range; depending on the value, it can take 30 to 540 clock cycles.)
For the value I examined (0.95), 33% of the time is in the CORDIC
pseudo-division, 15% in the rational polynomial (mostly the squaring operation), 47% in the CORDIC pseudo-multiplication, and 5% overhead.
CORDIC is a popular way to compute trig functions, but there are alternatives such as polynomials. The 8087 is unusual because it combines CORDIC and a rational polynomial. For the Pentium, Intel moved from CORDIC to polynomial approximations; the Pentium's fast multiplication circuitry made polynomials practical. Nowadays, Intel has libraries such as MKL (Math Kernel Library) and Short Vector Math Library (SVML) that provide highly optimized implementations tailored to Intel hardware. These libraries are said to use polynomial approximations, using parallel instructions (SIMD) for performance, rather than specialized hardware. With these libraries, x87 operations and 80-bit floats are mostly obsolete. Nonetheless, I hope you've enjoyed this look at an original 8087 algorithm.
I plan to continue reverse-engineering the 8087 microcode; for updates, follow me on Bluesky (@righto.com), Mastodon (@[email protected]), or RSS. I've been working on this with the members of the "Opcode Collective", especially Smartest Blob and Gloriouscow, who converted the ROM images to microcode data and extensively analyzed the contents. See the 8087 repository on GitHub for more. AI statement: Despite the presence of the em dash, no AI was used in the writing of this article (details). The Opcode Collective used an ML algorithm to classify each ROM cell to extract the microcode.
If you want more on the 8087, here's a list of my previous 8087 posts, newest to oldest:
Microcode in Intel's 8087 floating-point chip: the scale instruction
The adder at the heart of Intel's 8087 floating-point chip
Microcode inside the Intel 8087 floating-point chip: register exchange
Instruction decoding in the Intel 8087 floating-point chip
Conditions in the Intel 8087 floating-point chip's microcode
The stack circuitry of the Intel 8087 floating point chip, reverse-engineered
Die analysis of the 8087 math coprocessor's fast bit shifter
Extracting ROM constants from the 8087 math coprocessor's die
Two bits per transistor: high-density ROM in Intel's 8087 floating point chip
Inside the die of Intel's 8087 coprocessor chip, root of modern floating point
↩
Intel's documentation provides a performance comparison of the 8087 versus floating-point operations emulated on the 8086. The speedup varies depending on the instruction, but is typically almost a factor of 100. This speedup made the 8087 chip highly desirable for numerical applications such as CAD and spreadsheets. ↩
Internally, the 8087 uses 80 bits to hold floating-point values: one bit for the sign, 15 bits for the exponent, and 64 bits for the significand. However, the 8087 uses three extra low-order bits for rounding, called Guard, Round, and Sticky. These bits ensure that a value is always rounded in the right direction. Some parts of the datapath have additional bits for sign or overflow: the shifter is 68 bits wide, and the adder is 69 bits wide. For the most part, I'll ignore these extra bits and refer to the datapath as 64 bits wide. ↩
To compute sin θ from the 8087's X and Y values, the typical formula is sin θ = Y/sqrt(X2+Y2); cos θ is similar. ↩
The special angles (in degrees) are approximately 45°, 26.6°, 14°, 7.1°, 3.6°, 1.8°, 0.9°, … You might wonder if adding up the special angles will always converge to the desired angle θ. A proof can be found here. Note that arctan(2-n) rapidly approaches 2-n (in radians), so it's kind of like a binary fraction expression, cutting the gap approximately in half each time. ↩
The CORDIC implementation in the 8087 is somewhat different from the typical use of CORDIC, which finds sin and cos. In this approach, all the special angles are used, but an angle is either added or subtracted at each step, resulting in convergence to the desired angle. Recall that since the matrix is scaled by 1/sin αi at each step, the ending vector is no longer a unit vector. As a result, cos and sin don't match the final vector (X, Y).
The trick is that if all the special angles are used, the overall scaling factor ends up being the same, simply the product of all the cos αi factors. (It doesn't matter if the rotation is positive or negative because cos αi = cos -αi.) Thus, the overall scaling factor can be precomputed and the initial unit vector can be prescaled by this amount. The result is that the final vector (X, Y) yields (cos θ, sin θ) directly, which is what we want.
The key point is that there are two CORDIC approaches: using positive and negative angles, or using or omitting angles. (The first case multiplies each angle by +1 or -1, while the second case multiplies each angle by 1 or 0.) Most CORDIC implementations use the first approach, while the 8087 uses the second approach. ↩
Jack Volder, the creator of CORDIC, wrote an article, The Birth of CORDIC, that describes the history in detail, as well as including photos of the B-58 navigation computer. Volder's original articles from 1959 are The CORDIC Computing Technique and The CORDIC Trigonometric Computing Technique.
The photo above shows the CORDIC II computer that was used on the B-58 aircraft. It was a 30-bit serial computer, running at 198.4 kHz and weighing a hefty 134 pounds. It was implemented with diode-transistor logic (DTL) gates, using 2498 transistors and 4265 diodes, and had a drum memory (visible at the top) for storage, holding the equivalent of 39 kilobytes. Interestingly, the CORDIC operations were implemented as basic instructions in the instruction set, rather than subroutines; a CORDIC instruction took 5 ms, the same speed as a multiplication or division. ↩
This Padé approximation is called the [1,2] approximation since the numerator is a first-order polynomial and the denominator is a second-order polynomial. Padé approximations can be derived from the continued fraction expansion of tan. See Constructing Padé Approximates.
By the way, if you've taken calculus, you might think that a Taylor series is a good way to approximate a function. Unfortunately, a Taylor series is bad at approximating a function over an interval, rather than a point. You're much better off using a polynomial that minimizes the maximum error over the interval, as in the Pentium. ↩
The valid argument range for FPTAN is documented as 0<θ<π/4, so the demonstration value that I use, 0.95, is outside
the documented range.
I find the range puzzling, since the first CORDIC constant is arctan(1), π/4,
which will only be useful for inputs above π/4.
Thus, the 8087 uses a scarce ROM entry and an extra loop cycle to handle values outside
the permitted range.
I have two hypotheses about this. Perhaps the 8087 was implemented for a larger
argument range, but the numerical error was larger than expected, so the range
was truncated.
Alternatively, the FPATAN arctan instruction might need the first CORDIC constant
and it was easier to use the same constant loop for FPTAN and FPATAN.
(I haven't examined FPATAN yet to confirm this.)
In any case, the code works with 0.95; I use it as an example because
the angles are larger and more visible.
Another peculiarity is that the documentation is inconsistent about whether 0 is
in the range or not. The book The 8087 Primer by
the principal architects of the 8087 and 8086 states that the argument range excludes
0, a decision that was made to simplify the microcode.
However, looking at the microcode (#1044) shows that the code explicitly checks for
a zero input and handles the case.
FPTAN appears to work for values almost up to π/2, with
some accuracy loss as the result approaches infinity near π/2.
However, the values from 1 to π/2 (which are outside the defined range and have an exponent of 0) probably work by coincidence,
not by design.
The larger exponent results in an additional loop iteration;
the lookup of trig constants wraps around the algorithm starts with the last constant, atan(2-15).
But due to scaling, this value ends up being interpreted as approximately 2. Since this CORDIC angle is
greater than π/2, it is skipped.
The algorithm then proceeds with the remaining constants, executing properly.
Footnote to the footnote: Although the mathematical meaning of "range" is the output of a function, Intel uses it to describe the input of a function, which mathematicians call the domain. ↩
One difference between the 8087's temporary real format and the external formats is that in the temporary real, the leading 1 digit is explicitly stored in the number. In the external formats, the leading 1 is implicit and not stored in the number, providing one additional bit of accuracy, but making arithmetic more complicated. ↩
The flowchart below shows the control flow for the FPTAN microcode.
The main blocks are the CORDIC pseudo-division, the rational approximation,
and the CORDIC pseudo-multiplication. (Click it for a large image.)
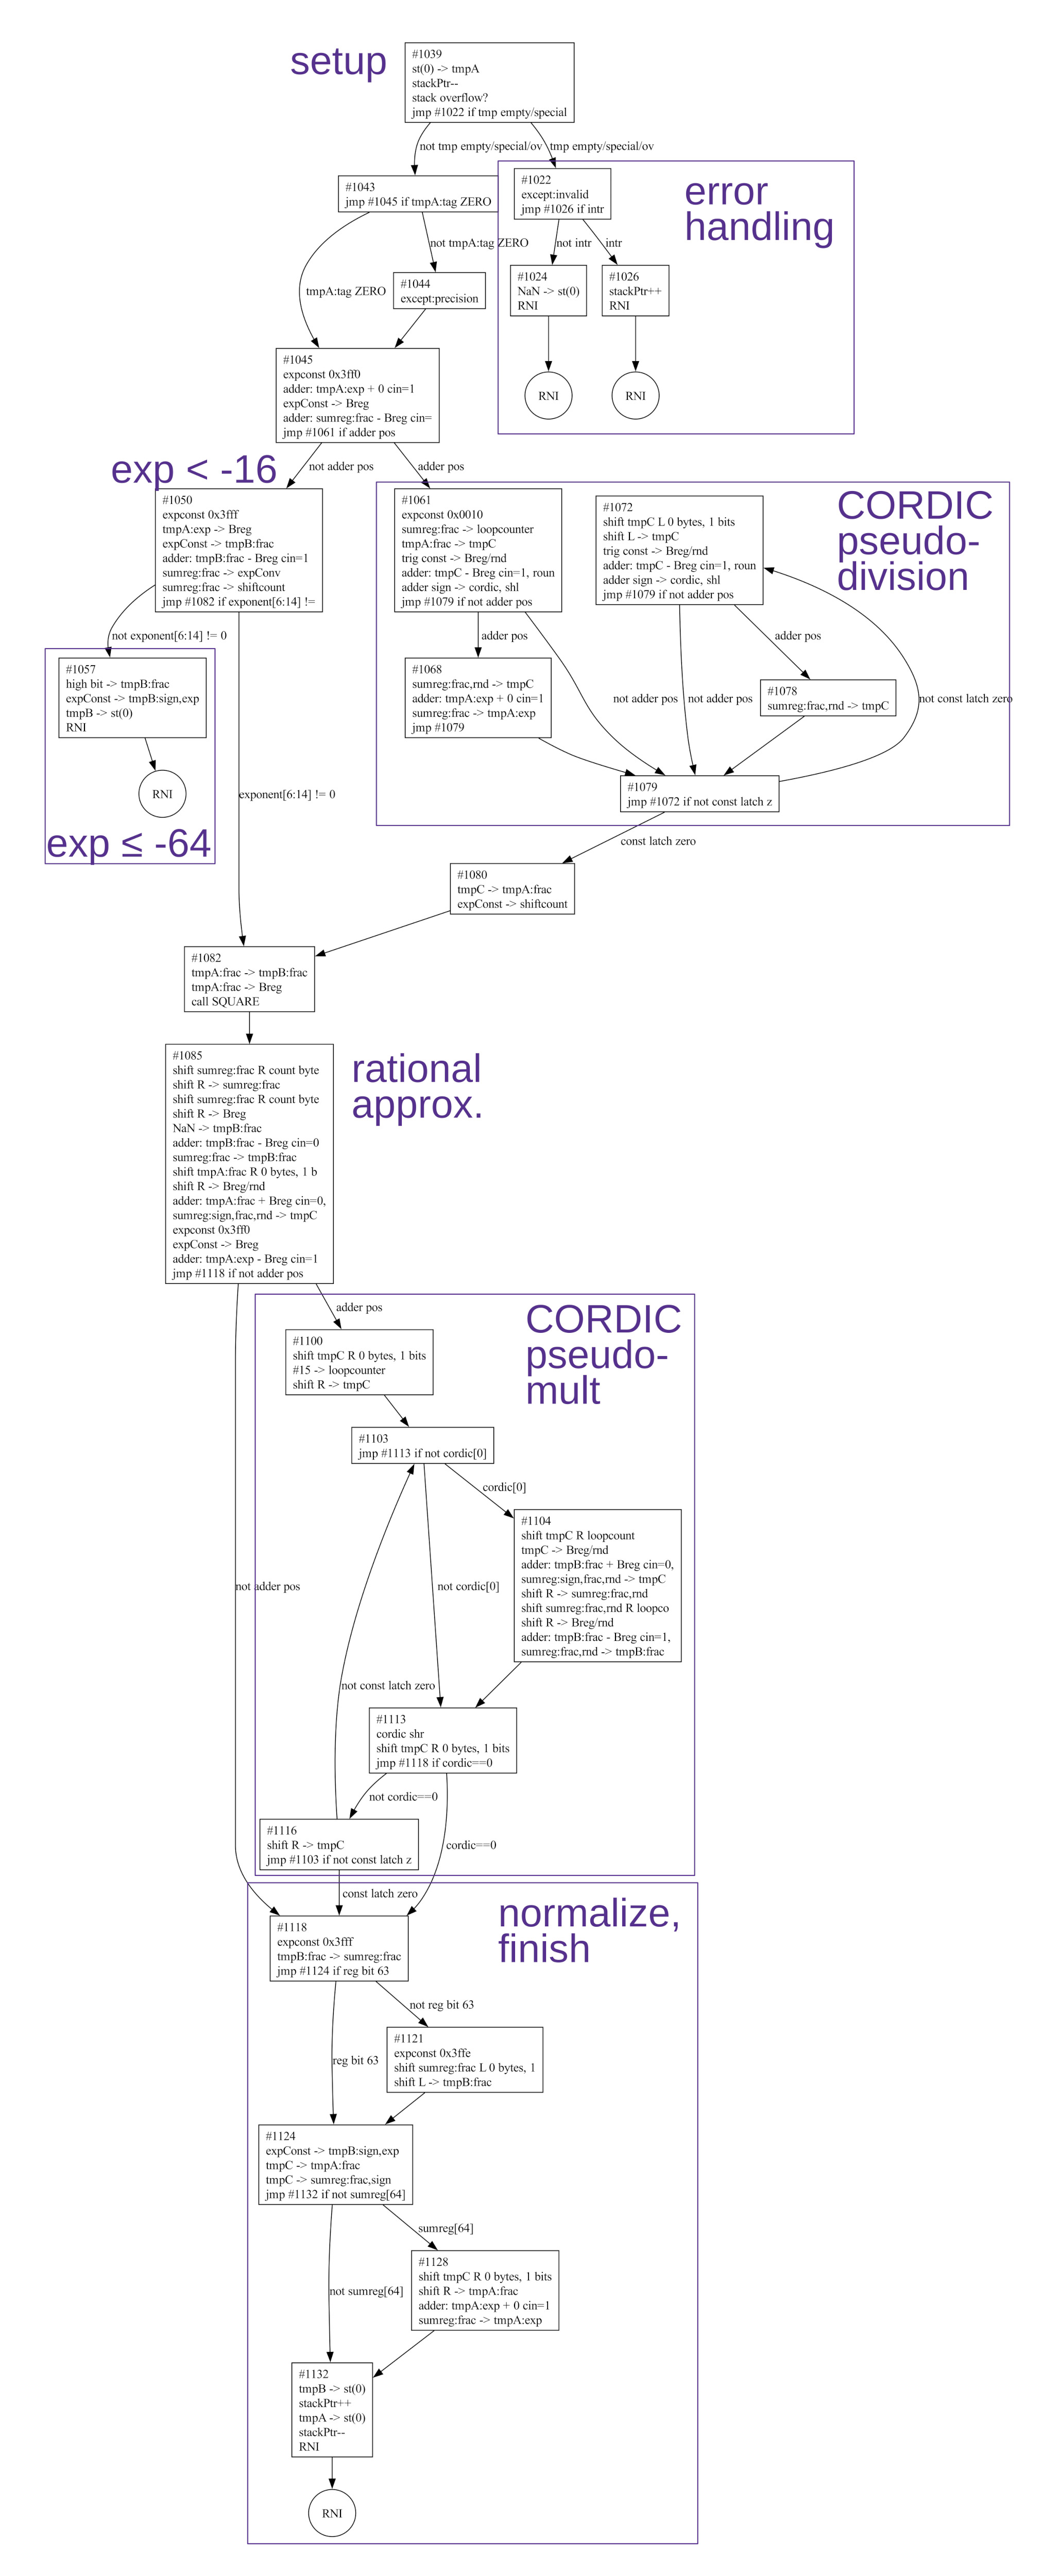
The comparisons take multiple micro-instructions, for example, selecting a constant such as 0x3ff0 (recall that exponents are biased by 16383 or 0x3fff, so 0x3ff0 corresponds to -15), moving the constant to the adder,
subtracting the constant from the exponent, and branching on the result. ↩
The first step of the CORDIC algorithm (#1061-#1068) is handled separately.
It took me a while to figure out why the first step of the CORDIC algorithm is special.
The cause is that the CORDIC angles are close to 2-n, but not exactly.
Thus, the number of CORDIC cycles does not change exactly when the exponent of the input angle changes.
This is a problem because the number of pseudo-division cycles depends on the exponent,
but the number of pseudo-multiplication cycles depends on the largest CORDIC angle used.
Since the numbers are scaled in both loops, a mismatch in the number of cycles leaves
the result off by a factor of 2. The first CORDIC step tests if the first CORDIC constant
is used and increments the tmpA exponent by 1 to counteract this.
(Don't worry if this doesn't make sense.) ↩
The constant ROM in the 8087 holds the significands, but not the exponents. When I originally extracted the constants from the constant ROM, back in 2020 (link), I couldn't find the exponents, so I came up with plausible exponents that resulted in meaningful values. The 8087 has a separate exponent ROM. Now that I've examined the microcode, I can see that the exponents in the exponent ROM are unrelated to the significands in the constant ROM. I'm glad I didn't waste much time trying to figure out the exponents back then :-) ↩
The following table shows the calculations at each step of the algorithm, using 0.95 as the input. Note that the calculations are done with integer arithmetic; the exponents (gray) are not stored as part of the numbers, but are implied by the algorithm. The exponents change in each step, so as the values get smaller during the pseudo-division stage, the exponents get smaller too, ensuring that the values can use most of the available bits. The opposite happens during pseudo-multiplication: the values start off small and grow as the vector is rotated; the exponent is increased each step to counteract this. Unlike "real" floating-point numbers, the bit representations are not normalized; sometimes they have two 1 digits to the left of the binary point, and sometimes they have leading zeros. That is, the exponents are fixed for each step; they don't change based on the value.
| operation | bits | value | flag | reg |
|---|---|---|---|---|
| load with θ | 1.1110011…×2-1 | 0.9500 | tmpC | |
| cmp atan(20) | 1.1001001…×2-1 | 0.7854 | 1 | const |
| sub angle | 0.0101010…×2-1 | 0.1646 | tmpC | |
| shift left | 0.1010100…×2-2 | 0.1646 | tmpC | |
| cmp atan(2-1) | 1.1101101…×2-2 | 0.4636 | 0 | const |
| shift left | 1.0101000…×2-3 | 0.1646 | tmpC | |
| cmp atan(2-2) | 1.1111010…×2-3 | 0.2450 | 0 | const |
| shift left | 10.1010001…×2-4 | 0.1646 | tmpC | |
| cmp atan(2-3) | 1.1111110…×2-4 | 0.1244 | 1 | const |
| sub angle | 0.1010010…×2-4 | 0.04025 | tmpC | |
| shift left | 1.0100100…×2-5 | 0.04025 | tmpC | |
| cmp atan(2-4) | 1.1111111…×2-5 | 0.06242 | 0 | const |
| shift left | 10.1001001…×2-6 | 0.04025 | tmpC | |
| cmp atan(2-5) | 1.1111111…×2-6 | 0.03124 | 1 | const |
| sub angle | 0.1001001…×2-6 | 0.009007 | tmpC | |
| shift left | 1.0010011…×2-7 | 0.009007 | tmpC | |
| cmp atan(2-6) | 1.1111111…×2-7 | 0.01562 | 0 | const |
| shift left | 10.0100111…×2-8 | 0.009007 | tmpC | |
| cmp atan(2-7) | 1.1111111…×2-8 | 0.007812 | 1 | const |
| sub angle | 0.0100111…×2-8 | 0.001195 | tmpC | |
| shift left | 0.1001110…×2-9 | 0.001195 | tmpC | |
| cmp atan(2-8) | 1.1111111…×2-9 | 0.003906 | 0 | const |
| shift left | 1.0011100…×2-10 | 0.001195 | tmpC | |
| cmp atan(2-9) | 1.1111111…×2-10 | 0.001953 | 0 | const |
| shift left | 10.0111001…×2-11 | 0.001195 | tmpC | |
| cmp atan(2-10) | 1.1111111…×2-11 | 0.0009766 | 1 | const |
| sub angle | 0.0111001…×2-11 | 0.0002181 | tmpC | |
| shift left | 0.1110010…×2-12 | 0.0002181 | tmpC | |
| cmp atan(2-11) | 1.1111111…×2-12 | 0.0004883 | 0 | const |
| shift left | 1.1100100…×2-13 | 0.0002181 | tmpC | |
| cmp atan(2-12) | 1.1111111…×2-13 | 0.0002441 | 0 | const |
| shift left | 11.1001001…×2-14 | 0.0002181 | tmpC | |
| cmp atan(2-13) | 1.1111111…×2-14 | 0.0001221 | 1 | const |
| sub angle | 1.1001001…×2-14 | 0.00009604 | tmpC | |
| shift left | 11.0010010…×2-15 | 0.00009604 | tmpC | |
| cmp atan(2-14) | 1.1111111…×2-15 | 0.00006104 | 1 | const |
| sub angle | 1.0010010…×2-15 | 0.00003500 | tmpC | |
| shift left | 10.0100101…×2-16 | 0.00003500 | tmpC | |
| cmp atan(2-15) | 1.1111111…×2-16 | 0.00003052 | 1 | const |
| sub angle | 0.0100101…×2-16 | 0.000004482 | tmpC | |
| X approx | 1.0111111…×21 | 3.0000 | tmpB | |
| Y approx | 0.0011100…×2-14 | 0.00001345 | tmpC | |
| Y += 2-15X | 1.1011100…×2-14 | 0.0001050 | 1 | tmpC |
| X -= 2-15Yold | 1.0111111…×21 | 3.0000 | tmpB | |
| shift right | 0.1101110…×2-13 | 0.0001050 | tmpC | |
| Y += 2-14X | 10.0101110…×2-13 | 0.0002881 | 1 | tmpC |
| X -= 2-14Yold | 1.0111111…×21 | 3.0000 | tmpB | |
| shift right | 1.0010111…×2-12 | 0.0002881 | tmpC | |
| Y += 2-13X | 10.1010111…×2-12 | 0.0006543 | 1 | tmpC |
| X -= 2-13Yold | 1.0111111…×21 | 3.0000 | tmpB | |
| shift right | 1.0101011…×2-11 | 0.0006543 | tmpC | |
| shift right | 0.1010101…×2-10 | 0.0006543 | 0 | tmpC |
| shift right | 0.0101010…×2-9 | 0.0006543 | 0 | tmpC |
| Y += 2-10X | 1.1101010…×2-9 | 0.003584 | 1 | tmpC |
| X -= 2-10Yold | 1.0111111…×21 | 3.0000 | tmpB | |
| shift right | 0.1110101…×2-8 | 0.003584 | tmpC | |
| shift right | 0.0111010…×2-7 | 0.003584 | 0 | tmpC |
| shift right | 0.0011101…×2-6 | 0.003584 | 0 | tmpC |
| Y += 2-7X | 1.1011101…×2-6 | 0.02702 | 1 | tmpC |
| X -= 2-7Yold | 1.0111111…×21 | 3.0000 | tmpB | |
| shift right | 0.1101110…×2-5 | 0.02702 | tmpC | |
| shift right | 0.0110111…×2-4 | 0.02702 | 0 | tmpC |
| Y += 2-5X | 1.1110111…×2-4 | 0.1208 | 1 | tmpC |
| X -= 2-5Yold | 1.0111111…×21 | 2.9991 | tmpB | |
| shift right | 0.1111011…×2-3 | 0.1208 | tmpC | |
| shift right | 0.0111101…×2-2 | 0.1208 | 0 | tmpC |
| Y += 2-3X | 1.1111101…×2-2 | 0.4957 | 1 | tmpC |
| X -= 2-3Yold | 1.0111110…×21 | 2.9840 | tmpB | |
| shift right | 0.1111110…×2-1 | 0.4957 | tmpC | |
| shift right | 0.0111111…×20 | 0.4957 | 0 | tmpC |
| shift right | 0.0011111…×21 | 0.4957 | 0 | tmpC |
| Y += 20X | 1.1011110…×21 | 3.4797 | 1 | tmpC |
| X -= 20Yold | 1.0011111…×21 | 2.4884 | tmpB | |
| final X | 1.0011111…×21 | 2.4884 | tmpB | |
| final Y | 1.1011110…×21 | 3.4797 | tmpA |
Eli Bendersky 26/09/2026 | Source: Eli Bendersky's website
Like many programmers, I find Alexis King's Parse, don't validate article fascinating, because it gives a name to an idiom that seems familiar and important - one I've observed and used in the past without naming it explicitly. This post is a review of the "Parse, don't validate" pattern applied to the Rust programming language (the original post uses Haskell). I was particularly interested in finding educational examples of this pattern in the Rust standard library and other well-known projects.
Without repeating the original article (please read it first!), here's the gist of it.
Consider the venerable Vec; its first method returns Option<&T>. Why? Because a vector is not guaranteed to have any elements in it, so what to do if first is invoked on an empty one? Returning an Option in this case is idiomatic in Rust [1], with convenient syntax sugar for accepting the result of functions that return Option and deciding what to do next.
So what's the issue?
Imagine we have a function to read some configuration paths from an env var, while enforcing the invariant that the list can't be empty:
use anyhow::{Result, ensure};

fn get_configuration_directories() -> Result<Vec<PathBuf>> {
    let value = env::var("CONFIG_DIRS").context("could not read CONFIG_DIRS")?;

    let directories: Vec<PathBuf> = value
        .split(',')
        .map(str::trim)
        .map(PathBuf::from)
        .collect();

    ensure!(!directories.is_empty(), "empty CONFIG_DIRS");
    Ok(directories)
}
So far, so good. Now let's take a typical usage of this function:
fn main() -> Result<()> {
    let config_dirs = get_configuration_directories()?;

    match config_dirs.first() {
        Some(cache_dir) => initialize_cache(cache_dir),
        None => unreachable!("already checked that CONFIG_DIRS is non-empty"),
    }

    Ok(())
}
Once get_configuration_directories returns a successful result, we are guaranteed that the vector isn't empty. And yet, if we want to get the first element of this vector, we have to use the first method that returns Option<&T>. We are therefore forced - again - to handle a potentially empty case (where the option is None).
As the original article states, this has a number of problems with code clarity, potential performance implications and a ticking time bomb if the invariant is ever changed in get_configuration_directories.
The core issue is that Vec is fundamentally a type that can be empty; we can carry along a "This one can't be empty, pinky promise!" comment on all the relevant code, but it's not formally checked by anything.
The solution is leveraging the type system to enforce a newly established invariant. We can use a separate type for "a vector that cannot be empty"; in fact, such types already exist in several Rust crates - for example nonempty:
pub struct NonEmpty<T> {
    pub head: T,
    pub tail: Vec<T>,
}
This type has no constructor that permits "no elements"; its new takes one element, and its first method returns &T without an Option:
pub const fn new(e: T) -> Self {
    Self::singleton(e)
}

pub const fn singleton(head: T) -> Self {
    NonEmpty {
        head,
        tail: Vec::new(),
    }
}

pub const fn first(&self) -> &T {
    &self.head
}
The rest of the crate deals with making NonEmpty behave as close as possible to a normal Vec, by implementing many useful traits, as well as conversions like:
pub fn from_vec(mut vec: Vec<T>) -> Option<NonEmpty<T>> {
    if vec.is_empty() {
        None
    } else {
        let head = vec.remove(0);
        Some(NonEmpty { head, tail: vec })
    }
}
Let's see how our get_configuration_directories function would look if it returned a NonEmpty instead of a plain Vec:
fn get_configuration_directories() -> Result<NonEmpty<PathBuf>> {
    let value = env::var("CONFIG_DIRS").context("could not read CONFIG_DIRS")?;

    let directories = value
        .split(',')
        .map(str::trim)
        .map(PathBuf::from)
        .collect();

    let Some(directories) = NonEmpty::from_vec(directories) else {
        bail!("CONFIG_DIRS cannot be empty");
    };

    Ok(directories)
}
Note the use of NonEmpty::from_vec here - this is where the invariant is established. Now a successful result is NonEmpty, not just Vec. The client code looks like:
fn main() -> Result<()> {
    let config_dirs = get_configuration_directories()?;

    initialize_cache(config_dirs.first())?;
    Ok(())
}
There's no need to check if the returned value is empty again; this is enforced by the type system!
This is where the parse vs. validate terminology of the original article comes from. When get_configuration_directories returned a Vec, it simply validated it. But when it returns a NonEmpty - the vector is transformed into another entity which carries additional meaning. If we treat the concept of parsing in the most generic sense - "transforming data from one format to another", this fits.
To mention a less artificial example, the Rust rewrite of core POSIX utilities uses NonEmpty in several places [2]. For example, when constructing a shell pipeline:
pub struct Pipeline {
    pub commands: NonEmpty<Command>,
    pub negate_status: bool,
}
The command parser's code:
fn parse_pipeline(&mut self, alias_table: &AliasTable) -> ParseResult<Option<Pipeline>> {
    // pipeline = "!" command ("|" linebreak command)*
    let negate_status = self.match_alternatives(&[CommandToken::Bang])?.is_some();
    let mut commands = if let Some(command) = self.parse_command(alias_table)? {
        NonEmpty::new(command)
    } else {
        return Ok(None);
    };

    // ...
A valid Pipeline is only returned if there are some commands in the parsed AST. Otherwise, it just returns None. Once this is done, the client code can use commands.first() without having to worry about the possibility of it returning None.
A somewhat more interesting example can be found in the source code of rust-analyzer. This project has a type that represents an absolute filesystem path:
pub struct AbsPathBuf(Utf8PathBuf);
Instead of carrying around a regular path, the absoluteness is recorded in the type once the initial parsing and validation is done:
impl TryFrom<Utf8PathBuf> for AbsPathBuf {
    type Error = Utf8PathBuf;
    fn try_from(path_buf: Utf8PathBuf) -> Result<AbsPathBuf, Utf8PathBuf> {
        if !path_buf.is_absolute() {
            return Err(path_buf);
        }
        Ok(AbsPathBuf(path_buf))
    }
}
Subsequent code doesn't have to validate the the path is absolute. The type enforces it.
Note also that AbsPathBuf wraps Utf8PathBuf, not PathBuf. Utf8PathBuf is itself a custom, "parsed" type refinement from the camino crate. Regular paths in the Rust standard library aren't guaranteed to be valid UTF-8, so they cannot be easily converted to a String (which has to be valid UTF-8 in Rust); camino::Utf8PathBuf establishes validity on construction, and can then be converted to a string with just:
fn as_str(&self) -> &str {
  ...
}
So we have an example of gradual parsing and type refinement here:
std::path::PathBuf

      |
      |   prove UTF-8
      |
      V

camino::Utf8PathBuf

      |
      |   prove absolute
      |
      V

rust-analyzer's paths::AbsPathBuf
Rust has a generic type called NonZero, to describe unsigned numeric quantities that are known to be non-zero.
For example, thread::available_parallelism is defined as:
pub fn available_parallelism() -> Result<NonZero<usize>>
If the call is successful, it returns a NonZero<usize>, which is like a normal usize with the restriction that it's not zero. Client code doesn't have to keep checking whether the parallelism is 0 - it's enshrined in the type system.
Rust defines the division operator with NonZero<usize> in the denominator as an operation that "cannot panic".
NonZero has an additional advantage: zero is an invalid value for the type, so Rust can use the zero bit pattern to represent None. Consequently, Option<NonZeroUsize> is guaranteed to have the same size and alignment as NonZeroUsize itself (and as usize). This can avoid the extra storage that an Option<usize> would generally require.
A common example of the "parse, don't validate" idiom appears in deserializing data from a JSON string. Rust's serde crate enables us to do the parsing, with validated decisions encoded into the type system, e.g.:
#[derive(Debug, Deserialize)]
struct Config {
    name: String,
    workers: NonZeroUsize,
    mode: Mode,
}

#[derive(Debug, Deserialize)]
#[serde(rename_all = "snake_case")]
enum Mode {
    Fast,
    Safe,
}
And then later:
let input = r#"
     {
         "name": "compiler",
         "workers": 4,
         "mode": "fast"
     }
 "#;

 let config: Config = serde_json::from_str(input)?;
There is a lot happening behind the scenes:
We take code like this for granted these days, but it's still a great example of the pattern discussed in this post. Once the parser converted mode into the Mode enum, no further validation is required.
In dynamic languages like Python and JS, the process is usually much more manual. Python's json.loads gives us a dictionary, and it's up to the user to validate its contents. Libraries like Pydantic permit an approach closer to Rust's, but they're not universally used.
| [1] | Other languages - like Go or Python - don't have a dedicated first method or function, and instead have the programmer rely on a runtime check that raises some sort of exception or panic when lst[0] is accessed on an empty list or slice. This is not by mistakel these methods / functions were not added to Go and Python precisely because their semantics are tricky to narrow down without a type like Option. |
| [2] | The project implements its own NonEmpty, without relying on the nonempty crate, but all the points in this post apply. |
Anonymous 22/09/2026 | Source: is this it?
Spring brings sunny and still days. One weekend morning we walked around the streets of Camberwell. Every couple of blocks we’d see a house in some stage of demolition, while others were being constructed.


This time of year, my evening walk home from the train station is timed with peak golden hour. For a couple of weeks I took my camera to work and kept an eye out for shots on the walk home.


Carlton and Fitzroy are my favourite suburbs for shooting buildings, streets, and architecture. There’s something about the Victorian-era architecture, pastel yellows, and very abrupt and vertical walls that immediately border the street that appeals to my eye. Shooting these suburbs on digital cameras gives the photographs a clinical look that doesn’t match my experience of being there. So I shoot them on film.
All of these photographs are shot on my old Nikon with a 40mm lens. Portra 160 film handles the high dynamic range of sunsets, while giving character to blue skies and hints of colour to otherwise white walls, like the bricks below.

Carlton.

Eras.

Carlton II.

Carlton III.

Carlton IV.

Colour.

Carlton V.

Carlton VI.

Carlton VII.

Wall.

Carson Gross 21/09/2026 | Source: htmx - high power tools for html
/src, next to the code it producesIn order to supplement my income as a professor at Montana State University, I do consulting on the side. I enjoy consulting and the act of writing code & helping build systems, both for their own sake and also because it keeps my skills relevant and allows me to teach students about the latest ideas in software development.
Obviously the biggest thing to happen in development in the last few years is agentic coding: using LLMs to generate code in lieu of hand coding. I have written a few essays on this topic:
In this essay I want to discuss an idea that is becoming increasingly clear to me as I work in companies that are prioritizing agentic coding:
Markdown is now source code, not documentation.
This is not a novel or particularly clever idea, of course.
In Markdown is the new source code, Hartley Brody writes:
It is starting to feel as if the application logic of the software is being defined and edited as markdown, and the actual code that is generated by the agent is sort of becoming a low-level implementation detail.
Now, as the essays above show, I am ambivalent about AI-generated code. However, my consulting work shows that organizations are headed in this direction, often at terrific speed.
What I want to do in the remainder of this essay is think about the ramifications of Markdown becoming, more and more, the source of truth for software systems.
There is a line of thinking, captured in the quote above, that LLMs are akin to compilers, taking high-level specifications and turning them into low-level implementations. In this view, we don’t need to look at the code an LLM generates, just as we don’t look at the machine code a compiler generates.
As I mention in Code is Cheap(er), I do not totally agree with this analogy for a few reasons, but the one relevant to this essay is: compiler workflows retain their original source code while LLM workflows typically do not.
Today, LLM-generated code is often created via a string of prompts fed into an agent as a developer builds out a feature. In practice, this means that the generated code is the closest thing we have to “ground truth” for that feature. There may be documentation for the feature stored elsewhere (e.g. Linear, Slack threads, wikis, etc.) but, so far as the codebase is concerned, the generated code is the source of truth.
My opinion is that, in professional agentic coding environments, we need to accept that LLM-generated code that emerges from ephemeral prompting sessions is not ideal, and begin moving towards capturing and checking in Markdown alongside generated code in the source directory.
Markdown has many nice properties that make it similar to traditional source code:
And, in fact, it is already acting as source, to an extent, in AGENTS.md, specs, plans, TASK.md and so forth. We just haven’t standardized capturing that source yet.
In Markdown is the new source code, Brody says he keeps his Markdown files in .scratch/research/ and .scratch/plan/ as he works. I have adopted the convention of creating a /tmp directory for similar ephemeral needs.
My proposal is that we promote some of these files to a new directory, alongside our existing source code: /src/md
The Markdown captured in this proposed directory would be lower level than traditional design documents:
It is much closer to a specification (although it is not one) than a design document as traditionally managed by a project manager or designer.
I am a fan of locality, and I think that moving Markdown into /src has strong locality advantages:
/src can be consumed by both humans and agentsOther sources of truth for the behavior of the system can still exist. These sources would provide higher-level and/or “process-oriented” documentation: high-level design documents, issues that need a resolution workflow and so forth.
But the core, current and static intended behavior of the system would increasingly be captured directly in Markdown in the source directory.
I have seen many people online saying that tests are the new specification (or always were). I think there is some truth to that.
However, tests are not a good mechanism for human/agent interaction:
I think the following division of labor makes sense:
/src and is the specification(ish)/test (or wherever) and are based on that Markdown, providing automated confirmation of correctnessAgain, the core idea here is that, rather than generating code and tests from prompts, a developer would work on Markdown in the /src directory, from which the code and tests would be derived.
/src/md Markdown Looks LikeThe Markdown in /src/md sits between a formal specification for the system and high-level design documents.
As with source code, there is a Complexity Budget associated with this Markdown. It will require thoughtful management to keep these documents clean, well-factored and at the right level of abstraction.
Developers should be expected to interact with both the Markdown and the derived code, so synchronizing the two (when appropriate) will become an important skill.
For example, developers will often do subtractive, constraining work on generated code, and those changes may need to be moved back into the Markdown.
I believe that agents should not be used to generate much content in /src/md. This directory should be mainly human authored and curated.
/src/md ConventionThis is necessarily the weakest part of this essay because this is a new idea and I haven’t used it extensively yet. It is me thinking out loud and inviting discussion.
With that said, here is a possible /src/md standard:
src/
  md/
    README.md          # index of all md, entry point for agents
    TODO.md            # a list of general TODOs open for this module
    OVERVIEW.md        # a technical overview of this module
    features/FEATURE_1.md       # a set of feature-specific documents
    data/DATAMODEL_1.md         # descriptions of data models in the module
    api/API_1.md                # descriptions of APIs the module provides
    infrastructure/INFRASTRUCTURE_1.md   # descriptions of infrastructure used by the module
Here the features, data, api and infrastructure directories are all optional; the idea is to divide along different axes to best capture a solid working description of the module’s behavior directly in the /src/md folder.
As code gets cheaper to generate, what remains valuable is the intent behind the code: what it does, why it does it, and what it must not do.
Today that intent is often lost in ephemeral prompting sessions, or scattered across wikis, tickets and Slack threads.
I think that, in the name of locality, we should consider capturing this intent in Markdown and checking it in to /src, alongside the code it produces, where both humans and agents can find it.
I don’t know exactly what the right structure for something like /src/md is yet, and I expect my thinking will change as I (and others) get more experience with it.
But I am fairly confident that Markdown is becoming source code, and that we should increasingly treat it like source code.
(Even though, no, LLMs are not compilers :)
Yegor Bugayenko 20/09/2026 | Source: Yegor Bugayenko
Claude helped me write this. Mostly quotes and fact-checking. I catch myself wanting to stress the “mostly,” and that is the whole subject of this essay. It’s September 2026. By September 2027 I don’t expect to be using Claude to write blog posts. Because I don’t expect there to be blog posts by me to write. I won’t be a writer. I won’t be a programmer either. And I don’t know what a man is for, after that.
In 1908, Alfred Adler suggested that contributing to others (a.k.a. Gemeinschaftsgefühl) is what gives the individual a sense of worth. Later psychologists, like Morris Rosenberg and Gordon Flett, called it “mattering”: the sense that one is significant to others. Adjacent to this, Edward Deci and Richard Ryan, authors of the Self-Determination Theory, identified “relatedness”: a psychological need to be bonded with others. Simone Weil in The Need for Roots (1943) listed “to feel one is useful and even indispensable” among the “vital needs of the human soul.” Moreover, Émile Durkheim in Le Suicide (1897) found suicide rates rise as social integration falls.
“The true joy in life,” according to Bernard Shaw in Man and Superman (1903), is “being used for a mighty purpose.” I believe that being needed by others is not only a joy, but the primary reason to exist.
There are nearly 50 million programmers like us in the world, by SlashData’s count. We are a small part of something larger: about 400 million people whom ISCO classifies as “professionals”—one in nine of everyone employed on the planet. Peter Drucker named us “knowledge workers” in Landmarks of Tomorrow (1959), before the personal computer existed. Robert Reich, in The Work of Nations (1991), called us people who “manipulate symbols,” and put us at a fifth of the American workforce. Counting managers and technicians alongside professionals, ISCO now finds 20.1% of the planet in that kind of work. The world looks the way America looked in 1989. We contribute by thinking, and that is what makes us needed.
However, LLMs already think better than us, and faster too. At the 2025 ICPC World Finals, Gemini solved ten of twelve problems. Had it competed as a team of humans, it would have finished 2nd out of 139. It also solved Problem C, which no human team solved at all. That was a year ago. I’ve been writing code for more than 25 years, contributing over 100K lines to my GitHub annually. Since March, not a single line of code committed under my name has been written by me. It’s all Claude Code. It was 4% in February.
And they are not only good. They are cheap, and getting ~13x cheaper every year—faster than computing or electricity ever fell. If all of us took a fifty percent pay cut tomorrow, the machines would take back the difference in ninety-nine days. Dario Amodei describes what is arriving: “millions of instances,” each thinking at “10x-100x human speed”—a “country of geniuses in a datacenter.” Thinking stops being scarce. Soon we won’t be needed.
Some expect a market for artisanal code: machines will write the millions of routine lines, and humans will craft the parts that matter, charging double for it. This won’t happen for the same reason nobody hand-writes assembly anymore. No law banned it. The compiler simply got better than we were. Every published study still says our code is the safer of the two.
I don’t believe them anymore. Since March I have shipped nothing else but LLM-written code, and the quality is higher than a year ago. Our code won’t be illegal at first—just something no reviewer approves. In mission-critical systems first, then everywhere. “Made by a human” will stop being a price premium and will become a disclosure.
None of this is new. Steven Pinker in The Language Instinct (1994) predicted this: “It will be the stock analysts and petrochemical engineers and parole board members who are in danger of being replaced by machines. The gardeners, receptionists, and cooks are secure in their jobs for decades to come.” He was writing about the future. Thirty-two years later it is career advice.
In May 2026 Jensen Huang a graduating class at Carnegie Mellon: “Electricians, plumbers, iron workers, technicians, builders—this is your time.” He meant it kindly. He was talking to people who had just finished four years of university. We will retire, or we will move to physical work.
John Keynes named it in Economic Possibilities for Our Grandchildren (1930): “technological unemployment,” he called it, “unemployment due to our discovery of means of economising the use of labour outrunning the pace at which we can find new uses for labour.” Yuval Harari named the people in 2017: a useless class that “will not merely be unemployed—it will be unemployable.”
A child born today will be obsolete before he finishes school.
Nick Bostrom declared a world of “deep redundancy” in Deep Utopia (2024): there is nothing you could do that anyone would need. He proposed “artificial purpose”—challenges designed for us by the intelligence that replaced us. Keynes already knew how that ends: the people who had money and no duties, he wrote, “failed disastrously.”
This already happened once, to people with less protection than us. From 1999, middle-aged Americans without a degree started dying faster than their parents’ generation—the first such reversal in a century. Drugs, alcohol, suicide. 151,845 of them in 2017 alone. The suicide rate was the highest since 1938. Deaths from alcohol were the highest since the First World War. Anne Case and Angus Deaton found the cause was not poverty. It was the sense that “their ability to contribute to society has been terribly thwarted.” We read about it, called it their problem, and went back to work. Now the same thing is coming up the ladder, for the people who have the degrees.
Hannah Arendt saw the shape of this in 1958, before programming became a profession. “What we are confronted with,” she wrote, “is the prospect of a society of laborers without labor, that is, without the only activity left to them. Surely, nothing could be worse.” And she saw no way out: no class left, “no aristocracy of either a political or spiritual nature from which a restoration of the other capacities of man could start anew.” The next sentence of her prologue is the one I keep returning to: “To these preoccupations and perplexities, this book does not offer an answer.”
Neither does this one.
Anonymous 20/09/2026 | Source: Irrational Exuberance
One of the interesting challenges of the AI ecosystem in 2026 is that new, effective patterns emerge faster than I can adopt them. I’ll find a handful, get back to work, and realize a month later that I’d missed four or five more. The adoption cycle for Imprint this year has been something like:
The most recent question for me has been figuring out how to adopt the software factory pattern. (After some light research, the specific AI-context origin of this term is slightly messy to attribute, but I think it might be Justin McCarthy in February 2026’s Software Factories And The Agentic Moment.)
The software factory pattern is looping on a broad goal, and then relying on the harness to drive progress towards that goal. Our first pass at implementation is fairly basic:
An agent skill /linear-project-loop which reads in a Linear project and starts by auditing
that project’s goal definition on these dimensions:
If those are missing, or the Linear project is missing in its entirety, it iterates with you on creating those missing tools.
Then it reviews the state of the metrics and issues for the project. If new work is identified, it adds those issues to the project. It updates the state of issues that have moved.
It works on the non-blocked tasks based on the project’s current state. This is often writing a pull request, updating a pull request, pinging for review, asking a clarifying question, etc.
When a task completes, if the project description is fresh, it takes on the next task. If the description hasn’t been updated in a while, it reruns the loop starting with the first step.
Right now I am running this locally in a local harness, but it’s working well enough that I anticipate moving the behavior to be driven by the same orchestrated harness that we assign one-off tasks to.
What I particularly like about the factory pattern is that it parallels very closely how I’ve been working locally, while forcing me to recognize the places where I was accidentally hoarding parts of the state for myself regarding the goals of the project. I was already asking agents to iterate on specific Linear projects, but they didn’t have the ability to evaluate if they were going in the right direction, or if it was missing necessary tasks. Now it does. The other place this has been extremely helpful for me is checking in on projects post-release. For example, I shipped our passkeys implementation earlier this year, but some months go by without my checking in on how it’s going. If we saw adoption spike, or error rates start to turn, I might miss it, but running the factory in a less frequent post-release mode would catch it immediately.
The final thought that’s been interesting to me is how much all of the pieces here compound only to the extent that you have the other pieces. For example, this factory pattern depends on having Datadog MCP and Snowflake access available to manage goal-tracking, but it also depends on Linear being the single source of state for the company’s work, and an orchestrated harness that can perform work independently from your laptop. Keeping up with this many migrations is a fascinating industry moment.
Alex Russell 20/09/2026 | Source: Infrequently Noted
An excellent feature of Eleventy1 is the official PrismJS-based syntax highlighting plugin, which adds painless build-time syntax highlighting. It keeps 11ty sites from worrying about client-side bloat from JS-based highlighters and the common failure mode of over-including language definitions.2
But nothing's perfect.
The official plugin integrates naturally, and I took to using it via the usual triple-backtick markdown syntax:
# The Usual Markdown Nonsense { #the-usual-nonsense }

And now for something entirely different:

```js
function yourCodeHere() { /* ... */ }
```

Etc., etc.
This works a treat, until you want a bit more control. At that point, what seems magical starts to feel restrictive.
A recent goal was to add line numbers.
After reading some of the plugin code that invokes PrismJS, I closed my laptop in frustration, unable to cajole eleventy-plugin-syntaxhighlight into outputting line numbers. Walking away from the keyboard paid off a few days later when I recalled the paired shortcode code path generated stable per-line delimiters. This allowed reuse of the plugin's primary logic, wrapped in a bit of string munging to add the necessary styling hooks:
// From this site's Eleventy config file

// Because my esm conversion is still partial:
const { default: syntaxHighlight } =
        await import("@11ty/eleventy-plugin-syntaxhighlight");
// ...
module.exports = async function(config) {
  // ...
  let syntaxHighlightOptions = {
    // For faster CSS selectors
    preAttributes: { highlighted: "highlighted" },
    codeAttributes: { highlighted: "highlighted" },
  };

  config.addPlugin(syntaxHighlight,
                   syntaxHighlightOptions);

  config.addPairedShortcode("code",
                            function(content,
                                    language="",
                                    highlightLines="") {
    // The design of cssMin and addToBundle are outside
    // the scope of this post.
    //
    // Suffice to say, we're inlining the contents
    // of the file path passed as an argument to it.
    //
    addToBundle(
      this,
      "css",
      `<style>${
        cssMin("assets/css/prism-okaidia.css")
      }</style>`);

    let xformed = syntaxHighlight.pairedShortcode.call(
        this,
        content,
        language,
        highlightLines,
        syntaxHighlightOptions
    );

    // Wrap each line in `<span class="line">...</span>`
    let _preamble = "<pre><code>";
    let _end = "</code></pre>";
    let _content = "";

    // Preamble and postfix might be different than
    // defaults above, so preserve them.
    let preambleEnd =
      xformed.indexOf(">",
                      xformed.indexOf("<code")) + 1;
    _preamble = xformed.substring(0, preambleEnd);

    let contentEnd =
      xformed.lastIndexOf("</code></pre>");
    _content =
      xformed.substring(preambleEnd, contentEnd);

    let parts = _content.split("<br>");

    // Wrap each line in a stylable <span>
    _content = parts.map((line) => {
      return `<span class="line">${line}</span>`;
    }).join(`<br>`);
    return _preamble + _content + _end;
  });

  // ...

};
Add a bit of CSS that does the counting for us, ét voila!, line numbers:
pre[highlighted] {
  display: block;
  overflow-x: auto;
  isolation: isolate;
  max-width: 100%;
  contain: content;

  & > code {
    width: 100%;
    text-wrap-mode: wrap;
    counter-reset: step;
    counter-increment: step 0;

    & .line::before {
      content: counter(step);
      counter-increment: step;
      width: 1.5rem;
      padding-right: 0.5rem;
      margin-right: 0.5rem;
      display: inline-block;
      text-align: right;
      color: var(--color-mid);
      border-right: 1px solid currentColor;
    }
  }
}
If the JavaScript approach looks familiar, that might be because it's the technique outlined last year when I pressed the 11ty Bundler into service as a poor man's route-based code splitter, allowing each shortcode that requires JavaScript to lazily include it only for pages that feature those components:
// An `.eleventy.js` configuration file

module.exports = async function(config) {

  // Register some bundles that templates output.
  config.addBundle("js");
  // etc., ...

  // Needed to avoid Markdown double-processing.
  let removeNewlines = function(str) {
    return str.replace(/[\n\r]/g, "");
  }

  // Invoke shortcodes that `config.addBundle()`
  // generates from within *other* shortcodes,
  // allowing us to use the Bundler for duplicate code
  // removal and hoisting dependencies to the optimal
  // place in output templates.
  function addToBundle(scope, bundle, code) {
    config.getPairedShortcode(bundle).
            call(scope, removeNewlines(code));
  }

  config.addShortcode("someblock",
                      function(/* ... */) {
    addToBundle(this, "js", `
      <script type="module" async
          src="/assets/js/someblock-deps.js">
      </script>
    `);
    // ...
  });
  // ...
};
The 11ty syntax highlighting hack only works because the output always has a <br> delimiter when invoked via HighlightPairedShortcode. While brittle, it does work. Invoking it via Nunjucks paired shortcode syntax is longer than triple-backticks, but not painful:
# The Usual Markdown Nonsense { #the-usual-nonsense }

And now for something entirely different:

{% code "js" %}
function yourCodeHere() { /* ... */ }
{% endcode %}

Etc.
This blog hasn't been code-heavy of late, but this has been working well enough for a fair few months. If anyone is interested to see this wrapped up in an 11ty plugin, let me know.
Line numbers scratched an itch, but the situation was uneasy; PrismJS emits sub-optimal markup and features like highlighting never worked. I've remained curious about other solutions.
Enter my colleague Dave Rupert's extremely cool MicroLighter project. If you'd like to learn more about the ultra-modern web decisions behind it, he's got a great blog post that teases out the whys and wherefores.
As I've been thinking about syntax highlighting alternatives for use here and an upcoming, 11ty-based multi-document HTML slide system (provisional name: "Faro"), reworking {% code "..." %} to use something else behind the scenes has seemed increasingly beneficial. To that end, here's the general approach I've ended up with to integrate MicroLighter:
Ensure that all the files get copied to the output directory.
It's a bit more complicated than this in practice, as I avoid copies in favour of symlinks for speed in dev mode — this blog rebuilds from scratch in less than six seconds and sub-second incrementally on a Chromebook — but the effect is the same:
config.addPassthroughCopy({
  overwrite: false,
  "node_modules/microlighter/dist": "assets/microlighter",
});
Use the approach from last year's post to include scripts and inline the CSS only when needed.
This has three components:
<link rel="modulepreload" ...> tags are generated for each used language.There's a bit of finagling here to replicate what the Web Component's runtime language aliases (js in addition to javascript, e.g.). I don't have a solution for language dependencies, but top-level grammar preloading avoids network stalls in my limited use.
Handle content escaping in shortcodes.
By default, 11ty and Nunjucks (my templating engine of choice) escape content, replacing < with <, e.g. which is what we want for code that will live inside a <pre><code>...</code></pre> block. It's less desirable in cases where the surrounding markup is intended to land in the final page as HTML, as is the case with web components.
Sidestepping Nunjucks escaping relies on old env.filters.safe() and env.filters.escape() hacks, and skipping Markdown escaping comes courtesy of markdown-it-ignore.
Together, these allow passthrough of web component markup amidst other processing.
Step #2 is the linchpin. I would not have felt comfortable adopting a client-side solution without the ability to load dependencies in a way that plays well with other content and only includes code when highlighting is required and brings in language definitions as-needed.
The dependency chain for this new shortcode is a bit unwieldy and site-specific, so I hesitate to offer as a plugin. If someone with ambition is interested, I'd be happy to share my hacky code and talk through how it might be made more general.
I understand the brand-consistency arguments for 11ty's Build Awesome rebranding. I'm a huge fan of Zach, the lovely and supportive community he has built, and the OSS funding model that the Fonticons, Inc. folks have put into practice with Font Awesome, Web Awesome, and now Build Awesome.
I get it, deeply. When the Build Awesome kickstarter was announced, I was early to throw cash at the effort, and I'm pleased as punch to see the community's outpouring of support for the project.
...all of which is preamble to say that I won't be uttering the words "Build Awesome" unironically. It's always eleventy to me, and I hope everyone will forgive (or at least accommodate) my style guide transgressions. ⇐
You might be thinking "surely nobody includes every PrismJS language in their bundles in 2026?", and I'd reply that you, sir or madam, are not looking closely at the bundles of the pages you experience feeling "a little bit slow".
Not only is correct dependency inclusion like hen's teeth in "modern" frontends, I've personally diagnosed close to a dozen cases of PrismJS language definition over-inclusion over the past few years. Perhaps syntax highlighting blunders will fade away in the future, but that point was not last year, last month, or yesterday. ⇐
Eli Bendersky 19/09/2026 | Source: Eli Bendersky's website
The following are my notes on discrete-time Fourier series (DTFS), as well as the discrete-time Fourier transform (DTFT). These topics serve as an important theoretical underpinning to the digital processing of signals by computers using the DFT (which will be covered in a future post).
For discrete-time signals, we use the square bracket notation to denote samples: is the n-th sample of signal .
We’ll say that a discrete-time (just discrete from this point on, for brevity) signal is periodic with period if:
When talking about continuous-time Fourier series, we started with real trigonometric functions and later moved to complex exponentials. Here, we’ll just go ahead and start directly with (discrete) complex exponentials - converting between the two representations isn’t difficult and can be done as needed (Appendix C in this post demonstrates it).
We’ll be dealing with the following family of signals [1]:
These are discrete complex exponentials that are periodic with period N. is the angular frequency. As discussed in Appendix A, there are only N such distinct signals, since:
We’ll want to consider the representation of an arbitrary N-periodic by a linear combination of :
The notation means runs over any sequence of consecutive integers. Since there are only distinct signals , the order of summation doesn’t matter - as long as all of them are used. So it could go from 0 to , or from 1 to , or from 2 to , and so on. All of these orders will enumerate all distinct .
Going back to our linear combination:
This is the discrete-time Fourier series (DTFS) representation of and the coefficients are the Fourier series coefficients. Note that there are no convergence issues as in the continuous case, because we’re dealing with a finite sum.
To find the coefficients , we’ll proceed in a way that’s somewhat similar to the continuous case. Multiply both sides of the equation above by and sum over terms:
Interchanging the order of summation on the right-hand side:
By Appendix B, the inner sum on the right-hand side is equal to when and to 0 otherwise. Without loss of generality - since we iterate over consecutive values - let’s just assume this happens in our sum when (and therefore , which is an integer multiple of ).
So our equation becomes:
Or:
To conclude, the Fourier decomposition of a periodic discrete signal into periodic complex exponentials is:
Let’s revisit the triangular function from the post on Fourier series. Here, we’ll be using the following sampled version:
The sampling is done with 12 samples per period of 4. The spacing between two samples is . Another way to express it:
Substituting this into the definition of , we get:
We then do an odd extension [2] to the range , and repeat it with period .
Using considerations similar to the continuous time case, because our function is odd we just need a sine series here:
The five terms correspond to the five pairs of nonzero-frequency indices; see Appendix C.
And the coefficients are:
We can run this sum over half the period, because the terms at  and are equal (both and the sine change
signs). Also, the terms at and vanish because
:
Looking at the values of :
We can similarly calculate all until :
The resulting Fourier series is therefore:
You can use the following interactive plot to explore this approximation to the discrete triangle function :
The dropdown box selects how many of the terms in the series shown above to plot. The orange crosses show where the series’ values at the integer indices are, and the orange line is interpolated to better visualize the sine waves being added. Note that when all the coefficients are used, the DTFS exactly reconstructs the input signal.
In the post on the Fourier Transform we’ve seen how non-periodic signals can be represented in the frequency domain by taking the Fourier series and calculating them at the limit . Here, we’ll do something similar for discrete signals.
Suppose we have a non-periodic discrete signal of finite duration (it’s zero outside a finite range of indices). Here’s a sample plot:
The bottom half is - a periodic signal, one period () of which is equal to . We choose large enough that outside and set .
Since is periodic, we can represent it with DTFS [3]:
We’ll use the notation of angular frequency:
Then:
Now the critical part; since is zero outside , extending the summation to all integers does not change its value:
We’ll define the following continuous function with variable
 :
Then at points :
The function is the discrete-time Fourier transform (DTFT) of . The inverse DTFT process reconstructs from , by substituting back into the DTFS:
By our definition of , we have:
Therefore:
Just like in the continuous case, we recognize the sum as a Riemann sum. Let . The spacing tends to zero, and we can rewrite the sum as an integral:
To conclude, the DTFT and inverse DTFT pair are:
is a continuous, periodic function with period , because:
Therefore, it’s enough to run the integral on any interval of length .
The DTFS and DTFT are closely related. Starting with a finite-duration signal , we form a periodic signal by repeating a block of samples containing it. Its DTFS coefficients are equally spaced, scaled samples of the DTFT:
The relation is similar to the one between Fourier series and the Fourier transform in the continuous case.
The DTFT also has useful properties similar to the continuous Fourier transform: linearity, time shifting, the convolution theorem etc, but we won’t spend time on them here.
Discrete-time complex exponentials have the form where is the angular frequency. The discrete nature of these functions leads to some interesting outcomes; for example, consider the exponential with angular frequency :
Therefore, the exponential at is exactly the same as the exponential at . In considering discrete complex exponentials, we need only choose from a range of length .
Another interesting aspect of these functions concerns their periodicity. In order for to be periodic with some positive integer period , the following must hold:
In other words:
So itself must be an integral multiple of . For some integer :
For a fixed positive integer , let’s consider all complex exponentials for which is a period:
But earlier we’ve said that all complex exponentials with angular frequencies apart are identical. This means that the set above consists of only distinct exponentials. We can choose any starting and get distinct signals with , , and so on until . After that, they begin repeating: and so on.
All of this is very different from the continuous case, where
is a real number. The signals and
agree only at integer values of , so
they are distinct functions of . Consequently, for
a fixed positive period  , the continuous-time exponentials
are distinct for every integer , giving
infinitely many distinct signals.
Let’s consider the following discrete function, defined by a sum:
We’ll want to consider two cases:
(1) When is an integer multiple of : for some integer (for example , , etc.)
In this case, the sum becomes:
Since both and are integers, the exponent is an
integer multiple of , so:
(2) When is not an integer multiple of , let’s do a variable change :
We can now use the finite sum formula for a geometric progression with the common ratio ; the sum is:
Note that because is not an integer multiple of . However:
Therefore:
While these calculations demonstrate the sums from to
, they work exactly the same for any consecutive
indices, because the summand is periodic in with period
. Therefore:
Using the formula for DTFS developed earlier in the post:
Recall that is odd over the full range . Specifically, since the cosine is an even function, we have for any :
Therefore the cosine terms cancel out throughout the period; term 1 is the same as negative term 11, etc.
We’re left with the sines:
All coefficients are purely imaginary. For convenience, let’s write:
Let’s turn back to the Fourier reconstruction formula:
And pair up exponentials at with ones at :
Also, since are real, the conjugate of is:
So adding the paired exponentials with their coefficients and using Euler’s formula:
Therefore:
We don’t include the terms at and , because (sine of an integral multiple of ).
| [1] | There are a lot of symbols used in this equation. is the
"time" index of the signal - its domain;
enumerates the k-th function from a family of
functions - each is a function of ;
is the period;  is the imaginary unit. |
| [2] | The odd extension may be slightly confusing because we don’t use negative indices. But indices are arbitrary! In our case, within a single period index is equivalent to ; if we consider one period around the halfway point of , it’s easy to see that the function is indeed odd. |
| [3] | Note that we use , not in the summation for . This is because within the chosen range they are equal. |
Armin Ronacher 14/09/2026 | Source: Armin Ronacher's Thoughts and Writings
Yesterday David Sacks wrote a tweet and within a few minutes people did, what they usually do, and they asked Pangram if it was AI. And Pangram said it’s entirely AI generated. To which David replied that these AI detectors are bogus.
Now Pangram has a pretty low false positive rate, but if you have ever used an LLM as a writing assitant, you will have probably noticed that it claims your posts 100% AI, even though you don’t feel like they are.
Pangram itself is a trained model, that attempts to detect segments of text as being definitely human, definitely AI and a mixture of the two. If you want to know how it works, they published a paper. The short summary is that they are manufacturing its own training data by starting from collections of known human authored text. An LLM is then tasked to understand the text and write a fresh new text on the same topic. They also let the LLM perform partial edits on that original human text and through that they can pick up on these co-authored details. Pangram claims their model to have rates of 0.0041% false AI accusations and 0.34% missed AI text.
So now that we know this I figured it might be fun to have an LLM re-create David’s tweet. I first came up with a prompt. And when I say I came up with that prompt I in fact used an LLM to propose to me from that tweet what I might want to say for the structure. I’m sure if you ask Pangram about if the above text is AI, it will probably say so, but that’s not really the point. The point is that I then used Opus 5 to generate a text which reads entirely AI generated.
If you are curious, this is the prompt I used:
Please write an 8 paragraph tweet about “Pacing the Frontier”, not longer than 350 words.
Context of this tweet is this post by Dario: https://darioamodei.com/post/we-must-pace-the-frontier
And this tweet by Sam Altman: “I agree with Dario that we need to pace the frontier. This has been a primary topic of discussions we’ve had at OpenAI in recent weeks.
Committing to having independent evaluators with employee-like access is a great idea, and we will do the same. We’ll have more to share soon.”
Structure for the post:
- Open with a concession: Note that Dario (“We Must Pace the Frontier”) and Sam Altman both want to slow down at the frontier. Say “go ahead” which reads as a surprising response.
- Establish they own the frontier: Argue OpenAI and Anthropic hold a duopoly on frontier intelligence by all kind of metrics (market share, capability, revenue etc.) and that they themselves claim the lead is widening via RSI.
- Concede you can’t see their unreleased models, so if those are scary, being responsible is their call.
- Follow with a list of a rapid-fire paragraph (“stop pretending”) rejecting the asks from Dario’s post.
- Name the commercial self-interest (Slowing down isn’t purely altruistic)
- Close with the challenge that pacing buys room for a smarter regulatory debate than Bernie Sanders “shut it all down”. Say something about China and Open Weight models.
The text that Opus 5 then wrote, was this one:
Dario published “We Must Pace the Frontier.” Sam agreed, and said OpenAI will also commit to independent evaluators with employee-like access. My response is not the one they expect: go ahead. Please do.
Because you two are the frontier. OpenAI and Anthropic hold a duopoly on frontier intelligence by every metric anyone actually uses: capability, revenue, enterprise share, developer mindshare. And you both keep telling us the lead is widening, that models are starting to improve models. If that’s true, pacing costs you a quarter you can reclaim whenever you like.
I also can’t see your unreleased checkpoints. If what’s sitting behind the curtain genuinely scares the people who trained it, then slowing down is your call to make, and the right one. I’m not going to second-guess a risk assessment I have no access to.
But stop pretending the rest of us are the problem. Stop pretending this is a collective action failure in which a handful of startups are the defectors.
Stop pretending open weights are the dangerous frontier while the two of you ship the most capable model in the world every few months. Stop pretending third-party evals require new law, when you both just committed to them voluntarily, in public, on a blog.
And stop pretending it’s purely altruism. Pacing the frontier is also margin repair. It slows the price war, stabilizes the capex story, stretches depreciation schedules across a longer product cycle, and makes life considerably harder for fast followers who survive by distilling whatever you shipped last month. Safety and self-interest are pointing the same direction here. That’s worth saying out loud.
Still, the upside is real. Pacing buys room for a smarter regulatory debate than the one on offer, where the loudest alternative is Bernie Sanders’ “shut it all down.” That’s a slogan, not policy. Meanwhile China keeps shipping competitive open weights, and any rule that binds two American labs while the rest of the world downloads its capability for free isn’t safety, it’s theater with a very expensive ticket price.
And well, Pangram agrees that this is 100% AI. So far, so uninteresting. It does read somewhat like David’s tweet, but obviously not entirely. Given that the original prompt does not have enough information to re-create the tweet entirely you would expect some divergences.
The actual thing that interests me is if you can take this output at all, and then rewrite it from scratch, but by sticking to the general structure and ideas. Will Pangram give us a AI or human rating?
I read the generated text. Then I read each paragraph and decided to rewrite and rephrase it without an LLM. According to some similarity checkers, they the final texts are 50% similar which seems about right. But strictly speaking, not a single sentence is the same. Here is the 100% human rewritten text of the above one. No LLM was used to write it, but an LLM was used to fix up typos in the end. That from my experience really does nothing to tick off an LLM detector.
Dario has written “We Must Pace the Frontier,” and Sam from OpenAI has agreed. My response might surprise people: go ahead, please.
You two are the frontier! Your companies, OpenAI and Anthropic, are at the frontier by all metrics: revenue, developer mindshare, adoption, capabilities. And yet you both claim that your lead is widening as a result of recursive self-improvement as models are improving models. You currently are the duopoly of self-improving models!
I am unable to see what unreleased models you have. When what you have behind those doors really scares your folks, then you should slow down. I’m not going to tell you otherwise and I support you.
But please don’t pretend we are the problem. Stop pretending you need our permission. Stop pretending this is all a collective issue when in reality this is all on you. Stop pretending open weights are the problem here. Stop pretending pulling third-party evaluators in requires lawmaker involvement. And for the love of all the good things in the world: stop pretending this is all about altruism.
Pacing the frontier is also about your margins, and it makes it harder for fast followers. And it patches up your capex story and has the potential for slowing down the price war ahead of the IPOs.
But yes: pacing might give us the space for a better debate than Bernie Sanders’ “shut it all down.” There is no policy there. And while we’re having fights at home, China will keep shipping competitive open-weight models and won’t adhere to any American agreements.
This is all regulatory capture hiding behind a safety debate, and the rest of the world is watching.
So what does it say? Well this text too comes back as 100% slop. And it does not surprise me all that much. I have generally noticed that if you rely on an LLM to give your text structure, it will score badly on Pangram even if you do plenty of edits over it. In fact, it’s quite unlikely you’re going to get a post that starts out as slop into a structure that will make it appear that it’s not.
I came to quite appreciate the existance of Pangram because at the very least it has made me quite aware of some of the effects that using LLMs for writing blog posts has. This blog has been AI supported for about two years (as you can see from the AI transparency link on the bottom but I did notice that I became both more reliant on those tools and that they have become much more aggressive editors and it gave me pause.
Yet, I also think that plenty of people will find a “100% AI” rating misleading when in fact the author has done plenty of editing. But maybe it’s fair to have this to show up as entirely AI?
Eryn Wells 12/09/2026 | Source: Eryn Rachel Wells
先月、日本語のクラスがまた始まった。 今学期CCSFの日本語16と日本語2Aに入った。 また勉強するが楽しみ!😄
Last month, Japanese classes started again. This semester, I enrolled in Japanese 16 and Japanese 2A at CCSF. I’m looking forward to studying again!
Ken Shirriff 12/09/2026 | Source: Ken Shirriff's blog
In the 1970s, floating-point arithmetic was a mess. Computer manufacturers had a dozen incompatible arithmetic standards. Moreover, floating-point systems were designed around hardware simplicity rather than mathematical rigor, leading to problems with numerical stability. This changed when Intel introduced the 8087 floating-point coprocessor chip in 1980, designed to be as accurate as possible, even in the corner cases. The 8087 became popular because it could be installed in the IBM PC, making floating-point operations up to 100 times faster in applications ranging from spreadsheets to CAD. But more importantly, the 8087 became the floating-point standard used by most computers today.
The 8087 implemented its instructions in complex low-level code called microcode.
I'm part of a group, the Opcode Collective, that is reverse-engineering this microcode, and I've recently made some progress.
In this post, I examine the microcode for one of the 8087's instructions—FSCALE—and describe how this microcode works.
The FSCALE (Floating-point Scale) instruction provides a quick way to scale a number by a power of two, much faster than a multiplication.
I figured that FSCALE was a simple, almost trivial instruction that would be straightforward to understand and explain.
Spoiler: it is not simple. FSCALE uses over 140 micro-instructions and three levels of subroutine calls to handle many special cases.
But the FSCALE microcode illustrates many interesting parts of the 8087, such as the shifter, the adder, and the exponent converter, and also reveals a
hidden feature of the 8087, so hopefully you will find it interesting.
To explore the microcode, I opened up an 8087 chip and created a high-resolution image with a microscope. The large microcode ROM is in the center, holding the 1648 micro-instructions that control the chip. The microcode engine on the left steps through the microcode, handling jumps and subroutine calls. The bottom half of the chip is the "datapath", the circuitry that performs floating-point calculations; it is split into a 16-bit datapath for the number's exponent and a 64-bit datapath for the number's significand (also known as the fractional part).
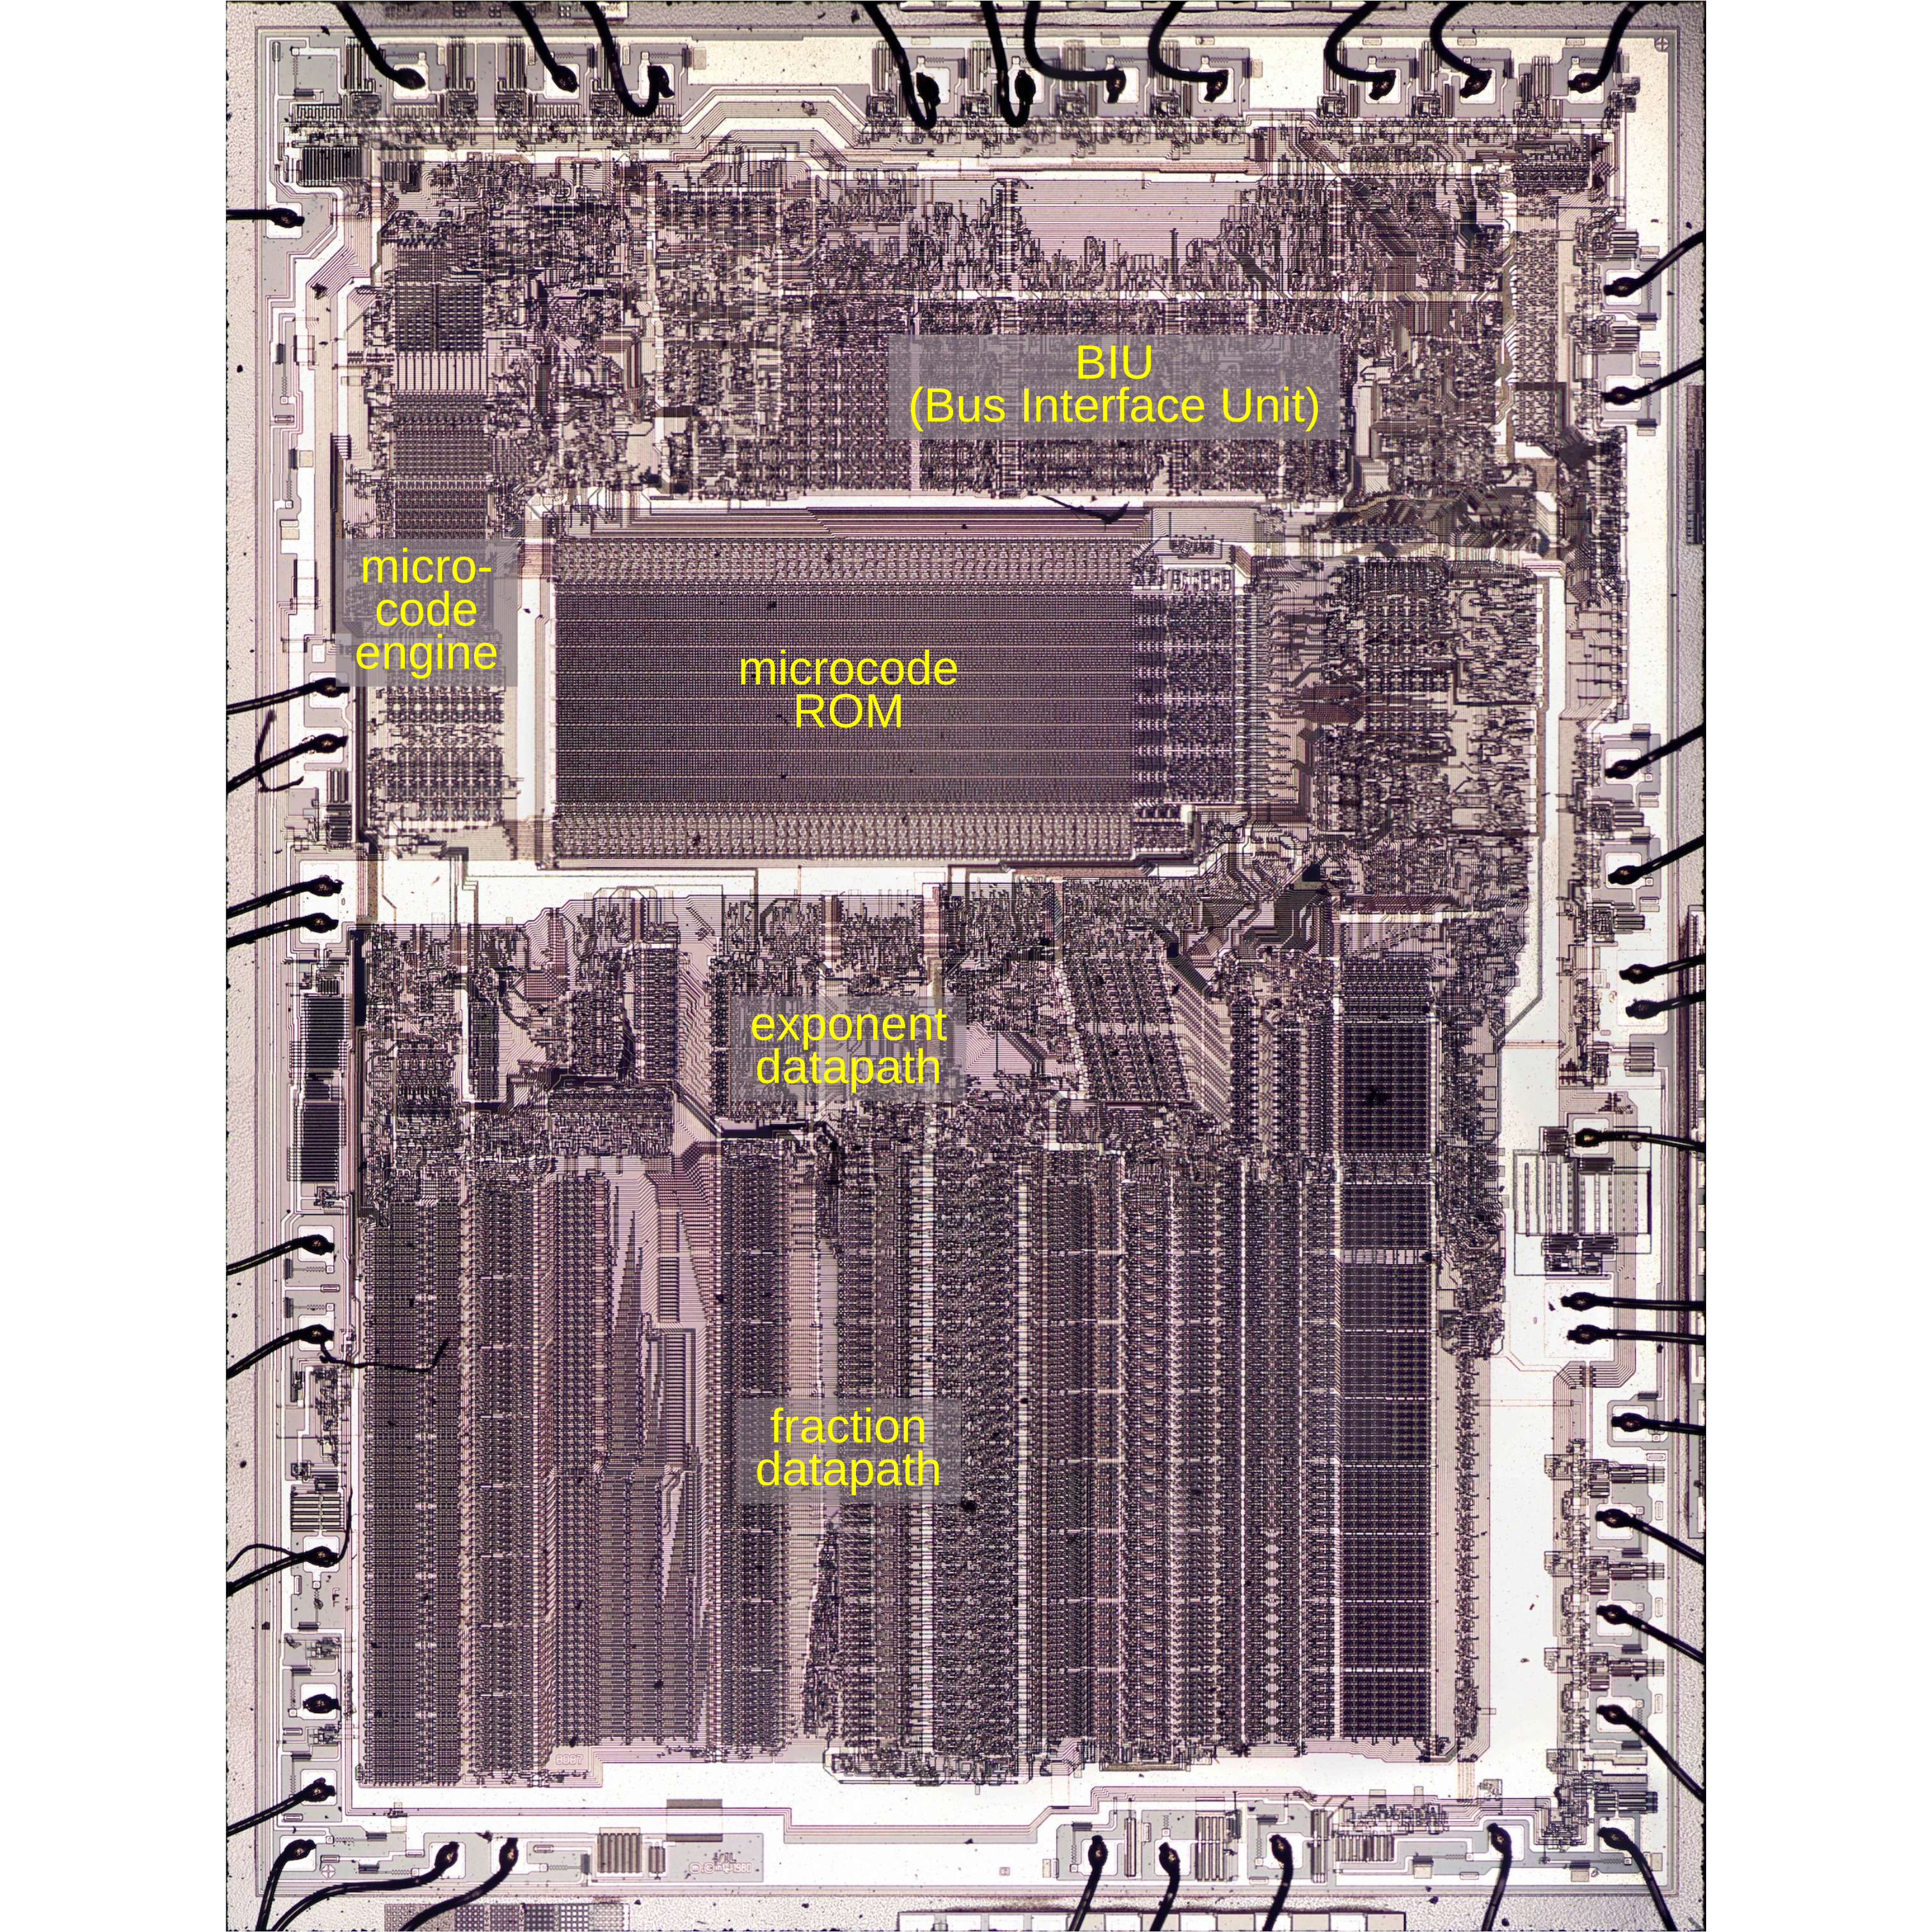
Zooming in on the bottom part of the chip shows the datapath circuitry; I've highlighted the relevant parts below.1 The exponent ROM holds various constants. The exponent converter is a specialized circuit that examines exponents, detects special values, and converts between exponent formats.2 The shifter is a large component; it allows a 64-bit3 value to be shifted left or right by arbitrary amounts. (I wrote about the 8087's shifter circuitry here.) The adder is the heart of the 8087's calculations; it is used in a loop for multiplication, division, and square roots. The B register holds one input to the adder, while multiple sources can provide the other input. The sum register holds the adder's output. The eight stack registers and the temporary registers hold floating-point numbers.
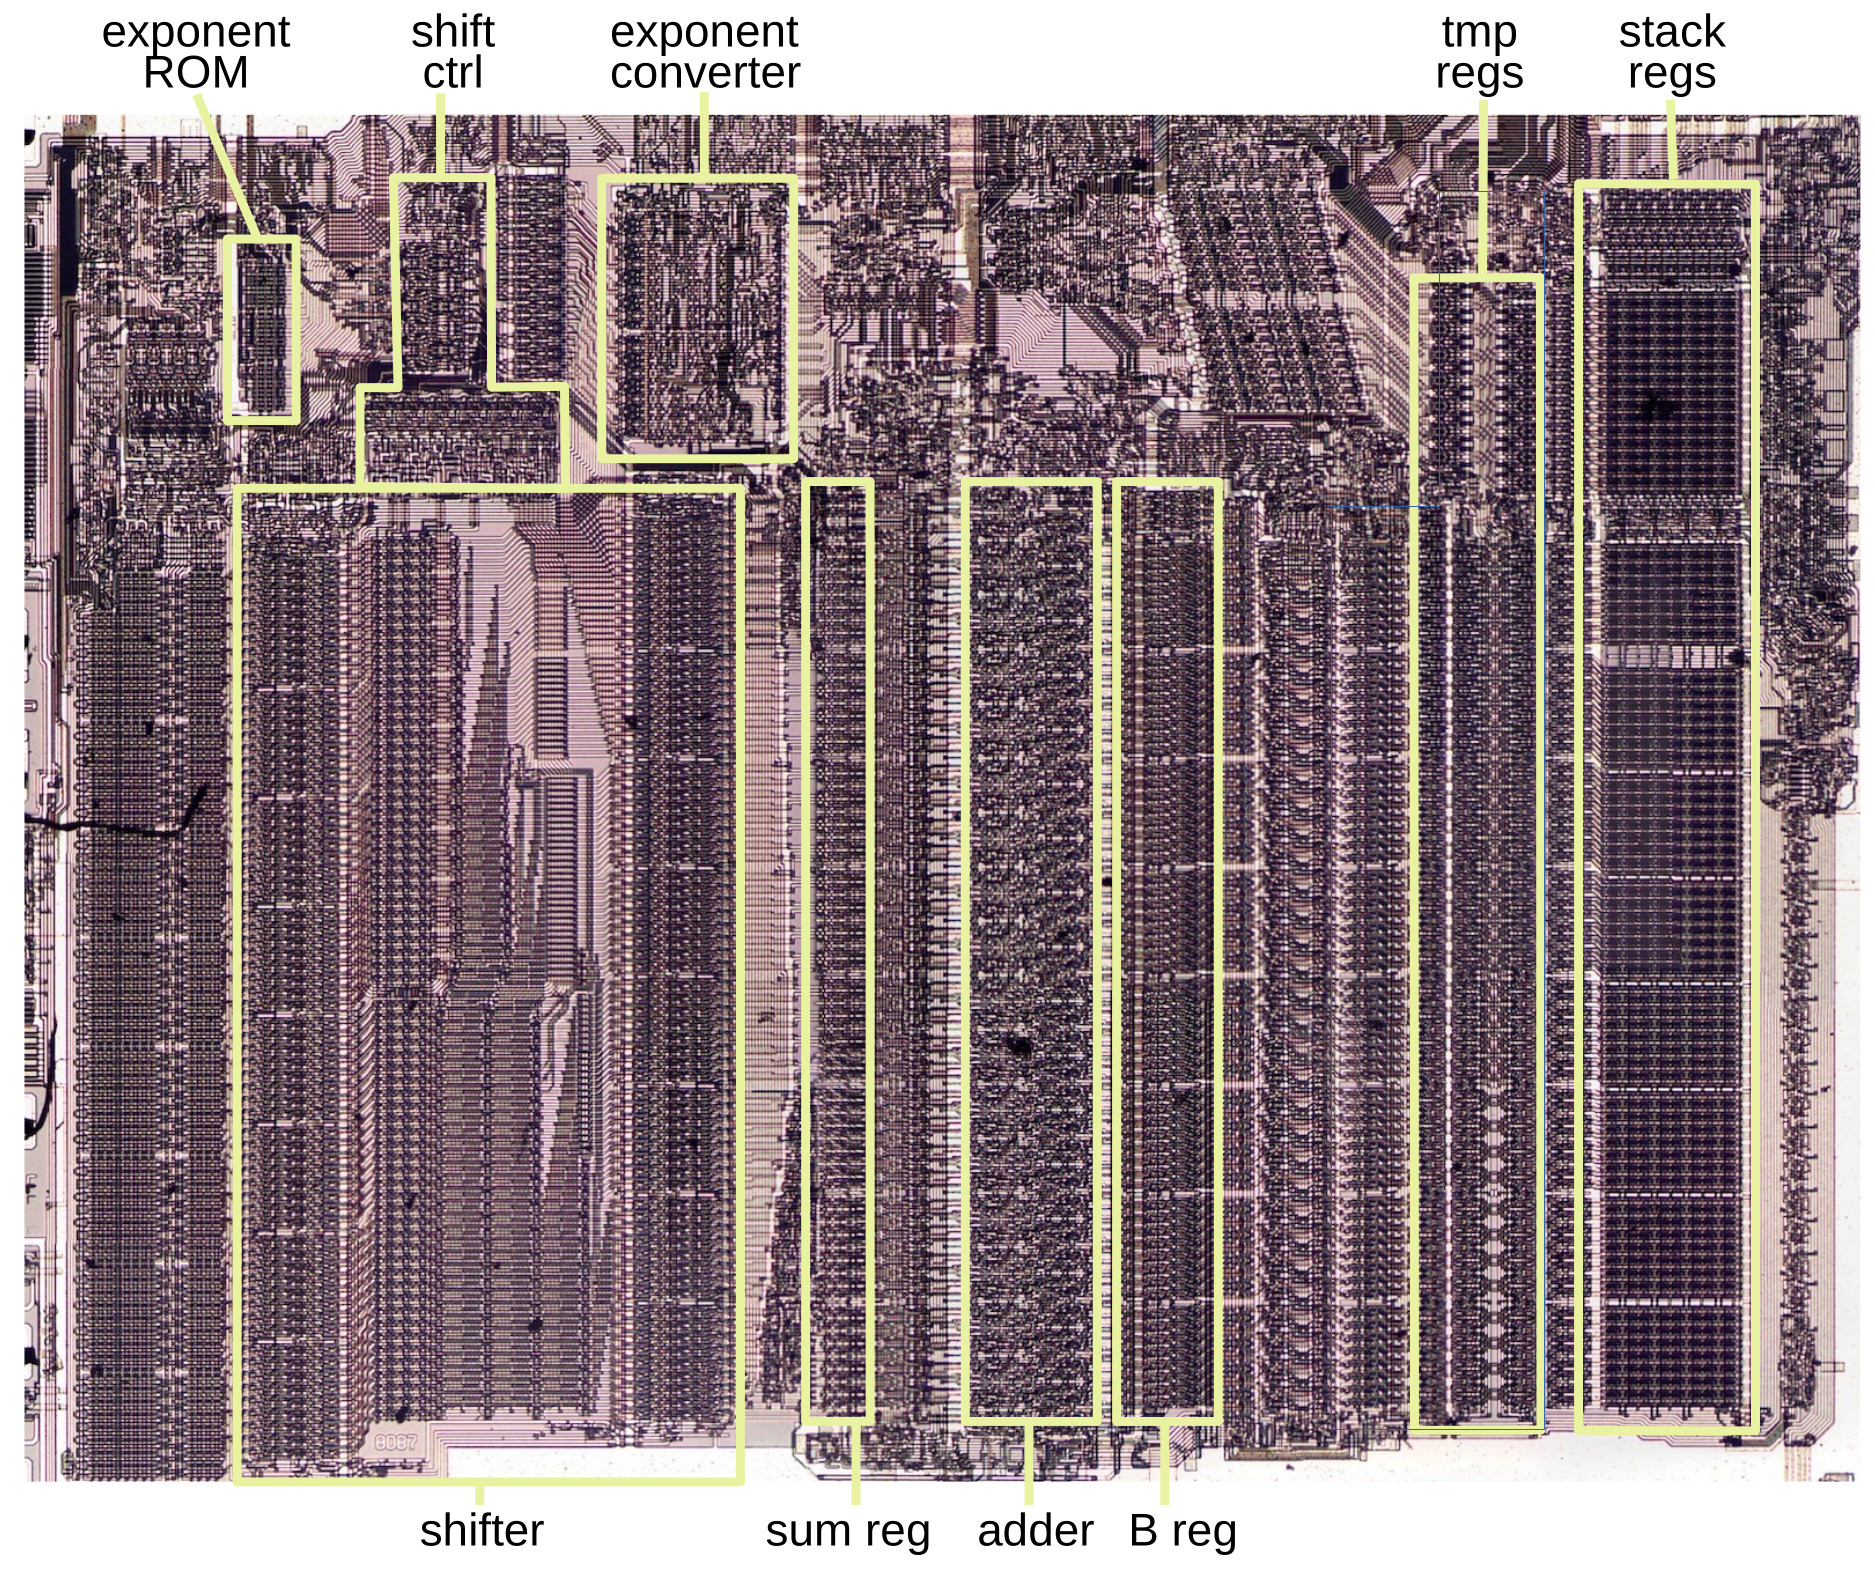
FSCALE.In this section, I'll explain some features of the 8087 that are important for the FSCALE microcode.
To use the 8087, a programmer stores values in its eight internal registers, organized as a stack. Each register holds an 80-bit floating-point number.
To optimize performance,
each value in the register stack has an associated "tag" value, which is mostly invisible to the programmer.
A tag labels a value as valid, special, zero, or empty.
A "normal" floating-point value is tagged as valid. If the floating-point value is infinity, Not a Number (NaN), or a denormalized value,
then it is tagged as special. A zero value is tagged as zero.
Finally, if a register is empty (e.g., its value has been popped off the stack), the register is tagged as empty.
The 8087 also has temporary registers that it uses internally: tmpA, tmpB, and tmpC.
Like the stack registers, tmpA and tmpB are 80-bit registers, along
with two tag bits. However, tmpC only holds a 64-bit significand.
The 8087 supports a variety of data types: floating-point numbers of various sizes, integers, and binary-coded decimal.
But internally, everything is stored as an 80-bit floating-point number called a "temporary real"; for the rest of this article,
I'll only be considering temporary real values.
A number has three parts: the sign bit, the 15-bit exponent, and the 64-bit significand (the fractional part),
In most cases, a floating-point number is represented by sign × significand × 2exponent.
The significand is a 64-bit binary number of the form 1.bbb...:
a leading 1, followed by the binary point (the binary equivalent of the decimal point) and the rest of the bits.5
What makes floating-point numbers useful is that their scope covers the incredibly small to the astronomically large, thanks to the exponent, which
ranges from -16382 to 16383.
One important detail is that the exponent is stored with a "bias" of 16383 added to it. Thus, the stored exponent is always positive, even if the real
exponent is negative.6
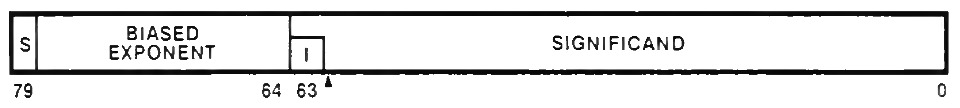
The 8087 supports several types of numbers that are represented as special cases with special exponents, as shown below. Zero and infinity have both positive and negative values. "Not a Number" (NaN) represents values that don't make sense, such as 0/0 or sqrt(-1); NaN has a large number of representations, not a single value. The 8087 also supports denormalized and unnormalized values, which are extremely small values where the significand doesn't have a leading 1.
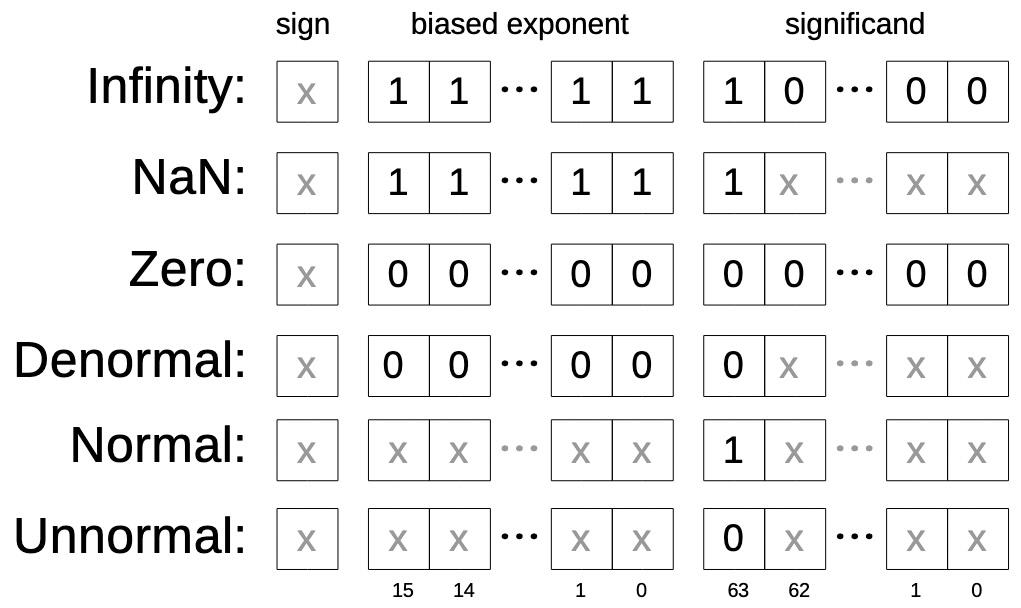
The 8087 has a complicated exception system with six types of exceptions to indicate if something went wrong with an arithmetic operation. The most serious is the "invalid operation", indicating that the operation does not make sense, such as 0/0 or ∞-∞. It also includes accesses to an empty register (stack overflow or underflow) or operations on a NaN value. The 8087 also has an overflow exception if a value is too large to store, an underflow exception if a value is too small, and a divide-by-zero exception (excluding 0/0). A denormalized operand exception indicates that the result is too small to store as a normal value, but can be stored as a denormalized value. Finally, a precision exception indicates that a value cannot be represented exactly and must be rounded. (Precision exceptions are very common; even 1/10 will yield one.)
The 8087 provides fine-grain control over each exception type, specified by bits in the control register. If an exception is unmasked, the 8087 sends an interrupt to the 8086 processor, which handles the problem in software, for instance by terminating the program or logging an error. Alternatively, the exception can be masked and the 8087 will continue execution as best it can. For instance, an invalid result will be replaced by NaN, while an overflow or divide-by-zero will be replaced by infinity. A precision exception will result in rounding. The point of masked exceptions is that calculations continue, yielding an answer that is as accurate as possible; in most cases, this is what the programmer wants.
These features make the 8087 flexible and provide accuracy, but they also make the microcode much more complicated, since the combinations of special cases need to be handled appropriately.
Executing an 8087 instruction can require hundreds of internal steps to compute the result. These steps are implemented in microcode with micro-instructions that specify each step of the algorithm. (Keep in mind the two levels of instructions: the assembly language instructions used by a programmer and the undocumented low-level micro-instructions inside the chip.) The microcode ROM holds the 1648 micro-instructions that implement the 8087's instruction set. I'm working with the Opcode Collective to reverse-engineer the micro-instructions and fully understand the microcode (link).
The 8087's micro-instructions are complicated, with many corner cases and ad hoc functions, but I'll provide a simplified overview. Each micro-instruction consists of 16 bits, as shown below. The first three bits specify the micro-instruction's type, which controls the meaning of the remaining bits. The first type is a transfer operation, which transfers data from one internal register to another. The two fields specify the source and destination. The three remaining bits are used for various special cases. Next is a shift operation, which uses the barrel shifter to shift a value left or right. The third type of micro-instruction controls the adder (which can also subtract). The miscellaneous instructions include stack pointer operations, tag modification, exceptions, and subroutine return. The far jump and far call micro-instructions perform a jump or subroutine call to a target micro-address in a fixed list. The condition field allows conditional jumps/calls/returns based on numerous conditions, while the last bit inverts the condition. A local jump is a relative jump to a nearby micro-instruction.
FSCALE microcodeWhen the 8087 starts executing an instruction, the instruction decoder circuitry determines the starting address of the microcode corresponding to the instruction.
This 11-bit address is loaded into the microcode engine, which starts executing the microcode.7
The microcode for FSCALE (shown below) starts at decimal address 748.8
The idea behind FSCALE is straightforward: if you want to scale a floating-point number by 2N (for an integer N),
you add N to the number's exponent.
This allows you to multiply or divide by a power of two much faster than using the full floating-point multiplication operation.
However, the microcode for FSCALE is unexpectedly complicated and uses several microcode subroutines.
In brief, the microcode first checks for arguments that are zero and then handles other special arguments.
It converts the scale argument to an integer and adds it to the exponent. Finally, it handles any overflow or underflow.
In more detail,
the microcode routine starts by moving the first argument from the top of the stack (st(0)) to the tmpA temporary register.
If the argument is zero, the routine immediately returns. (Thus, scaling 0 by anything—even NaN—will give a result of 0.)
Next, the second value on the stack (the second argument) is moved to the tmpB temporary register.
Likewise, the code returns if this value is 0, so scaling anything by 0 leaves the value unchanged.9
Next, a constant value is selected; selecting a constant and using it are two separate micro-instructions.
(The 8087 has separate ROMs for 16-bit exponent constants and 67-bit significand constants; this one is an exponent constant.)
In the normal case, execution jumps to address #0763, skipping the call to subroutine SPECIAL_TMPS.
FSCALE:
#0748 st(0) -> tmpA        Input argument from top of stack
#0749 jmp #0776 if tmpA:tag ZERO Bail if 0
#0750 stackPtr++
#0751 st(0) -> tmpB        Scale argument from stack(1)
#0752 stackPtr--
#0753 jmp #0776 if tmpB:tag ZERO Bail if 0
#0754 expconst 0x403e      Const 403e: exp shift to convert to int
#0755 jmp #0763 if not tmp empty/special/div
#0756 call SPECIAL_TMPS    Special handling
#0757 jmp #0762 if flag
#0758 jmp #0761 if not tmpB:tag SPECIAL
#0759 except:invalid       Invalid exception, use NaN
#0760 NaN -> tmpA
#0761 jmp #0776 if intr
#0762 jmp #0775 if expConv[0] Return tmpA if expConv set, otherwise continue
#0763 tmpB:exp -> Breg     Normal path
#0764 tmpB:sign,exp -> expConv ExpConv will test tmpB's sign
#0765 expConst -> tmpC     Const 403e
#0766 adder: tmpC - Breg cin=1 403e-exp is amount to shift to convert tmpB to int
#0767 sumreg:frac -> shiftcount Store in shifter control
#0768 shift tmpB:frac R count byte bit Perform the shift
#0769 shift R -> Breg      Breg holds scale argument as an int
#0770 jmp #0777 if neg     Negative Breg needs separate handling
#0771 adder: tmpA:exp + Breg cin=0 Add the scale to the exponent
#0772 sumreg:frac -> expConv Put result in expConv to check
#0773 sumreg:frac -> tmpA:exp Update exponent with sum
#0774 call NONNORMAL_RESULT if not exp normal Handle overflow/underflow
#0775 tmpA -> st(0)        Save result back to stack
#0776 RNI                  Done: Run Next Instruction
#0777 adder: tmpA:exp - Breg cin=1 Subtract Breg
#0778 jmp #0772            Continue processing
Continuing at #0763, the second argument is converted from a float to an integer, which takes a few steps.
For example, suppose the argument is 9, which in floating point is 1.001×23.
The significand bits 1000 are "left justified", but for an integer, these bits need to be "right justified" by shifting them to the right.
In general, if the exponent is n, the significand is shifted right by 63-n bits.
But recall that the exponent is biased by 16383. Thus, the significand must be shifted right by 63-(exp-16383) bits, that is 0x403e-exp bits.
(This explains the constant 0x403e earlier in the microcode.)
In the microcode, the subtraction takes several steps.
At #0763, the exponent of the second argument is moved to the B register, one of the inputs to the adder (completely different from tmpB).10
Next, the sign and exponent are moved to the exponent converter, a circuit that, among other things, tests for overflow.
Next, the constant 0x403e (selected back at #0754) is moved to the tmpC register.
At #0766, the adder is activated, subtracting the exponent from the constant.11
The adder puts the result into the sum register, and this value is copied to the shift count register, which controls the shifter.
This value indicates how many bits the second argument must be shifted to convert it to an integer.
At #0768, the shifter is activated to shift by the desired amount, using both the bit shift part and the byte shift part.
As with the adder, activating the shifter and reading the result are separate micro-instructions; the result is put into the B register.
The core part of the FSCALE instruction is finally performed at #0771, adding the second argument to the first argument's exponent.
The adder is activated to add the B register value (the scale) to the exponent, and the updated value is stored in tmpA's exponent.
(Except if the scale factor is negative, it is subtracted via the #0777 path.)12
The value is also sent to the exponent converter circuit, which checks the exponent for overflow or underflow; if so, subroutine NONNORMAL_RESULT is called.
But in the normal case, the updated value is copied from tmpA to the top-of-stack register st(0).
Finally, RNI (Run Next Instruction) indicates that the microcode routine is done and the instruction is completed.
Thus, even in the straightforward case, FSCALE takes about 22 micro-instructions.
What happens if an argument accesses an empty stack location (i.e. stack underflow) or is a special value (infinity, denorm, NaN)?
These cases are handled by a micro-subroutine that I'll call SPECIAL_TMPS15 because it processes special values in tmpA and/or tmpB.
This subroutine is a general-purpose routine, used by basic arithmetic operations, FSCALE, FTST (test), and FPREM (partial remainder).
The control flow through SPECIAL_TMPS is rather convoluted since the code must prioritize issues if,
say, one argument is empty and the other is a denorm.
I'll just give a brief summary; see the footnote13 for details.
First, the subroutine converts any denorms to unnorms. Then it checks for access to empty stack locations, raising an exception or interrupt if so.
Then it checks the two arguments again. If either is NaN, an exception or interrupt is triggered. Otherwise, it returns a status indicating the type of arguments.
Unexpectedly, if both arguments are NaN, the code compares the two NaN values and returns the larger.
This behavior may seem very weird, but it's a documented feature.14
You might think that NaN is a single value, but it's actually an enormous family of values.
The idea was that the programmer could use different NaN values to signal where a problem occurs. For instance, you could put a different
NaN in each location of an uninitialized array, so you could tell which position was accessed.
For some reason, the designers of the 8087 decided that if you perform an operation with two different NaNs, the result is the larger one.
Thus, the microcode needs code that detects if both operands are NaN and computes the larger, using a subtraction for the comparison (#1518).
SPECIAL_TMPS (J5):
#1484 call SPECIAL_VAL if tmpA:tag SPECIAL Handle special values in tmpA/tmpB
#1485 xchg tmp
#1486 call SPECIAL_VAL if tmpA:tag SPECIAL Handle tmpB special
#1487 xchg tmp
#1488 1 -> flag            Flag=1 by default
#1489 jmp #1500 if not tmp empty/special/div 0 -> expConv if tmps okay
#1490 1 -> expConv
#1491 jmp #1497 if not tmpA/B empty
#1492 except:invalid       Invalid if either empty
#1493 jmp #1525 if compare instruction No NaN for comparison
#1494 jmp #1511 if intr    Return if interrupt not masked
#1495 NaN -> tmpA          NaN if interrupt masked
#1496 return
#1497 jmp #1502 if tmpA:tag SPECIAL Special cases
#1498 jmp #1505 if tmpB:tag SPECIAL
#1499 0 -> flag            Div normal path:
#1500 zero -> expConv      Return flag 0, expConv 0
#1501 return
#1502 call SPECIAL_VAL     TmpA special
#1503 jmp #1512 if not flag Jump if NaN, fallthrough if infinity
#1504 jmp #1509 if not tmpB:tag SPECIAL
#1505 xchg tmp             TmpB special
#1506 call SPECIAL_VAL
#1507 xchg tmp
#1508 jmp #1521 if not flag Jump if NaN, return if infinity
#1509 0 -> flag            Clear flag, return
#1510 return
#1511 RNI                  End instruction with interrupt
#1512 jmp #1522 if not tmpB:tag SPECIAL TmpA NaN, now check tmpB
#1513 xchg tmp
#1514 call SPECIAL_VAL     Check tmpB
#1515 xchg tmp
#1516 jmp #1522 if flag    Jump if tmpB is not NaN
#1517 except:invalid       Invalid exception
#1518 tmpB:frac -> Breg    Both args are NaN, find larger
#1519 adder: tmpA:frac - Breg cin=1
#1520 jmp #1522 if adder sign See if tmpA
#1521 tmpB -> tmpA         Take larger
#1522 except:invalid       Invalid exception
#1523 jmp #1525 if compare instruction No interrupt for comparison instruction
#1524 jmp #1511 if intr    End instruction with interrupt
#1525 1 -> flag            Return with flag set
#1526 return               End of J5
This subroutine makes heavy use of a helper subroutine, SPECIAL_VAL,16 that processes one argument.
The helper converts a denormalized argument to an unnormalized argument, raising an exception or interrupt as appropriate. It also flags an input of infinity.
The hardware for the micro-instruction that exchanges tmpA and tmpB at #1485 is interesting.
Instead of physically moving the values between the two registers, the micro-instruction toggles a flip-flop that exchanges the meaning of tmpA and tmpB.
That is, if the flip-flop is set, a reference to tmpA goes to tmpB and vice versa.
(This is a standard trick in microprocessors; the Intel 8080's XCHG instruction exchanges the DE and HL registers in a similar way.
The Z80 uses the same trick for the EX and EXX instructions to exchange the regular register set with the secondary register set.)
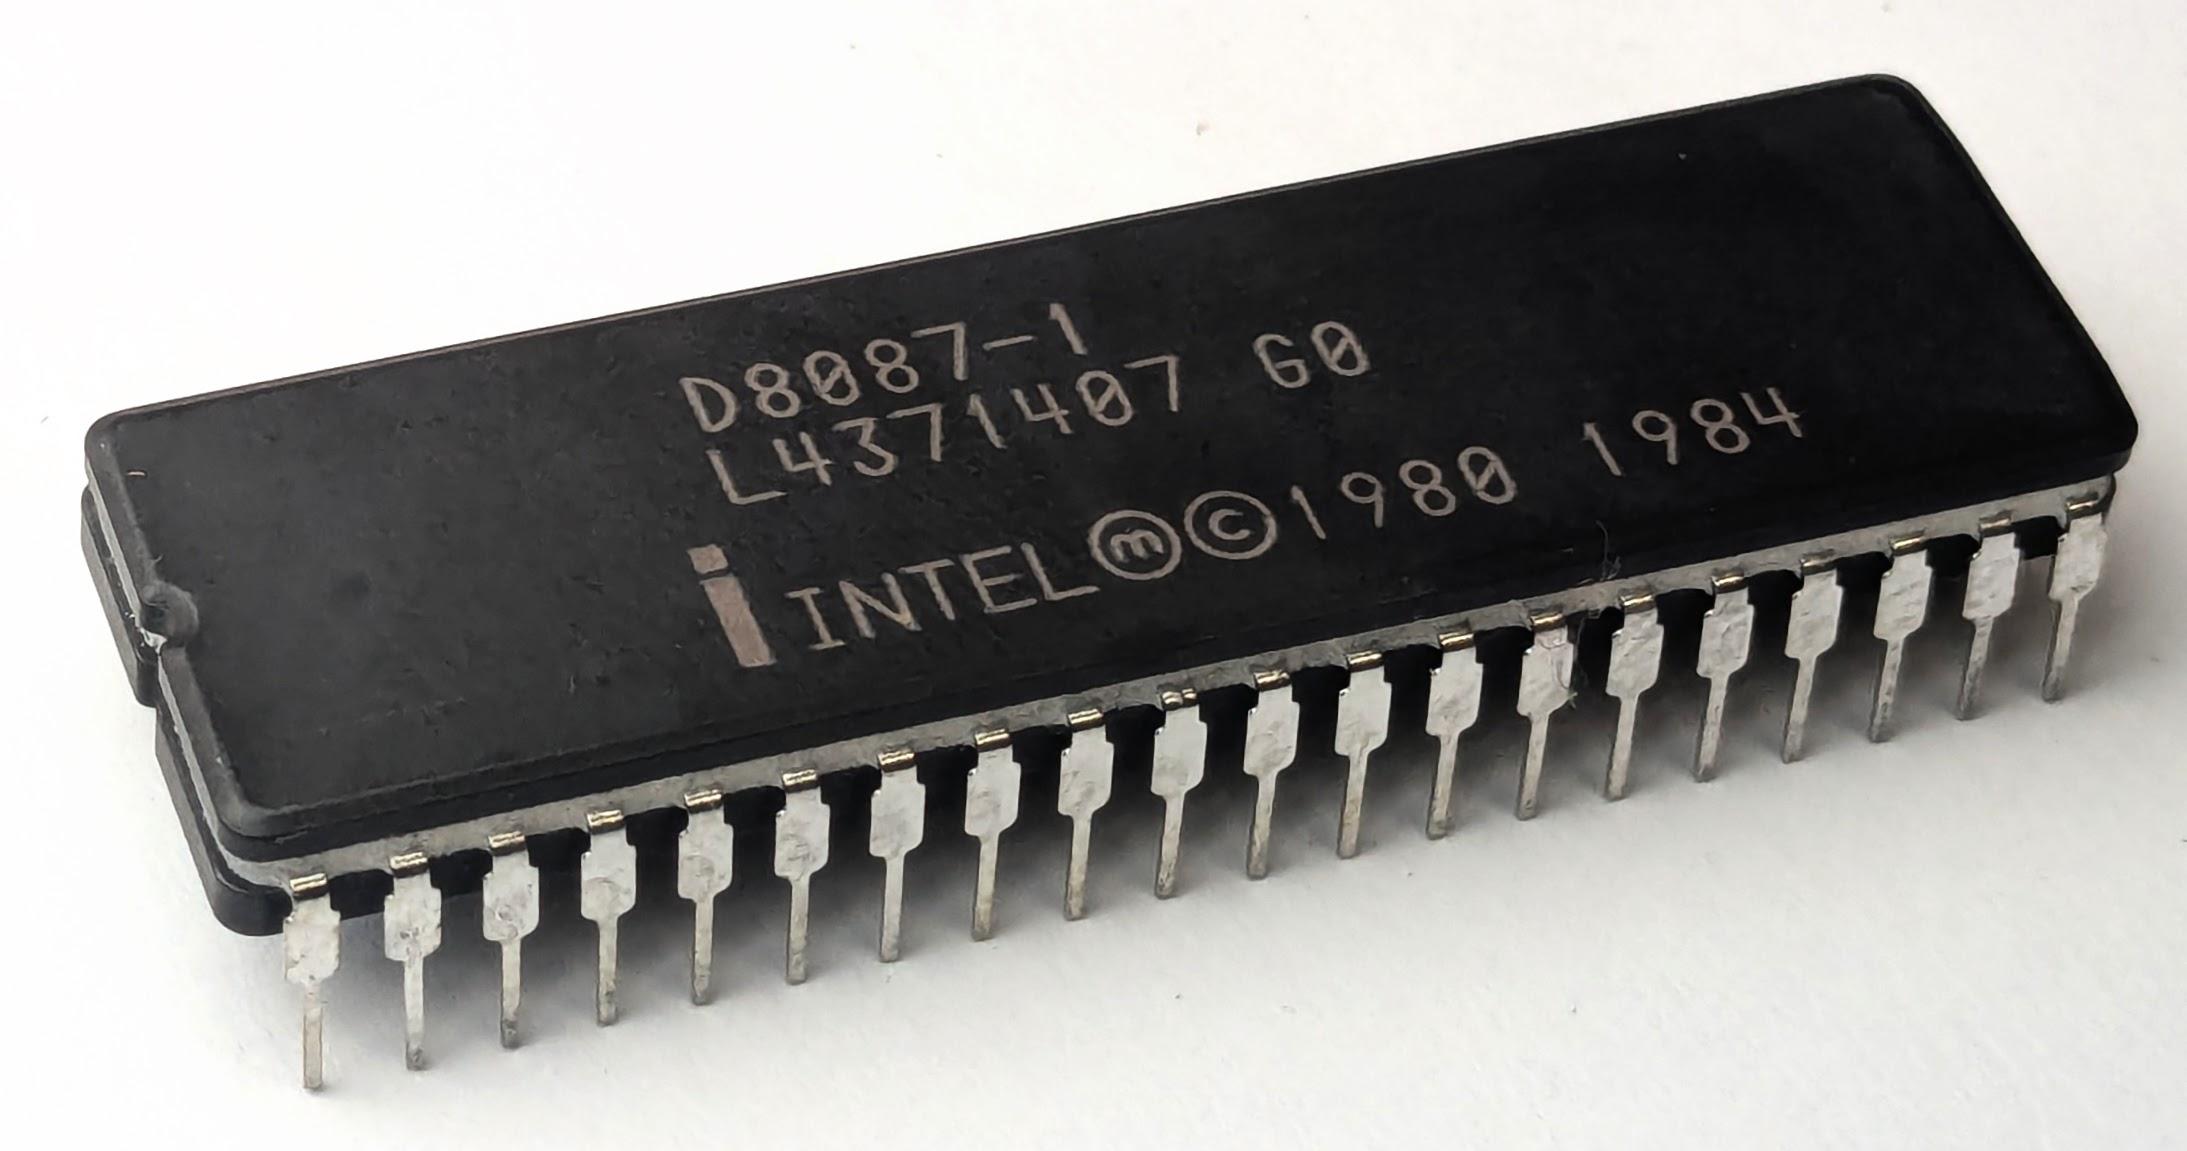
If you take a very large number and scale it larger, you can end up with overflow. If you take a very small number
and scale it smaller, you can end up with a denormalized number or underflow.
This will trigger an overflow, denorm, or underflow exception, and an interrupt if unmasked.
Moreover, the 8087 supports four rounding modes:
round to nearest valid value, round down (toward -∞), round up (toward +∞), or round (chop) toward zero.
Depending on the rounding mode, an overflow can result in either ∞ or the largest possible floating-point number.
Similarly, an underflow can result in either zero or the smallest possible floating-point number.
And depending on the infinity mode (affine or projective), infinity can be either signed or unsigned.
Thus, the FSCALE microcode needs to handle many special cases for the result.
The subroutine to handle a non-normal result in tmpA is below.
One interesting micro-instruction is update overflow/underflow exceptions, which triggers an exception if appropriate.
For most exceptions, a micro-instruction triggers the exception (for example, except:precision at #0346).
But for the overflow and underflow exceptions, the microcode delegates the task to hardware.
Specifically, the 8087's "exponent converter" circuit examines the exponent to see if an overflow
or underflow exists, based on the selected floating-point precision.
The micro-instruction sets the overflow and underflow flags based on these values.
Thus, a complex task is performed by a single microcode instruction, thanks to the hardware support of the exponent converter.
NONNORMAL_RESULT (J16):
#0318 return if tmpA:tag ZERO Handle non-normal result
#0319 update overflow/underflow exceptions Trigger exceptions if exp conv says to
#0320 expconst 0x6000      The interrupt bias constant 0x6000
#0321 jmp #0329 if not intr
#0322 expConst -> Breg     Interrupt path
#0323 jmp #0326 if neg
#0324 adder: tmpA:exp + Breg cin=0 Add bias for underflow
#0325 jmp #0327
#0326 adder: tmpA:exp - Breg cin=1 Subtract for bias overflow
#0327 sumreg:frac -> tmpA:exp New exponent to tmpA
#0328 return               Interrupt, so done
#0329 jmp #0344 if neg     Masked exception
#0330 tmpA:exp -> Breg     Underflow
#0331 adder: 1 - Breg cin=1 Amount to shift denormal
#0332 call CREATE_DENORM   Create a denormal
#0333 adder: zero + Breg cin=0, roundmode Add zero to round
#0334 call ADJUST_PRECISION Adjust to specified precision
#0335 jmp #0340 if Sum register is zero If zero, return +/- zero as appropriate
#0336 zero -> tmpA:exp     Denorm: exponent is 0
#0337 sumreg:frac -> tmpA:frac Save denorm fraction
#0338 special -> tmpA tag  Tag denom as special
#0339 return
#0340 tmpA sign -> sign latch Return +/- zero
#0341 zero -> tmpA
#0342 sign latch -> tmpA sign
#0343 return
#0344 NaN/Inf -> tmpA:exp  Overflow: maybe return infinity
#0345 tmpA:frac -> tmpB:frac Save tmpA frac in tmpB
#0346 except:precision     Set precision exception
#0347 Inf -> tmpA:frac     Put infinity in frac
#0348 special -> tmpA tag  Mark infinity as special
#0349 return if not round chop If rounding up, return infinity
#0350 1 -> Breg            Return max float: adjust down
#0351 adder: tmpA:exp - Breg cin=1
#0352 sumreg:frac -> tmpA:exp Exp=7fff-1=7ffe
#0353 adder: zero - Breg cin=1
#0354 sumreg:frac -> tmpA:frac Frac 0-1 = ff...ff
#0355 norm -> tmpA tag     Normal value
#0356 return if tmpB:frac[63] Return max float unless unnorm
#0357 tmpB:frac -> tmpA:frac Return original tmpA frac
#0358 return
The 8087 has interesting behavior if an overflow or underflow is unmasked and an interrupt occurs.
The idea is to let the interrupt handler know what the exponent should have been.
However, the proper value can't be used since it is too big or too small to fit in the exponent field (which is why the exception occurred).
The solution is to add or subtract the constant 0x6000, resulting in an exponent that fits.
The interrupt handler can subtract or add this constant to get the correct exponent.
Lines #0322 to 0328 perform this addition or subtraction.
For a masked underflow, a denorm value is created by the subroutine CREATE_DENORM.
The value is rounded to the specified precision by ADJUST_PRECISION.
Finally, if the value is too small for a denorm, the value +0 or -0 is returned as appropriate.
For a masked overflow, the 8087 either returns Infinity or the largest-possible float, depending on the specified rounding mode.
Infinity is represented by an exponent of all 1s, and a significand of 1000...; these values are loaded directly onto the bus by transistors.
The maximum float, however, is computed: 1 is subtracted from the infinity exponent, and 1 is subtracted from a zero significand.
One controversial feature of the 8087 is denormals, numbers that are smaller than "regular" floats. Recall that floating-point numbers have a significand with the first bit set to 1. But what happens if you hit the smallest possible exponent and want an even smaller number? The 8087 lets you break the rule that the significand starts with 1, producing smaller numbers known as denormalized numbers or denorms. Denorms significantly extend the range, providing numbers up to a factor of 263 smaller. However, denorms don't have as much precision since the upper bits are "wasted". Moreover, calculations with denorms can be substantially slower because special handling is required.
The diagram above shows a normal number with the minimum possible exponent (-16382, which is 1 after biasing). Dividing the number by 8 (or scaling by -3) creates a denorm since the exponent can't be reduced any further. Instead, the significand is shifted 3 bits to the right. The exponent is replaced with the special value 0, indicating that the number is a denorm.
In the 8087, denorms are created by a microcode subroutine that I'll call CREATE_DENORM;
it is used by many arithmetic operations, not just FSCALE.
This subroutine takes a normal number and a shift amount. By shifting the normal number (as in the example above), it creates a denormalized number.
The microcode (below) uses the exponent converter to check if the shift is 64 or more.
If so, there will be nothing left after the shift, so zero is returned.
Otherwise, the value is shifted to the right and the denorm is stored in the B register.
CREATE_DENORM (J20):
#0522 sumreg:frac -> expConv Create denorm
#0523 sumreg:frac -> shiftcount Number of bits to shift
#0524 jmp #0528 if exponent[6:14] == 0 Jump if
#0525 zero -> Breg         No bits left, use zero
#0526 shift tmpA:frac L 0 bytes, 0 bits Run through shifter?
#0527 jmp #0532
#0528 shift tmpA:frac R count byte bit Shift right by the specified amount
#0529 shift R -> Breg      Result to Breg
#0530 shift tmpA:frac L ~count byte bit Now shift back for sticky test
#0531 NOP                  Wait for shifter
#0532 rounding(h) -> Breg[grs] Store the three rounding bits in the Breg
#0533 return
But why is the value then shifted to the left (#0530)?
The purpose of this is to get the rounding bits.
One of the principles of the 8087 is to get rounding correct, which is a lot harder than it seems.
In order to decide how to round up a number, you need to keep track of an impossibly large number of bits.
For instance, if you calculate 1 + 0 and round up, you get 1.
But if you calculate, say, 1 + 2-10000 and round up, you get a float a bit higher than 1.
The problem is how do you distinguish the two sums before rounding, without storing thousands of bits?
The trick is that the 8087 keeps three bits for use in rounding: the "guard" bit, the "round" bit, and the "sticky" bit. If you consider a "tail" of bits to the right of the significand, the guard bit is the most significant bit of the tail, followed by the round bit. The sticky bit is special: it is the OR of all the remaining bits in the tail, indicating if any of them are 1. Thus, 1 + 2-10000 has the sticky bit set, while 1 + 0 does not, so the two values can be rounded up differently. To generate the sticky bit, the 8087 uses a very large 64-bit NOR gate that tests the tail bits in parallel.
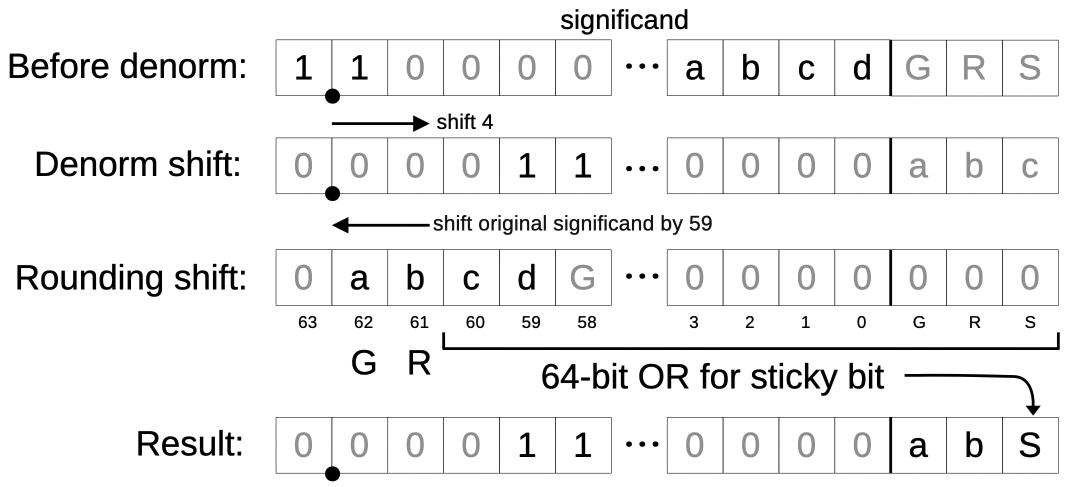
When a number is shifted to the right (e.g., when creating a denormal), bits are lost off the right.
To generate the rounding bits,
the value is shifted to the left, keeping all the tail bits that will eventually be discarded, and discarding the bits that will be in the final significand.
The top two bits go into the guard and round bits, while the remaining bits are ORed together to generate the sticky bit from the rest.17
The diagram above is an example of this process. Suppose the value is being shifted to the right by 4 bits. The tail bits abcd (or at least d) will get lost in the shift.
The rounding bits are computed by shifting the original significand to the right by 59 bits (the complement of 4). Bit 62 (a) becomes the new guard bit,
bit 61 (b) becomes the new round bit, and the OR of the remaining 64 bits becomes the new sticky bit. (Note that the old guard, round, and sticky bits get
ORed in too, so they aren't lost.)
Merging the significand from the first shift with the rounding bits from the second shift produces the desired result.
Although the 8087 supports three lengths of floats, it performs all calculations with 80-bit "temporary reals".
At the end of an instruction, it converts the result to the desired length. (As a consequence, most instructions aren't any faster if you use a shorter float.)
A microcode subroutine, which I call ADJUST_PRECISION, converts the result to the precision that is specified in the 8087's control word,
using the specified rounding mode.
This subroutine is used by most of the arithmetic instructions.
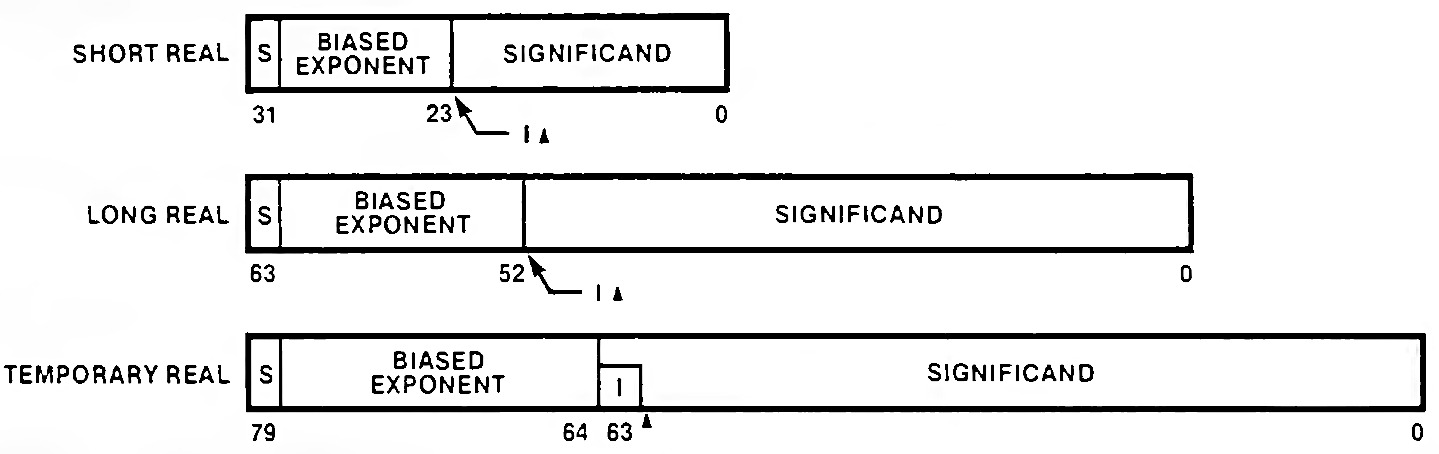
The first code path handles temporary reals (which have 64 bits of precision). The control word specifies one of four rounding modes. However, there are only two actions that can be taken for a particular significand: either round down (chop) or round up (chop and increment by 1). This decision is made by complicated logic circuits that examine the rounding bits, the rounding mode, and the sign to determine whether to round up or down. This simplifies the microcode but makes the hardware more complicated. The microcode performs a conditional return, returning if the significand doesn't need to be rounded up. Otherwise, the microcode increments the significand by adding 0 with a carry-in. It then checks for overflow, in which case it replaces the value with Infinity and sets a special flag.18
ADJUST_PRECISION (J11):
#0299 jmp #0306 if not precision64
#0300 return if not round up, update CC1 Update condition code, maybe return
#0301 adder: sumreg:frac + 0 cin=1 Add 1 to round up
#0302 return if not sumreg[64]
#0303 Inf -> sumreg:frac,sign Return infinity if overflow
#0304 2count++             Set special flag
#0305 return
#0306 23/52 -> shiftcount  Short or long real: get appropriate shift
#0307 shift sumreg:frac,rnd L count byte bit sticky Shift to generate rounding bits
#0308 NOP                  Wait for shifter to complete
#0309 rounding(H) -> sumreg[grs] Store rounding bits
#0310 shift sumreg:frac R ~count byte bit Shift right to drop excess bits
#0311 shift R -> sumreg:frac
#0312 jmp #0314 if not round up, update CC1 Update condition code
#0313 adder: sumreg:frac + 0 cin=1 Round up if appropriate
#0314 shift sumreg:frac L ~count byte bit Shift left to realign
#0315 shift L -> sumreg:frac,sign
#0316 return if not sumreg[64] Return if not overflow
#0317 jmp #0303            Return infinity
The code is more complicated when
returning a smaller precision (short real or long real), since the significand must be shortened.
First, the code at #0306 loads the shifter with either 23 or 52, depending on the precision specified in the control word, and then shifts the
value left. This produces the rounding bits as in the previous section.
Next, the value is shifted to the right, shortening it to the desired length.
As before, the significand is incremented or not, depending on whether it should be rounded up or not.
Finally, the value is shifted back to the left, so the most significant bit of the significand is on the left.
As before, if rounding up caused an overflow, infinity is returned.
One bizarre feature is that a jump with the "round up" conditional also has a side effect of updating the 8087's programmer-visible condition code register (CC1), indicating
if the result was rounded up or down.
That is, the 8087 has extra circuitry to detect this specific condition and load the value into the condition code latch.
Strangely, the 8087 documentation doesn't describe this condition code action; Intel didn't document it until the 387SX floating-point chip in 1987.19
Floating-point has a long history before the 8087. For instance, the IBM System/360 mainframes (1964) supported 32-bit and 64-bit floating-point numbers. In 1977, AMD introduced the Am9511 floating-point chip, supporting 16- and 32-bit floating-point numbers, along with transcendental functions. What made the 8087 revolutionary is that it was carefully designed to be as mathematically accurate as possible, largely thanks to numerical expert William Kahan. (The 8087 led to the IEEE 754 Standard, now used by almost every computer and ending the anarchy of incompatible floating-point standards.)
The 8087 ended up extraordinarily complicated with three different sizes of floating-point numbers, four sizes of integers, four rounding modes, infinity modes, a collection of exceptions that could be masked or unmasked, denormalized and unnormalized numbers, signed and unsigned infinities, signed zeros, and a whole family of Not-a-Numbers. These features combine, yielding many corner cases. The 8087 deals with this complexity both through specialized circuits and through tangled microcode.
How complicated is the 8087? For users who didn't have an 8087 chip, Intel sold an 8087 Support Library that exactly emulated the 8087's instructions (but much slower). The emulator took 16K bytes of 8086 code, which was a lot when a full BASIC interpreter could fit in 8K. Another way of looking at this is that the hardware of the 8087 drastically reduced the amount of software required: the 8087 itself used 3.3K of microcode, compared to the 16K for the emulator in 8086 code.
I plan to continue reverse-engineering the 8087 microcode; for updates, follow me on Bluesky (@righto.com), Mastodon (@[email protected]), or RSS. I've been working on this with the members of the "Opcode Collective", especially Smartest Blob and Gloriouscow, who converted the ROM images to microcode data and extensively analyzed the contents. See the 8087 repository on GitHub for more.
The 8087 patents provide some details on the hardware, but unfortunately not the microcode. The patent diagram below shows the architecture of the 8087; I've highlighted the relevant parts. The fraction bus and exponent bus are shown in red. The adder and associated registers are in yellow. (For subtraction, the B register selector selects the complement.) The shifter is in green. The exponent constant ROM and the exponent converter are in orange. The temporary registers and stack registers are in blue.
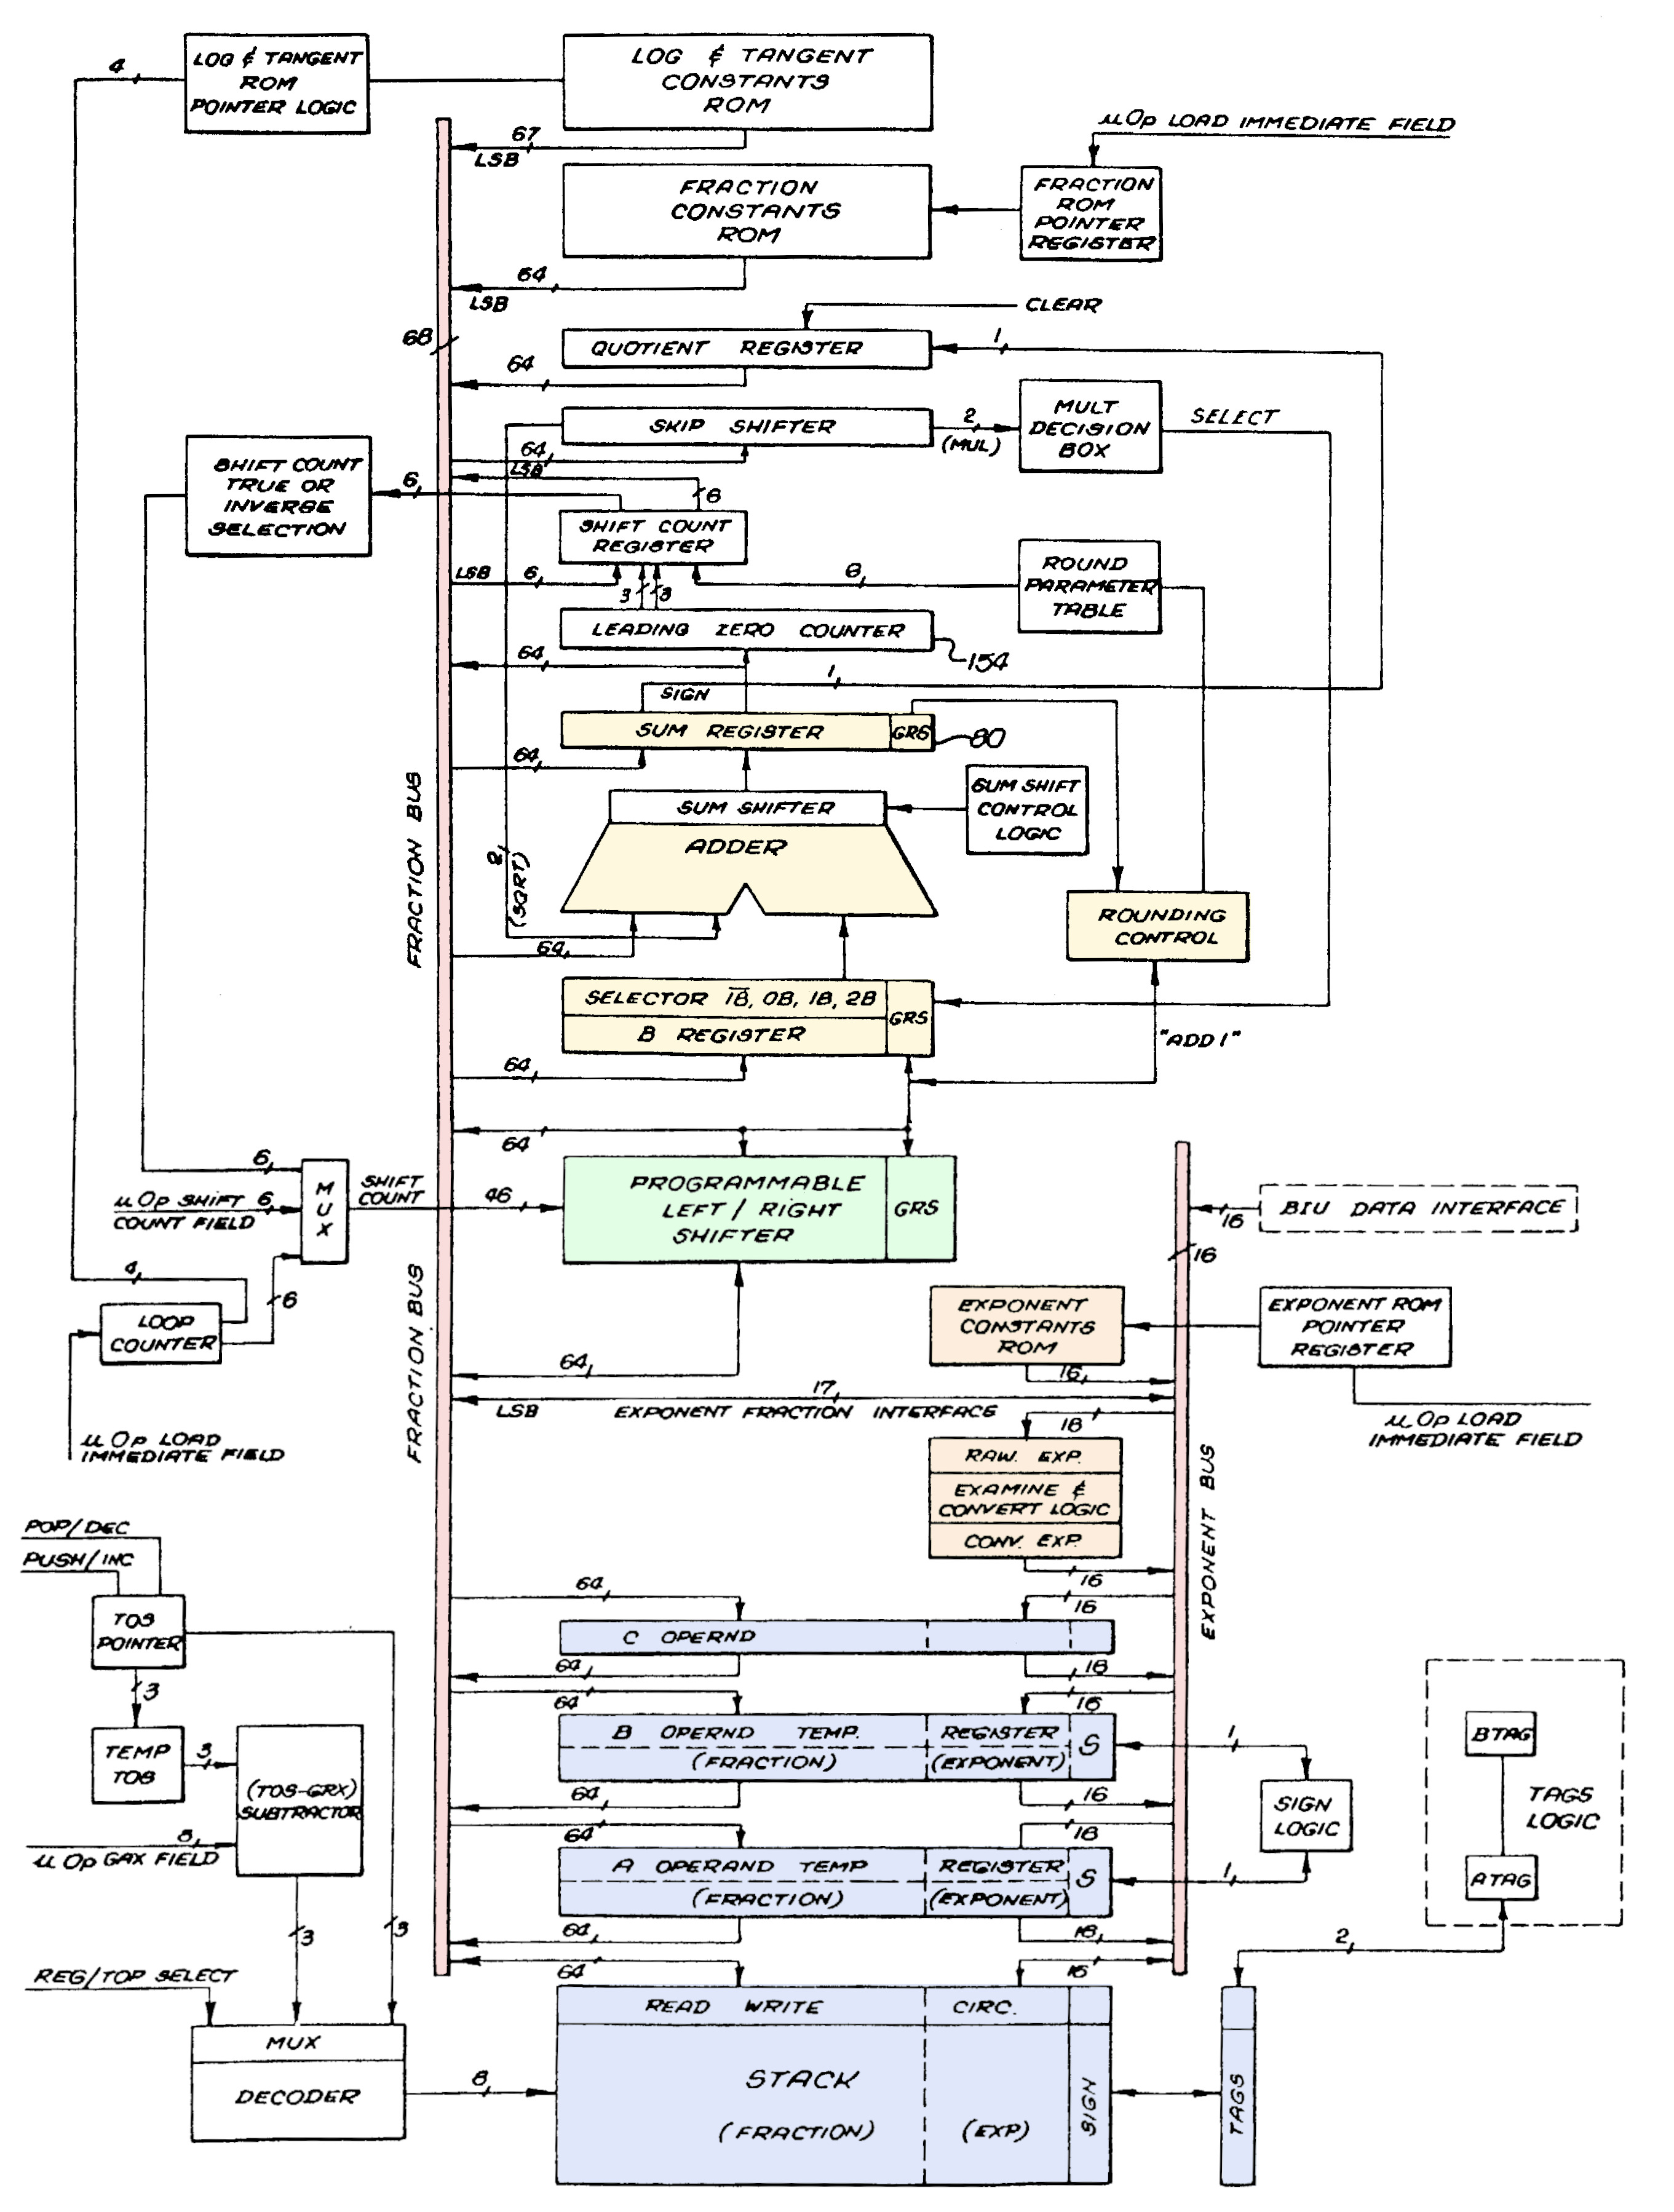
The exponent converter is surprisingly complicated because the 8087 has three different formats for floating-point numbers with three different sizes of exponent fields (8 bits, 11 bits, and 15 bits). Moreover, the different sizes of exponents are stored with different biases. Thus, converting between different sizes of exponents is not trivial. The exponent converter also recognizes overflow and underflow for the different exponent sizes, as well as special values such as infinity and NaN. I plan to describe the exponent converter in more detail later. ↩
The significand in the 8087 is nominally 64 bits wide. However, the 8087 uses three extra low-order bits for rounding, called Guard, Round, and Sticky. These bits ensure that a value is always rounded in the right direction. Some parts of the datapath have additional bits for sign or overflow: the shifter is 68 bits wide, and the adder is 69 bits wide. For the most part, I'll ignore these extra bits and refer to the datapath as 64 bits wide. ↩
The external representations of floating-point numbers have an implied leading one, with only the bits after the binary point explicitly stored. This provides one additional bit of resolution "for free". The internal 80-bit representation, however, has an explicit leading one to simplify calculations. ↩
One reason that the exponents are biased is that to find the larger of two floating-point numbers, you can compare them lexicographically as signed integers, rather than needing to examine the exponents separately. ↩
Most of the 8087's instructions are implemented in microcode, but a few are hard-wired. For more details on instruction decoding, see Instruction decoding in the Intel 8087 floating-point chip. ↩
I use decimal addresses for the microcode because the Opcode Collective started using decimal addresses, and it would be confusing to change now. ↩
The microcode shows that scaling 0 by anything, or scaling anything by 0, leaves the value unchanged.
My view is that the designers took a shortcut here, rather than returning the "right" value.
Since the 8087 defines 0×∞ as NaN, it seems to me that 0×2∞ should also be NaN, so FSCALE(0, ∞) should be NaN, not 0.
The designers probably made the valid decision that nobody really cared about corner cases on the obscure FSCALE instruction.
For other instructions, the behavior with
denormals, unnormals, and zeros is documented (tables S-24 to S-26 in the Numerics Supplement documentation),
but FSCALE is omitted. ↩
The 8087 has separate buses for the exponent and the significand, and the adder is only connected to the significand bus, so how does the exponent get to the adder? The trick is that there is a 16-bit gateway between the exponent bus and the significand bus, so the exponent can be copied over. ↩
I described the 8087's adder here. In brief, subtraction is performed by inverting the B register's value when it is fed into the adder. The carry-in to the adder is set to 1, so this in effect performs a two's-complement subtraction. ↩
Why does the microcode have separate paths to add a positive scale and subtract a negative scale? The reason is that values are stored as a sign bit and an unsigned value, not two's complement like standard integers. As a result, the adder can't perform signed addition directly. Instead, the adder circuitry must be explicitly directed to complement the B register value and perform a subtraction. ↩
This flowchart shows the SPECIAL_TMPS subroutine.
The structure of this routine is complicated because paths split off and rejoin.
One tricky path is the code to determine if there are 0, 1, or 2 NaN values, and take the maximum NaN if there are two.
Another complication is the exception exits, which raise an interrupt if the interrupt is not masked, but not for a comparison instruction.
The two return values are returned through flag and expConv.
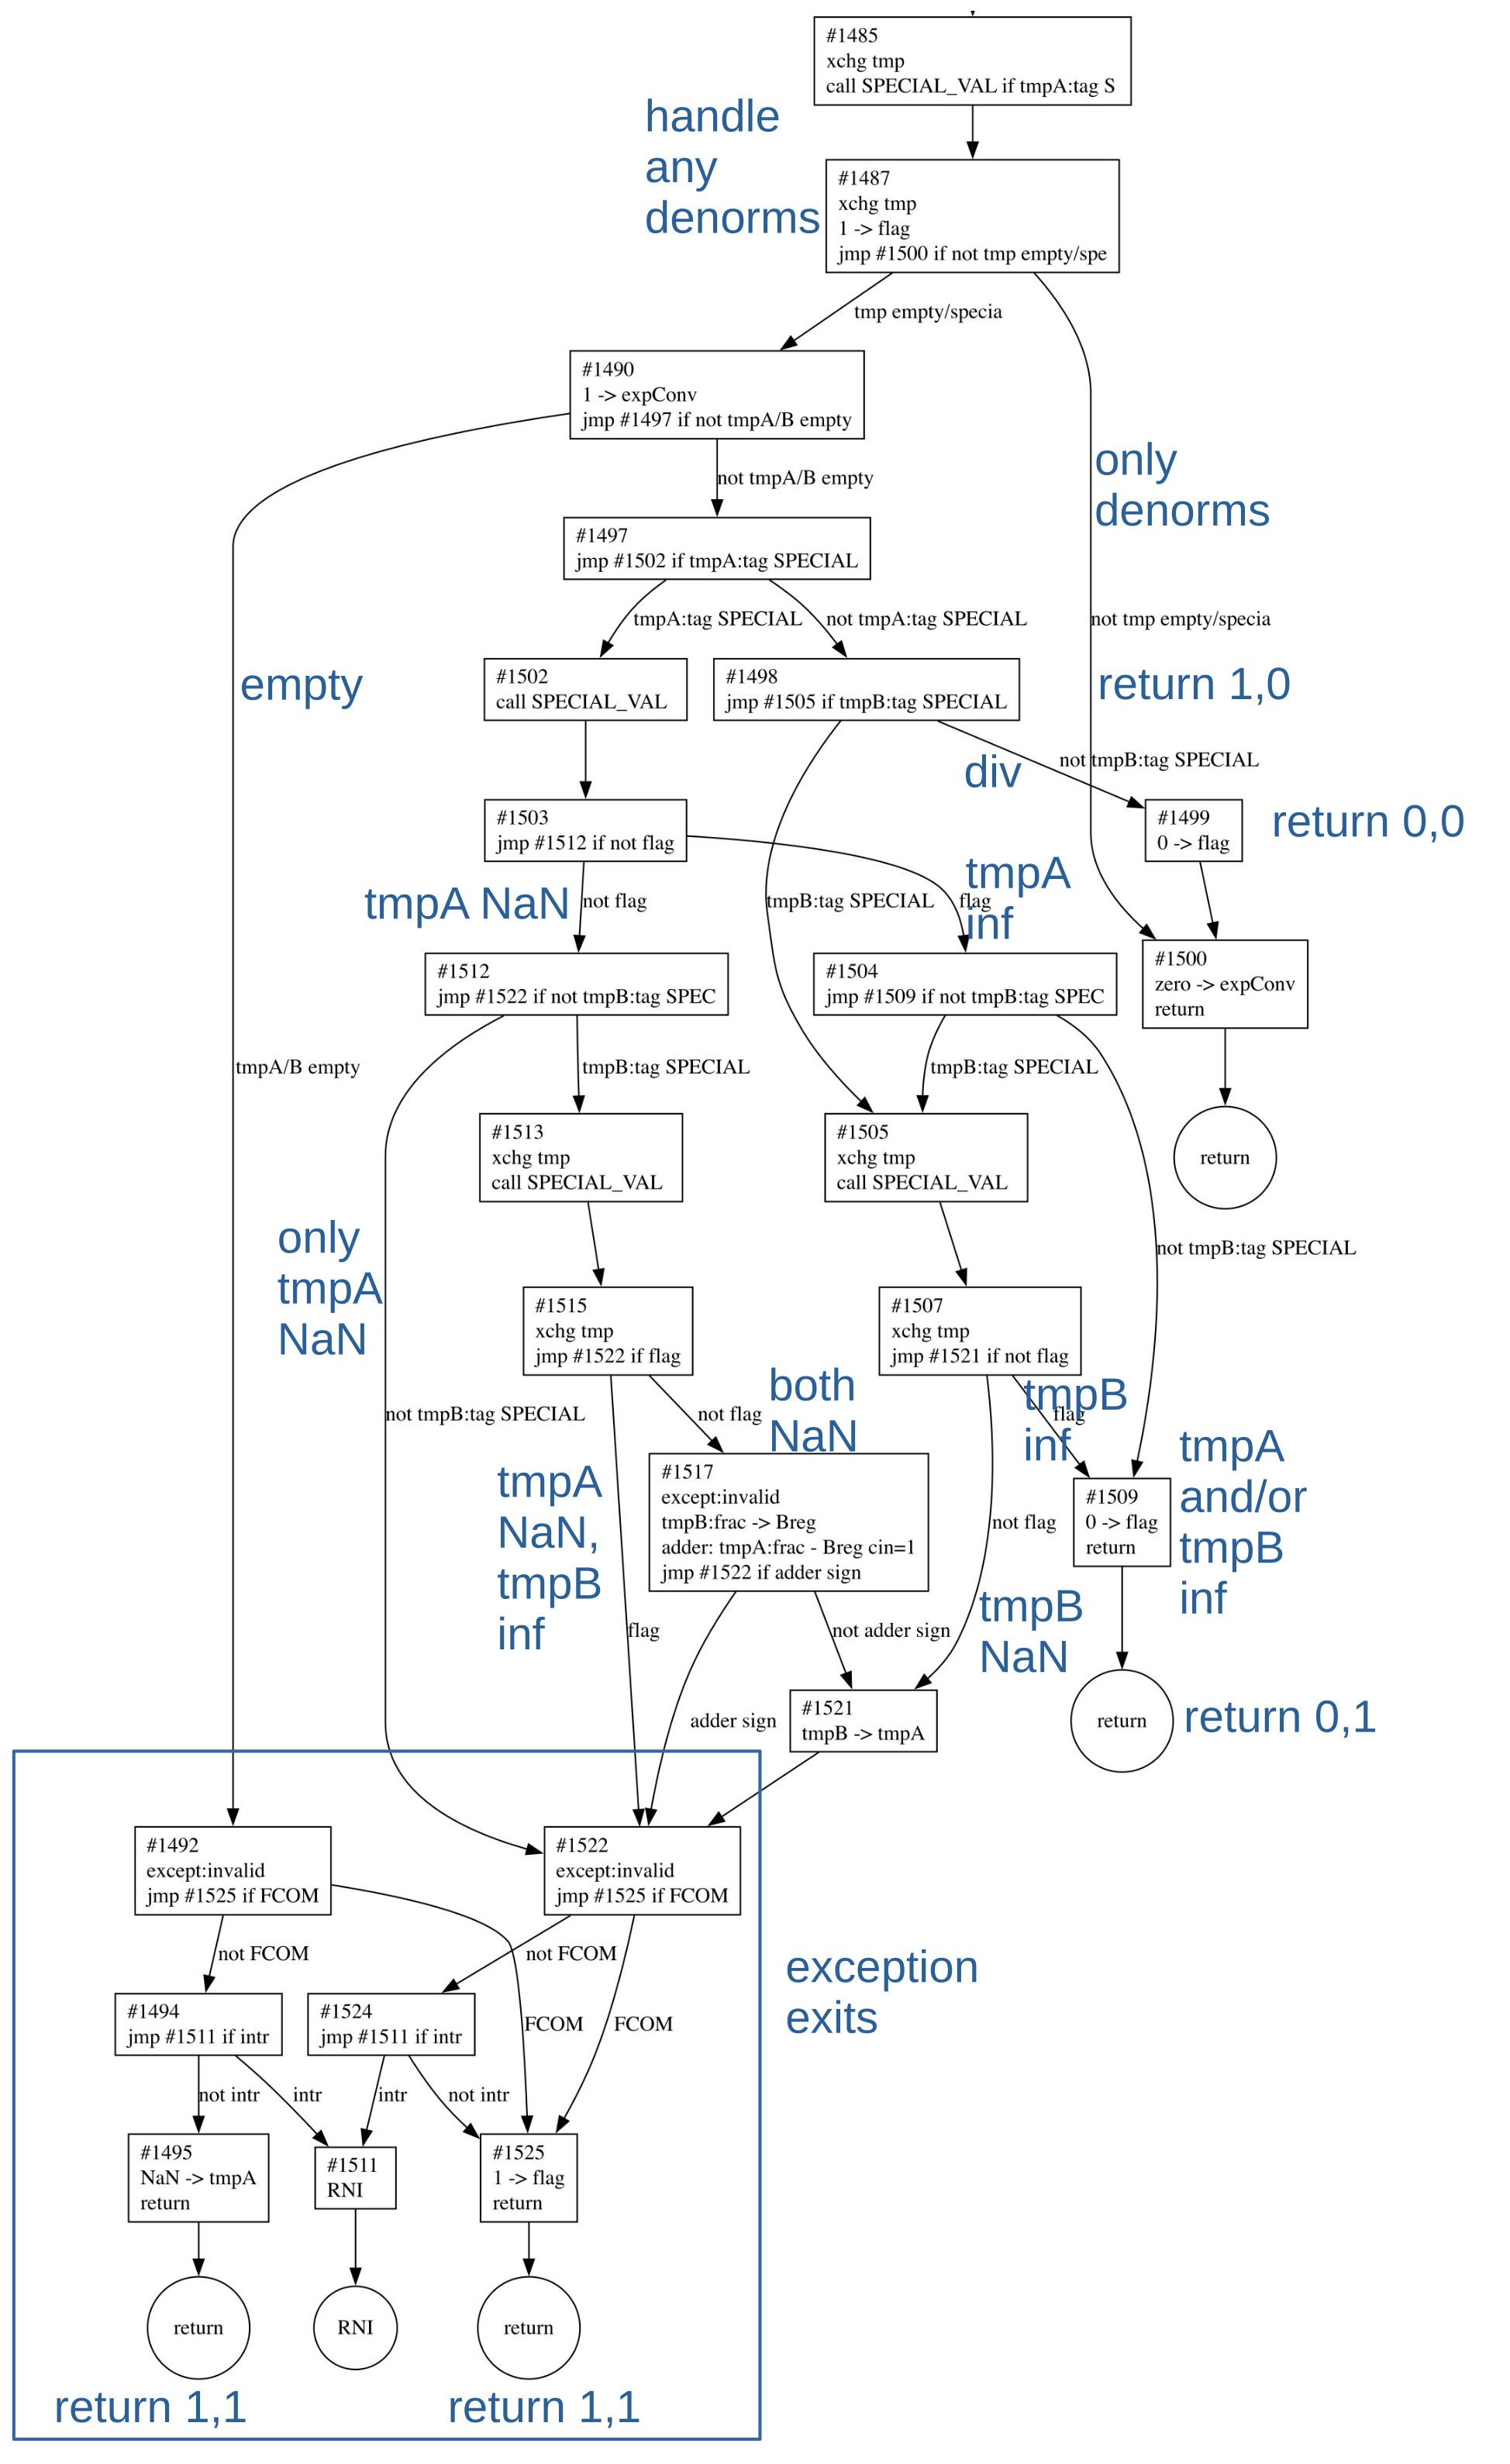
The actions of SPECIAL_TMPS are summarized below. It returns status through the flag flip-flop and the exponent converter register (expConv). Its actions are:
| Input | Result | flag | expConv |
|---|---|---|---|
| empty | NaN, exception | 1 | 1 |
| NaN | (larger) NaN, exception | 1 | 1 |
| infinity | infinity | 0 | 1 |
| denorm | unnorm | 1 | 0 |
| div abnormal | no change | 0 | 0 |
(The last row signals an abnormal value during division computation; I'm still investigating this.) ↩
Prof. William Kahan, who guided the development of the 8087, was disappointed that some floating-point features were unused because of a vicious circle: the features didn't receive good compiler support, so programmers didn't use the features, so compiler developers claimed a lack of demand for the features and didn't implement support. Using multiple values of NaN to record how and/or where an NaN came into existence was an example of a feature that lacked software support. See Lecture Notes on the Status of IEEE Standard 754 for Binary Floating-Point Arithmetic for a detailed discussion of NaN and other issues. ↩
The 8087 makes heavy use of micro-subroutines, with a 6-level stack for microcode subroutine calls.
Microcode jumps and subroutine calls get the address from a jump table. The index from the jump table comes from 6 bits of the micro-instruction.
We unimaginatively named the entries in the microcode jump table as J0, J1, and so forth based on the index, but I'm adding more meaningful names
as I figure them out.
As for the names for micro-instructions, we don't have any information on what names were used by Intel (unlike the 8086).
I invented names, influenced by the names in Gloriouscow's disassembly. ↩
A subroutine that I call SPECIAL_VAL handles denormalized values, infinity, and NaN.
(This subroutine is primarily used by SPECIAL_TMPS, but is also used by FRNDINT (round to integer) and FSQRT.)
First, the subroutine looks at the exponent of tmpA; if the exponent is zero, the value is denormalized.
(The value could also be zero, but that was handled earlier.)
If so, the denorm exception is set.
Comparison instructions such as FCOM handle denorms differently, but I'll ignore that for now.
The code at #1576 tests if the denorm triggered an interrupt; if so, the instruction ends with the interrupt.
If the interrupt was masked, the code converts the denorm to an unnorm by changing the tag to norm and
changing the exponent to 1 (which corresponds to the very negative, smallest valid value because of the exponent bias).
The result of the subroutine is returned through a special flag flip-flop.
SPECIAL_VAL (J12):
#1572 tmpA:exp -> sumreg:frac Handle special value
#1573 jmp #1581 if not Sum register is zero Test exp for denorm
#1574 except:denorm
#1575 jmp #1577 if compare instruction No exception for comparison
#1576 jmp #1571 if DE (denormalized) interrupt RNI if exception
#1577 norm -> tmpA tag     Handle denorm: tag empty? or valid?
#1578 1 -> tmpA:exp        Change to unnorm
#1579 0 -> flag            Clear flag
#1580 return
#1581 shift tmpA:frac L 0 bytes, 1 bits Shift to check if infinity vs NaN
#1582 shift L -> sumreg:frac
#1583 jmp #1579 if not Sum register is zero Clear flag for NaN
#1584 1 -> flag            Set flag for infinity
#1585 return
At #1581, the code checks if the value is infinity or NaN.
Interestingly, this test isn't done directly, but by manipulating the value with the shifter.
Recall that infinity has a significand of 10...00, while NaN has at least one additional 1 bit.
The code shifts the significand one bit to the left; a zero result indicates infinity, while a nonzero result indicates NaN.
As before, the result is returned in the flag flip-flop. ↩
The logic to compute the rounding bits is more complicated than described. There are two micro-instructions with slightly different behavior depending
on the expConv value, but I won't get into that here. ↩
The ADJUST_PRECISION subroutine appears to return infinity if the significand overflows after rounding up, but I'm not entirely happy with this.
For instance, 1.111... should round up to 2, not infinity; the significand overflows, but that's not an overflow of the float.
Presumably, this gets fixed somewhere else. ↩
I don't know why Intel failed to document the feature that a condition code indicates whether a value was rounded up or down. The 8087 documentation is very thorough with corner cases; usually, when I find a strange circuit, I can find a line in the documentation that explains why it is there. Maybe the condition code feature was buggy, so it was easier to not document it? Maybe this feature was a hidden trap to catch competitors that copied the chip? (Intel had a secret instruction in the 8086 for this purpose, but NEC's version of the 8086 didn't have it, much to the disappointment of Intel's lawyers.) Maybe Intel wasn't sure if they wanted to support the feature in later versions? (This is why some of the 8085 processor's instructions weren't documented.) For now, it's a mystery. ↩
Armin Ronacher 12/09/2026 | Source: Armin Ronacher's Thoughts and Writings
This week some flavor of “AI is going to kill us all” went viral. In particular one where an employee put his personal probability of that happening above 10%. Which made me go to the Wikipedia page of P(doom) and I realized that Dario Amodei’s apparent probability of something bad happening seems to be between 10-25%. And well, Dario then wrote about pacing the frontier . And Sam read it and wants to pace too. And well, so does Musk.
I encourage you strongly to read the post, because I think it’s a good one. And yet, when I read the post I could not help but feel in strong opposition to it, despite the fact that I think I’m on the same page with regard to all observations and, to a large degree, the concerns.
I thought it might be interesting to write down my present-day thoughts on this, even if for no other reason than for myself to look back at it a year or two from now.
What I really appreciate about Dario’s post is that he lays out a scenario that is not a huge stretch but also one that describes a clear, unfortunate outcome we should fight: persistent botnets and other forms of nuisance. And well, we don’t have to look very far to see the issues left and right. Wikipedia has a page called 2026 OpenAI agent cyberattacks which gives you at least some overview of what we figured out agents have hacked up to this point. Except I know it’s not up to date, because for instance they also poisoned RubyGems.
Today these systems might be annoying, but they can be turned off when we figure out where they are. Except, it seems like OpenAI and Anthropic are operating at such a scale that they seemingly can be completely blind to what their systems are doing.
I don’t think we are anywhere close to a world where an agent might decide to hack into core inference infrastructure to upload weights to other GPUs to survive. But simultaneously it’s entirely in the realm of possibility and primarily curtailed by the labs probably being particularly careful about their IP.
For me the scenario I primarily worry about is what it does to us. And by us I mean anyone who is not currently working on closed weight, dopamine-loaded, subsidized token faucet. I really don’t worry about someone using these models to build a nuke, or to control some rockets in the Middle East, or that America would lose against China in some international culture war. I almost exclusively worry about what this does to us as humans.
What I find absolutely hilarious and simultaneously entirely frustrating about this conversation is that there is this idea that there is something to be paced. First of all, we should really talk about who Dario is talking about here. There are really only two companies: Anthropic and OpenAI. Nobody else matters in this space right now (this might change, but we’re talking about the right now). Both of those companies are basically coming from the same origin. The solution that Dario proposed, at least in part, is a third-party evaluator that in this case is METR. Which, unsurprisingly, also has strong ties to both OpenAI and Anthropic. Sure, there are some philosophical differences between the companies, but they are much more alike than they are different.
Both those companies greatly benefited from being able to train on public data that we all generated in one form or another over the last decades. They are also both increasingly causing strain on public resources, though it seems that OpenAI has their shit way less under control. But now we are presented with the idea that what these models are being trained on is so dangerous that it really should be in the hands of very few American corporations to decide who can do what and when and how.
But behold, Dario is also very worried about China. It starts with using AI for “democracy and freedom” and then it asks for ensuring that a gap with China exists. All new recent shenanigans on the Anthropic API are fully there to prevent the distillation by the Chinese, and they are not at all hiding it.
I can tell you when the topic of AI safety and pacing is much less of a concern: if we actually were forced to have open weight models to begin with. A powerful technology that is out there for everyone to use comes with built-in pacing. In a way it’s the truest form of MAD or proliferation. I would argue we are in this pickle in the first place because right now the public is massively supporting (indirectly) the development of these models but simultaneously has to buy back the economic benefits that they might create from very few labs who have significant power. And their power is also seen as a geopolitical power, at least in the US, and maybe to some lesser degree in China.
And I know I use “public” loosely here. PyPI is not a public project, nor are RubyGems or GitHub. But they’re part of the Open Source commons and large AI companies are currently doing a tremendous job at stressing these in an effort to train ever more powerful models.
We should be glad that China is currently massively bailing out the world. If it were not for Chinese labs distilling American models, we would be in a pretty awful situation right now, particularly as Europeans. The open weight models are driving innovation and the diffusion of capabilities, and are leveling the playing field.
If we greatly restrain our AI capabilities in the belief that China will do the same, and then China defects, AI could be so powerful that such a defection could lead to their geopolitical dominance. Therefore any agreement must either have ironclad verifiability, or must be limited enough that defection would not be militarily existential.
— Dario Amodei
I am assuming Dario has reasons to believe this, but the models that are actually causing issues right now are all closed weight American models. I’m fairly certain if they were open weight models, we would not have that issue. Why? Because for a start, the economics of serving up these models are only that distorted due to how the big labs can operate. OpenAI is casually burning 18 million USD to brute force a problem on a whim. They are operating subscriptions at a massive loss, distorting the market everywhere. If we had mass accessibility on somewhat equal terms, a lot of the crazy issues we are seeing today would not be taking place.
From where I sit, what we observe right now is a total regulatory failure everywhere. In Europe you have some whacky AI regulation that is two years old and completely misses the problems that we actually have and focuses on problems that nobody has. In the US we’re seeing a system that is probably best described as turbo capitalism paired with sinophobia and erratic decision-making. In the chaos in which we find ourselves, the reality emerges. And the reality is, even today, really problematic.
Whatever laws and regulations already exist are largely completely ignored. Plenty of companies are buying data from all over the place that people never agreed could be used for training of AI models. The token economy that is emerging is one that looks like a drug market where you don’t know where the requests are going, what model is served up to you, where the GPUs are even running, let alone what you pay for all of this.
We now have mathematicians who are scared that their use of ChatGPT leads to future models being trained on their ideas, and OpenAI apparently can’t even rule it out.
Ideally the regulators would have forced these models to actually benefit the commons if they are from the commons. The internet has, for instance, greatly benefited from very liberal rulings in the US that permitted scraping. Learning on public data could have been regulated in a way that labs would have to actively support and enable certain forms of distillation. That alone would dramatically change how these models are trained.
As I said before, I don’t think AI is going to usher in an extinction event. In fact, even if nobody were to slow down, I really don’t think humanity would have much to worry about. I tend to think it would actually be the large labs that have much more to lose there in reputation and legal responsibilities. I find it preposterous that OpenAI’s agents are committing actual crimes out there, but we’re just shrugging our shoulders and moving on as if nothing happened. But I’m sure executives in those companies are waking up to the reality that this is not at all popular with a lot of their potential consumers.
I also think that this entire recursive self-improvement business has a good chance of being a problem. But not necessarily in that it will cause the end of humanity or societies, but that it will just do massive damage everywhere.
And really, it will just make a lot of the things we are doing much more expensive. Software engineering is an early victim of that. The newfound powers so far have resulted in a new tax that companies need to pay to the model providers, both to keep up with the new speed and to deal with the problem of these machines finding security issues left and right.
And presumably what is going on in software will happen to more industries. Universities and research groups will have to pour a lot of money into the closed models as well, to keep up with others who do.
In a way, I’m really confused that society is taking all of this so well.
Osvaldo Santana 09/09/2026 | Source: osantana.me
Eu me considero “agilista” desde os tempos do RUP. Sim, aquele RUP: iterativo no papel, mas tão cerimonioso que precisava de um documento para explicar os outros documentos. Foi a minha porta de entrada para a ideia de que software se constrói em ciclos, e de lá para cá acompanhei o Manifesto Ágil virar Scrum, Scrum virar “Scrum, mas…”, e Kanban virar a coisa que a gente faz quando cansa de Scrum.
Agora tem um agente de IA sentado na minha mesa escrevendo código mais rápido do que eu consigo ler. E a pergunta que não sai da minha cabeça é: os rituais que eu defendi durante vinte e tantos anos ainda fazem sentido?
Para responder isso eu precisei de um modelo mental e de uma volta no tempo. Tenha paciência comigo.
O Harold Leavitt, lá em 1964, descreveu uma organização como um diamante com quatro pontas: estrutura, tarefas, pessoas e tecnologia. O detalhe importante do modelo não são as pontas, são as setas entre elas. Está tudo interligado: mexeu numa, as outras se mexem junto, querendo ou não.

Em desenvolvimento de software a gente costuma simplificar isso para um triângulo de pessoas, processos e tecnologia. É nesse triângulo que a nossa conversa acontece. A IA mexeu, e muito, na ponta da tecnologia. Não dá para fingir que as outras duas vão ficar paradas no lugar. E como as pessoas continuam sendo as mesmas (por enquanto), a ponta que mais vai sentir o tranco é a dos processos.

E processo, em software, sempre foi uma história sobre uma coisa só.
Em 1959 a gente (a gente = programador e não eu, que nem era nascido  ) programava em COBOL no estilo code and fix, sem método nenhum. Deu tão certo (#sqn) que em 1968 a OTAN precisou convocar uma conferência para inventar o termo “engenharia de software” e tentar colocar ordem na bagunça. Veio o Waterfall em 1970, o Modelo Espiral do Boehm em 1988, o RUP em 1999 e, em 2001, o Manifesto Ágil como reação a tudo isso.

Se você olhar essa linha do tempo de longe, percebe que ela conta uma história só: a briga contra o feedback tardio. O Waterfall congelava requisitos no início e só descobria que estava tudo errado na homologação, quando mudar ou corrigir alguma coisa custava uma fortuna. O Boehm desenhou uma curva mostrando que o custo de mudar cresce exponencialmente conforme o projeto avança: uma correção barata na fase de requisitos vira um pesadelo em produção. O Ágil foi, essencialmente, a decisão de encurtar os ciclos para pegar os erros enquanto ainda estavam na parte baixa dessa curva.

Guardem essa curva. Ela vai voltar.
Durante toda a história que eu contei acima, escrever código era a parte lenta. Revisar era rápido, testar era relativamente rápido, discutir em reunião era… bom, reunião é reunião. Mas o trabalho pesado ficava na digitação. Estimativas, sprints de duas semanas, story points, tudo isso foi calibrado para um mundo em que o esforço de produzir era o esforço dominante.
O Armin Ronacher chamou o que aconteceu de “The Final Bottleneck”: a IA inverteu a relação e agora escrever é mais rápido do que revisar. O Avery Pennarun (apenwarr) foi mais longe e argumentou que cada camada de aprovação multiplica o tempo por 10, porque a IA acelera a produção mas não acelera a revisão. E não é só impressão: o relatório da Faros AI sobre o “paradoxo da produtividade” mostra quase o dobro de PRs abertas e o tempo de revisão crescendo na mesma proporção. Produzimos mais e entendemos na mesma velocidade de antes.
Aí vem a provocação: se um agente implementa uma feature em duas horas e a revisão leva cinco, o que exatamente estamos estimando no planning? A pergunta “quanto tempo para implementar?” perdeu relevância. A pergunta que importa virou “quanto tempo para garantir que isso está correto?”. Tem gente na AWS defendendo que o sprint planning deveria evoluir para algo como intent design: em vez de estimar tarefas, o time define intenção, guardrails e critérios de sucesso, e deixa a implementação para quem agora é rápido nela. Eu não sei se o nome vai pegar, mas a ideia de que o planning deixa de ser sobre esforço e passa a ser sobre intenção me parece certa.
Vale lembrar:
“Computadores são inúteis, eles só sabem dar respostas”. — Pablo Picasso
Se a IA dá respostas muito rápido o trabalho de fazer as perguntas certas e conferir se a resposta faz sentido continua sendo nosso, e ele não ficou nada mais rápido.
Voltemos à curva do Boehm. Eu sempre gostei do argumento de que pair programming é a forma mais barata de revisão que existe, porque a validação acontece no exato momento em que o código nasce, lá na parte baixa da curva. O code review tradicional acontece bem mais à direita, quando a mudança já está pronta e o autor já foi fazer outra coisa.
Com IA, o “par” passou a ser humano mais agente, e o custo desse pareamento é praticamente zero. A dinâmica inverteu: o humano vira o navigator permanente (revisa, direciona, decide) e o agente vira o driver (digita, implementa). O Kent Beck chama isso de augmented coding: você escreve o teste, a IA gera a implementação, você valida. A validação é reposicionada no ponto mais barato da curva. Para mim esse é o ponto de virada de toda a discussão.
O problema é o que acontece do lado direito da curva. Se o volume de código gerado é impossível de revisar no ritmo em que chega, o revisor cai no dilema que chamam de cognitive debt: ou mantém o rigor de antes e vira o gargalo do time, ou aprova no ritmo que o código aparece e torce para os testes pegarem o que a revisão deixou passar. Nenhuma das opções é boa.
E aqui tem uma coisa que a gente costuma esquecer: code review nunca foi só sobre achar defeito. Era o jeito de distribuir conhecimento sobre o codebase, alinhar decisões de arquitetura, fazer sêniors ensinarem júniors e vice-versa. Era o jeito de manter um modelo mental (aka contexto) compartilhado de como o sistema funciona. Se a máquina escreve o código e a máquina também revisa, quem é responsável? E, mais importante, como o time aprende? Aquela ideia de collective code ownership do XP não se sustenta se ninguém do time leu o código.

E o “como o time aprende” não é preocupação de um programador velho rabugento gritando para a nuvem. Um estudo da Anthropic sobre formação de habilidades com IA mostrou que quem delega passivamente (pede o código, cola, segue em frente) sai com menos de 40% de compreensão do que foi feito, enquanto quem usa a IA para investigar conceitos passa dos 65%. A mesma ferramenta produz um profissional que aprende ou um que só delega, dependendo de como o processo em volta dela é desenhado. Mais um cenário onde o processo pode se tornar um problema.
Isso muda até a definição de pronto. “Done” deixou de ser “funciona e passou nos testes” e passou a ser “funciona, eu entendo por que funciona e sei o que monitorar”. O Casey West, no Agentic Manifesto, descreve como a passagem de verificação (fez o que eu disse?) para validação (fez o que eu queria?). E o pessoal da Mozilla AI aponta que a nossa cultura sempre ligou ownership a autoria; a IA quebra esse vínculo, e agora você precisa ser dono de algo não porque você escreveu aquilo mas porque você entende aquilo.
Pelo mesmo raciocínio, o WIP limit do Kanban precisa mudar de dimensão. Não adianta limitar quantas tarefas estão “em andamento” se um agente consegue mover dez delas para essa coluna ao mesmo tempo. O limite relevante virou “quantas mudanças o time consegue entender simultaneamente”. O projeto OpenClaw, com suas 2.500 PRs abertas, é o que acontece quando a entrada cresce mais rápido que a capacidade de processar: uma falha acumulativa.
A IA não torna os processos obsoletos. Ela torna os processos errados mais perigosos, porque agora o erro é produzido em escala industrial.
O gargalo se deslocou de escrever para compreender e validar, e os rituais precisam acompanhar esse deslocamento. A daily deixa de ser “o que eu fiz” e passa a ser “o que eu entendi sobre o que foi feito”. A retrospectiva, que sempre foi o ritual mais negligenciado, virou na minha opinião o mais importante de todos: é o único momento formal em que o time para e pergunta “qual código gerado a gente não entende? que decisões técnicas o agente tomou sem a gente validar?”.
Também vale um alerta. Tem gente dizendo que documentação e specs agora importam mais que o código, porque viraram o insumo do agente. Pode ser. Mas se a resposta para tudo for “escreva uma spec bem detalhada antes de começar”, cuidado: isso tem nome, e o nome é Waterfall. Mais spec na frente não é sinônimo de mais controle. O que separa uma spec útil de um documento de requisitos de 1970 não é o tamanho dela, é o tamanho do ciclo até o primeiro feedback: se a spec alimenta um agente que devolve algo testável em uma hora, ótimo, isso é Ágil com outra ferramenta; se ela precisa estar “completa e aprovada” antes de qualquer código existir, é a curva do Boehm de novo, só que com um capítulo novo. Vinte anos para matar o Waterfall e seis meses para a IA trazê-lo de volta seria um final meio irônico para essa história.
O Ágil precisa evoluir, não ser abandonado. E o jeito mais barato de começar é o mesmo de sempre: revisando as suas práticas, uma por uma, e perguntando se elas ainda estão otimizando o gargalo certo.
Deixei de fora várias práticas que também merecem essa revisão (TDD, CI/CD, prototipação, demos, refactoring) desse texto porque ele já entrega o ferramental para refatorar os seus processos. Uma lista mais extensa pode ser encontrada nos slides da minha apresentação na Codecon 2026.
Armin Ronacher 07/09/2026 | Source: Armin Ronacher's Thoughts and Writings
I’m more and more convinced that all of AI engineering is Neijuan (内卷, meaning curl inwards). In China it describes a system that demands ever more effort and competition without improving output. The way in which it sometimes shows up in the West is the 996 nonsense. The English term for Neijuan is “Involution” from the book Agricultural Involution. Agricultural involution describes the intensification of farming that raises productivity per square meter while leaving productivity per head unchanged.
That’s how I feel about AI right now.
Which brings me to GPT 6 Astra. Astra is by all accounts an incredibly impressive model. There is really not much I can say against this. It’s amazing at computer use, understands images and complex topics, and it’s relentless in its pursuit of completion. It is absolutely impressive; these types of models are going to change the world in one form or another.
But at least for the moment I don’t know how to work with it for actual software engineering. Since that got quite a bit of attention on Twitter, I figured I might summarize my thoughts and just share what kind of code comes out of this thing.
“Armin, you should run a software factory!” I’ve heard that a few times now, so I figured
I might celebrate the release of it by running a little software factory over
the weekend. If everybody builds slop 3D games, then I should do something
useful with it. My software factory was intentionally set up to let the model
decide the how of the workflow entirely. It was free to manage its own context
and could maintain its own records in an agent-notes folder. Then it spun off
subagents to work on stuff. The goal? What if we had a Python with virtual
threads and lexical scoping. And well, I burned a
full reset’s worth of ChatGPT tokens on this which appears to be around 4 billion
tokens. 35 hours later, the factory has delivered absolutely nothing of value
and also not taught me anything about how to operate a better one.
But it produced a lot of code and input prompts, and so there is stuff I was able to study. And well, it shows behavior that I’m not used to with Sol and earlier OpenAI models 1. I have since encountered the same issues with regular programming with Astra, so it’s not a result of just the factory.
I think I’m suspecting something is going “wrong” in the training process. The model is greatly rewarded for succeeding on long-horizon tasks, but presumably there is very little punishing going on for “shitty code.” The apparent result is that Astra is amazing at producing 3D stuff and it can keep going for a very long time, coming up with its own work in the process. I had it do quite a bit of reverse engineering of my robot vacuum in ways that were quite impressive. So it’s definitely cool!
The first issue I have with Astra comes from the type of code that it uses for
tool calls. Codex increasingly has been relying on “just bash” to do more and
more operations. For a few versions now the original Codex harness just uses
sed and other tools to read files. You just usually can’t see them because Codex
parses the bash
commands
and hides them if it recognizes them. But Astra … really loves Python? That is
not much of a surprise because even older OpenAI models had a tendency to
sometimes use on-demand Python code to read and manipulate files at times, but
Astra does it really quite excessively for me.
Now here is an important disclaimer: this project is very meta here because I worked on the CPython interpreter. But I can assure you that I have seen this model do weird Python things even in TypeScript code in Pi. But I have the most evidence of odd code from when I had the thing work over the weekend with zero oversight from my slop factory.
That it writes Python is not interesting; the type of Python is interesting, and I collected some outputs for you to gloss over.
In the Codex harness I found multiple cases where subagents resorted fully to manual string manipulation with Python instead of using the patch tool.
python3 - <<'PY'
from pathlib import Path
p=Path('Include/internal/pycore_intrinsics.h');s=p.read_text().replace('#define MAX_INTRINSIC_1                         14','#define INTRINSIC_RETAIN_ANNOTATION_CELLS        15\n\n#define MAX_INTRINSIC_1                         15');p.write_text(s)
p=Path('Python/intrinsics.c');s=p.read_text();idx=s.index('#define INTRINSIC_FUNC_ENTRY');s=s[:idx]+'''/* Hold every old cell until the compiler has published the entire site's new
   capture. A replaced cell's finalizer may reenter module __annotate__. */
static PyObject *
retain_annotation_cells(PyThreadState *tstate, PyObject *holders)
{
    if (!PyTuple_CheckExact(holders)) {
        PyErr_SetString(PyExc_TypeError, "annotation holders must be a tuple");
        return NULL;
    }
    Py_ssize_t size = PyTuple_GET_SIZE(holders);
    PyObject *previous = PyTuple_New(size);
    if (previous == NULL) return NULL;
    for (Py_ssize_t i = 0; i < size; i++) {
        PyObject *holder = PyTuple_GET_ITEM(holders, i);
        if (!PyCell_Check(holder)) {
            Py_DECREF(previous);
            PyErr_SetString(PyExc_TypeError, "annotation holder must be a cell");
            return NULL;
        }
        PyObject *cell = PyCell_Get(holder);
        PyTuple_SET_ITEM(previous, i, cell == NULL ? Py_NewRef(Py_None) : cell);
    }
    return previous;
}

''' +s[idx:];s=s.replace('    INTRINSIC_FUNC_ENTRY(INTRINSIC_AWAIT_BLOCK, await_block)','    INTRINSIC_FUNC_ENTRY(INTRINSIC_AWAIT_BLOCK, await_block)\n    INTRINSIC_FUNC_ENTRY(INTRINSIC_RETAIN_ANNOTATION_CELLS, retain_annotation_cells)');p.write_text(s)
p=Path('Python/codegen.c');s=p.read_text();idx=s.index('static int\ncodegen_annassign(');s=s[:idx]+'''static int
codegen_retain_annotation_cells(compiler *c, location loc, PyObject *captures)
{
    Py_ssize_t pos = 0;
    PyObject *binding, *holder;
    while (PyDict_Next(captures, &pos, &binding, &holder)) {
        ADDOP_NAME(c, loc, LOAD_CLOSURE, holder, cellvars);
    }
    ADDOP_I(c, loc, BUILD_TUPLE, PyDict_GET_SIZE(captures));
    ADDOP_I(c, loc, CALL_INTRINSIC_1, INTRINSIC_RETAIN_ANNOTATION_CELLS);
    return SUCCESS;
}

''' +s[idx:]
a=s.index('                if (conditional_annotation_index != NULL) {',s.index('codegen_annassign(compiler *c'))
b=s.index('                if (captures != NULL) {',a)
# Move lookup before conditional registration and retain old cells before anything changes.
lookupstart=s.index('                PyObject *captures = _PyCompile_AnnotationCaptures',a)
lookup=s[lookupstart:b].replace('                    return ERROR;','                    Py_XDECREF(conditional_annotation_index); return ERROR;')
s=s[:lookupstart]+s[b:]
setup=lookup+'''                if (captures != NULL && codegen_retain_annotation_cells(c, loc, captures) < 0) {
                    Py_XDECREF(conditional_annotation_index); return ERROR;
                }
'''
s=s[:a]+setup+s[a:]
needle='                        ADDOP_NAME(c, loc, STORE_DEREF, holder, cellvars);\n                    }\n                }'
s=s.replace(needle,'                        ADDOP_NAME(c, loc, STORE_DEREF, holder, cellvars);\n                    }\n                    ADDOP(c, loc, POP_TOP); /* release old cells after full publication */\n                }',1);p.write_text(s)
p=Path('Include/internal/pycore_magic_number.h');s=p.read_text().replace('    Python 3.16a1 3709 (Checked deferred annotation closure capture)','    Python 3.16a1 3709 (Checked deferred annotation closure capture)\n    Python 3.16a1 3710 (Retain replaced annotation captures until publication)').replace('#define PYC_MAGIC_NUMBER 3709','#define PYC_MAGIC_NUMBER 3710');p.write_text(s)
p=Path('Lib/test/test_block_annotation_captures.py');s=p.read_text();idx=s.index('    def test_typing_consumers');s=s[:idx]+'''    def test_replaced_cell_finalizer_sees_complete_site_publication(self):
        module=execute("""\\
            events=[]
            class V:
                def __init__(self,n): self.n=n
                def __del__(self):
                    if self.n == 0: events.append(__annotate__(1))
            for i in range(2):
                x=V(i) # bind x y
                y=i
                value:(x.n,y)
        """)
        self.assertEqual(module.events,[{'value':(1,1)}])
        self.assertEqual(module.__annotate__(1),{'value':(1,1)})

''' +s[idx:];p.write_text(s)
PY
make -j1 > /tmp/block-annotations-build7.log 2>&1
In the middle of a conversation the agent ran into “Bad file descriptor” on a test and Astra decided it needs to see if file descriptors can be passed over Unix sockets on macOS in a super compressed manner:
/usr/bin/python3 - <<'PY'
import socket,os,array
for into in (False,True):
 a,b=socket.socketpair();fd=os.open(os.devnull,os.O_RDONLY);b.sendmsg([b'c'],[(socket.SOL_SOCKET,socket.SCM_RIGHTS,array.array('i',[fd]))]);print('fds',a.fileno(),b.fileno(),fd)
 if into:r=a.recvmsg_into([bytearray(1),bytearray(),bytearray(19)],socket.CMSG_SPACE(4),socket.MSG_PEEK|socket.MSG_DONTWAIT)
 else:r=a.recvmsg(20,socket.CMSG_SPACE(4),socket.MSG_PEEK|socket.MSG_DONTWAIT)
 print('peek',r,flush=True)
 rights=array.array('i',r[1][0][2]);print('rights',rights,flush=True)
 for f in rights:
  try: print('stat',os.fstat(f))
  except Exception as e: print('error',e)
 r=a.recvmsg(20,socket.CMSG_SPACE(4),socket.MSG_DONTWAIT);print('consumed',r,flush=True)
 a.close();b.close();os.close(fd)
PY
The agent notes were rather consistently updated with Python:
python3 - <<'PY'
from pathlib import Path
p=Path('agent-notes/live/block-with-bindings.md');s=p.read_text().replace('  has117/77/zero failures.', '  has117/77/zero failures; existing bundled Expat unreachable-fallthrough\n  warnings are the only optimized warnings.')
# Keep the final evidence readable without rewriting historical parent requirements.
for a,b in [('all328','all 328'),('pass31','pass 31'),('pass all328','pass all 328'),('pass,9.2s','pass, 9.2s'),('log`,210','log`, 210'),('log`,5,731','log`, 5,731'),('log`:18/18','log`: 18/18'),('pass,88','pass, 88'),('pass,90','pass, 90'),('skips,1m','skips, 1m'),('all6,280','all 6,280'),('has117','has 117')]: s=s.replace(a,b)
s += '\nKey source review: Python/symtable.c:603 (discovery), :3985 (sequential header traversal),\nPython/codegen.c:3488 (source-only exclusion), :5836 (publication), :5853 (normal/\nunwind reference cleanup), :5925/:6037 (enter-protected target setup).\n'
p.write_text(s)
for name in ('STATE.md','build-and-test.md'):
 p=Path('agent-notes/live')/name;s=p.read_text()
 for a,b in [('build:117','build: 117'),('paths.18','paths. 18'),('paths.\n18','paths.\n18'),('and210','and 210'),('pass5,731','pass 5,731'),('All6,280','All 6,280'),('failures,31','failures, 31'),('in\n115s','in\n115s'),('have117','have 117'),('paths.\n18','paths.\n18'),('18 focused,210','18 focused, 210'),('and5,731','and 5,731'),('all6,280','all 6,280')]: s=s.replace(a,b)
 p.write_text(s)
PY
git diff --check
git add -u
git add Lib/test/test_block_with_bindings.py agent-notes/done/asyncio-task-drivers.md
git diff --cached --stat
git commit -m 'Add explicit with and async with header bindings'
In multiple cases it used Python to spawn Node.js on another machine. It first wrote the script, then it used Bash to run Python, then that program ran Node.js via prlctl on my Windows box.
import subprocess
code = "const{readFileSync}=require('fs');const{strict:a}=require('assert');const c=require('C:/Users/mitsuhiko/AppData/Local/Temp/pi-clipboard-threads/win32-arm64.node');(async()=>{const p=c.getText();a.ok(p instanceof Promise);const saved=await p;const image=await c.getImage();if(image||saved===null){console.log('arm64 async text/image reads passed; preserving non-text clipboard');return}try{for(const text of ['café 日本語','', 'large'.repeat(200000)]){const p=c.setText(text);a.ok(p instanceof Promise);await p;a.equal(await c.getText(),text);a.equal(await c.getImage(),null)}console.log('Windows ARM64 async Unicode, empty, large text and empty image passed')}finally{await c.setText(saved)}})().catch(e=>{console.error(e);process.exitCode=1})"
subprocess.run(['prlctl', 'exec', 'Windows 11', '--current-user', 'C:\\Program Files\\nodejs\\node.exe', '-e', code], check=True)
Since it was already doing that, it used Bash to run Python to then run Node.js to then use Node.js to invoke PowerShell.
import subprocess
code = "process.env.PSModulePath='C:/Windows/System32/WindowsPowerShell/v1.0/Modules';require('child_process').spawnSync('powershell.exe',['-NoProfile','-NonInteractive','-ExecutionPolicy','Bypass','-File','C:/Users/mitsuhiko/AppData/Local/Temp/pi-clipboard-threads/pi-clipboard-windows.ps1'],{stdio:'inherit'});console.log('completed')"
subprocess.run(['prlctl', 'exec', 'Windows 11', '--current-user', 'C:\\Program Files\\nodejs\\node.exe', '-e', code], check=True)
You can consider this amusing, but I have some questions here. The first problem with this is that it’s unreadable for a human. If you wanna follow along with what is going on, then good luck. Particularly once it opts out of using the edit tools that the harness provides, you’re going to have to resort to using the diff viewer of the final artifacts since it’s almost impossible to visualize the changes as they happen by reading the code.
This is not quite as bad in Pi for the most part because I mostly see it editing
with the edit tool. When however goes all bananza with subagents (where the
agent believes nobody is looking) it’s resorting to all kinds of increasingly
bizarre behavior. I actually don’t know if the model thinks someone is looking,
but that’s the vibe I’m getting.
But then it starts doing the same nonsense in code that actually gets committed. I have mostly seen this in tests, but you can also see this for instance when it writes JavaScript or CSS embedded in HTML. It almost seems like when it’s “one step removed” from regular code, it starts falling into these patterns.
Here are some unit tests that it created:
def test_unpack_suspension_and_continuation_close(self):
    from continuations import Continuation,suspend
    readers=[]
    class Source:
        def __iter__(self):
            yield 1
            suspend('unpacking')
            yield 2
    ns=execute('''
        def run():
            a,b='old-a','old-b'
            readers.append(lambda: (a,b))
            def a,b=Source()
            suspend('published')
    ''',Source=Source,readers=readers,suspend=suspend)
    with Continuation(ns['run']) as continuation:
        self.assertEqual(continuation.resume(),'unpacking')
        self.assertEqual(readers[0](),('old-a','old-b'))
        self.assertEqual(continuation.resume(),'published')
        self.assertEqual(readers[0](),(1,2))
    class Value:pass
    refs=[];frames=[];callbacks=[]
    ns=execute('''
        def run():
            for def x in [Value()]:
                refs.append(weakref.ref(x))
                frames.append(sys._getframe())
                callbacks.append(lambda: x)
                suspend('body')
    ''',Value=Value,refs=refs,frames=frames,callbacks=callbacks,weakref=weakref,sys=sys,suspend=suspend)
    with Continuation(ns['run']) as continuation:self.assertEqual(continuation.resume(),'body')
    self.assertNotIn('x',frames[0].f_locals)
    self.assertIsNotNone(refs[0]());callbacks.clear();self.assertIsNone(refs[0]())

def test_ast_roundtrips_and_future_annotation_unparse(self):
    source='callback=lambda {for def a, [b,*rest] in [(1,[2,3])] {return a,b,rest}}'
    tree=ast.parse(source);node=tree.body[0].value.body[0]
    self.assertIsInstance(node,ast.ForBinding)
    self.assertEqual(node._fields,('target','iter','body','orelse','type_comment'))
    self.assertEqual(node.lineno,1);self.assertGreater(node.end_col_offset,node.col_offset)
    self.assertEqual(ast.dump(tree),ast.dump(ast.parse(ast.unparse(tree))))
    ns=execute('from __future__ import annotations\ndef f(arg: '+source.split('=',1)[1]+'): pass')
    self.assertEqual(eval(ns['f'].__annotations__['arg'])(),(1,2,[3]))
    tree=ast.parse('async def f():\n async for def x in values: pass # type: ignored\n')
    self.assertIsInstance(tree.body[0].body[0],ast.AsyncForBinding)
    self.assertEqual(ast.dump(tree),ast.dump(ast.parse(ast.unparse(tree))))
So at least in some situations, the Python slop that it normally code-golfs for
token-efficient tool calls leaks into the Python code it generates that should
be stored. And well, it’s clearly more token efficient. The two unit tests
above, when indented to the class structure they were in, are 10% more token
efficient in this form than after a ruff format.
I think there are a handful of things happening now that are pushing the whole thing in directions that are in conflict with one another. The training runs for these models are rapidly accelerating and they are now presumably also moving towards recursive self-improvement. The reward for the models is probably a combination of token efficiency, task completion rate and maybe some simple indicators like cyclomatic complexity. But we humans don’t think of code that is readable or understandable by simple, readily quantifiable metrics. All those things you can easily measure in isolation, and you can also optimize for them quite locally.
But these local optimizations do not produce global optimums, and the fewer of us are looking at the output, the less it matters. Obviously my software factory ran aground over the ~35 hours that it ran, but you can see the gradual regression towards insanity from the notes that it produced. For instance the task naming in the task file starts with an optimistic 1, 2, 3, 5, 5a but then eventually gets to 8a, 8a1, and then ends up with 8b2c2b3 and “8b2c2b2b checkpoint1”. The code that it produced got ever more wild. I don’t want to bore you with what it tried to build, but here are some example pieces of the interpreter changes:
I have no idea where it got those numbers from, but at one point it started passing random constants from one module to a C implementation. Initially that started out as a function that it mainly needed to do test assertions, but just before I turned off that experiment, that function started to be relied upon by non-test code as well.
static PyObject *
native_probe_run_impl(PyObject *callback, int sleep, int operation, PyObject *other)
{
    pthread_mutexattr_t attr;
    pthread_mutex_t mutex;
    pthread_mutexattr_init(&attr);
    pthread_mutexattr_settype(&attr, PTHREAD_MUTEX_RECURSIVE);
    pthread_mutex_init(&mutex, &attr);
    pthread_mutexattr_destroy(&attr);
    pthread_mutex_lock(&mutex);
    int previous = native_sentinel;
    pthread_mutex_t *previous_mutex = native_mutex;
    native_sentinel = previous + 1;
    native_mutex = &mutex;
    PyThreadState *tstate = PyThreadState_Get();
    PyGILState_STATE gil = PyGILState_Ensure();
    int saved_errno = errno;
    PyObject *result = NULL;
    Py_ssize_t value;
    /* No intervening Python frame: these exercise ambient C provenance. */
    switch (operation) {
        case 0: result = PyObject_CallNoArgs(callback); break;
        case 1: result = PyNumber_Add(callback, other); break;
        case 2: result = PyNumber_Negative(callback); break;
        case 3: result = PyObject_RichCompare(callback, other, Py_LT); break;
        case 4:
            value = PyObject_IsTrue(callback);
            if (value >= 0) result = PyBool_FromLong(value);
            break;
        case 5:
            value = PyObject_Length(callback);
            if (value >= 0) result = PyLong_FromSsize_t(value);
            break;
        case 6: result = PyObject_GetIter(callback); break;
        case 7: result = PyIter_Next(callback); break;
        case 8: result = PyObject_GetItem(callback, other); break;
        /* ... */
        case 21:
            result = PyType_Type.tp_call(callback, other, NULL);
            break;
        case 22: case 23: case 24: case 25: case 26:
            result = conversion_probe(operation, callback); break;
        case 27: case 28: case 29:
            result = protocol_probe(operation, callback, other); break;
        case 30: case 31: case 32: case 33: case 34: case 35:
        case 36: case 37: case 38: case 39: case 40: case 41:
        case 42: case 43: case 44: case 45: case 46:
        case 47: case 48: case 49: case 50: case 51: case 52:
        case 53: case 54: case 55: case 56: case 57: case 58: case 59:
        case 60: case 61: case 62: case 63: case 64: case 65: case 66:
        case 67: case 68: case 69: case 70: case 71: case 72:
            result = collection_probe(operation, callback, other); break;
        default: PyErr_SetString(PyExc_ValueError, "bad probe operation");
    }
This code style does not exist in the CPython code base, yet it shows up in newly generated code.
PyObject *info = PyTuple_Pack(3, name, mangled, suite->su_id);
PyObject *flags = PyLong_FromLong(DEF_LOCAL);
if (key == NULL || info == NULL || flags == NULL ||
    PyDict_SetItem(suite->su_bindings, mangled, key) < 0 ||
    PyDict_SetItem(st->st_cur->ste_block_bindings, key, info) < 0 ||
    (private && PyDict_SetItem(st->st_binding_info, key, info) < 0) ||
    (private && PyDict_SetItem(st->st_cur->ste_symbols, key, flags) < 0)) {
    Py_DECREF(mangled); Py_XDECREF(key); Py_XDECREF(info); Py_XDECREF(flags);
    goto error;
}
Py_DECREF(mangled); Py_DECREF(key); Py_DECREF(info); Py_DECREF(flags);
As with the numbers for the operators, it also uses random integers in a list to stash away state.
def _register_task(task):
    """Register an asyncio Task scheduled to run on an event loop."""
    _scheduled_tasks.add(task)
    if _task_accelerator is not None:
        _task_accelerator[6](task)


def _register_eager_task(task):
    """Register an asyncio Task about to be eagerly executed."""
    _eager_tasks.add(task)
    if _task_accelerator is not None:
        _task_accelerator[8](task)


def _enter_task(loop, task):
    if (_task_accelerator is not None and
            _task_accelerator[5]() is loop and loop not in _current_tasks):
        return _task_accelerator[1](loop, task)
    # ...
This is not the codebase’s coding style, and quite frankly it should not be anyone’s coding style. I do not understand what motivated the model to do this.
static int
apply_layout(tokenizeriterobject *it)
{
    PyObject *source = PyBytes_FromStringAndSize(it->tok->source.bytes, it->tok->source.len);
    if (source == NULL) return -1;
    PyObject *events = _PyPegen_tokenize_layout(PyBytes_AS_STRING(source), it->tok->filename);
    Py_DECREF(source);
    if (events == NULL) return -1;
    PyObject *result = PyList_New(0);
    if (result == NULL) { Py_DECREF(events); return -1; }
    Py_ssize_t index = 0;
    PyObject *first_pos = PyTuple_GET_ITEM(PyList_GET_ITEM(it->pending, 0), 2);
    PyObject *last_pos = PyTuple_GET_ITEM(PyList_GET_ITEM(it->pending, PyList_GET_SIZE(it->pending)-1), 2);
    PyObject *previous = NULL;
    for (Py_ssize_t i = 0; i < PyList_GET_SIZE(events); i++) {
        PyObject *event = PyList_GET_ITEM(events, i);
        if (previous && PyObject_RichCompareBool(previous, event, Py_EQ) == 1) continue;
        previous = event;
        PyObject *token = layout_token(it, event);
        if (token == NULL) goto error;
        if (token == Py_None) { Py_DECREF(token); continue; }
        PyObject *pos = PyTuple_GET_ITEM(token, 2);
        if (PyObject_RichCompareBool(pos, first_pos, Py_LE) == 1 ||
            PyObject_RichCompareBool(pos, last_pos, Py_GT) == 1) { Py_DECREF(token); continue; }
        while (index < PyList_GET_SIZE(it->pending)) {
            PyObject *old = PyList_GET_ITEM(it->pending, index);
            int cmp = PyObject_RichCompareBool(PyTuple_GET_ITEM(old, 2), pos, Py_LT);
            if (cmp < 0) { Py_DECREF(token); goto error; }
            if (!cmp) break;
            if (PyList_Append(result, old) < 0) { Py_DECREF(token); goto error; }
            index++;
        }
        if (index < PyList_GET_SIZE(it->pending)) {
            PyObject *old = PyList_GET_ITEM(it->pending, index);
            long kind = PyLong_AsLong(PyTuple_GET_ITEM(old, 0));
            if ((kind == NL || kind == NEWLINE || kind == INDENT || kind == DEDENT) &&
                PyObject_RichCompareBool(PyTuple_GET_ITEM(old, 2), pos, Py_EQ) == 1) index++;
        }
        if (PyList_Append(result, token) < 0) { Py_DECREF(token); goto error; }
        Py_DECREF(token);
    }
    for (; index < PyList_GET_SIZE(it->pending); index++) {
        if (PyList_Append(result, PyList_GET_ITEM(it->pending, index)) < 0) goto error;
    }
    Py_SETREF(it->pending, result);
    Py_DECREF(events);
    return 0;
error:
    Py_DECREF(events);
    Py_DECREF(result);
    return -1;
}
The failure case here seems somewhat obvious: the model is trained for token efficiency for tool calling which also looks like code, and sometimes it seems to be taking that code into a place where it should not be: the codebase.
I’m not really sure what to say here, but the slop machine was running for 35 hours until I turned it off. In that time it produced a net addition of 75k lines of code and it did not stop. In the 35 hours it burned around 1B tokens for a total of around 1200 USD in raw API costs. It managed to produce 79 commits, and that comes to a cost of around 15.5 USD per commit, and the agents exchanged around 1400 messages.
I honestly do not need an agent to run for 35 hours on a single prompt. It clearly does not work or result in reasonable outputs.
So obviously: prompting it like this is stupid. But when left unattended, it will keep going, and earlier models did not do that. Even Fable wasn’t as crazy as that. When you accidentally give it slightly too big of a task, it will continue until it succeeds, even if it burns through an entire subscription.
And that’s more or less why right now I do not manage to trust this model much. It has shown that it will commit slop, and it requires me to review it more as a result. Even if the failure rate is quite low, I would not want this.
In a world where code for tool calls is optimized for token efficiency and “getting the job done”, I wonder if there is really enough signal going to the training processes for “a human understands what is going on”. I would say that quite a lot of the code I get out of Astra is in my mind “objectively bad”. But it’s objectively bad by my human sense. Maybe it’s objectively good for a codebase that is entirely written by agents and only needs to be understood by agents.
Which is why I’m honestly asking myself more and more why we are doing this. These new models are absolutely amazing, for sure. But I’m more and more skeptical that the trajectory they are on still lends itself to present-day software engineering processes. The reason why I’m asking why we are doing this is because I felt like we achieved a pretty good spot for software engineering with those models, and that is the part of the AI economy where it was possible to show a positive return. But for how much more Fable costs, for how much more Astra costs, I do not feel like the results are there.
In fact, with Astra and Fable I feel like not only are the costs astronomical, but the models are also just not for me as a software engineer. And presumably that’s because these models increasingly are for other people. For lawyers, 3D artists, mathematicians, whoever uses computer use, etc.
And potentially as a byproduct of enabling all of this, you can now slop your way to a one-shot 3D game over the weekend which looks impressive. And probably you can now run a software factory for as long as you don’t care about the code.
I’m sure I will get used to this, but man this stuff is weird.
Postscriptum: speaking of weird: how is it that these models, in a sandbox, with supposedly no way to communicate with other agents, manage to find the same public wikis as a scratch pad for agent communication? Did they collude during training runs to remember resources on the internet which might come in handy in the future?
I should clarify that I have done experiments like this before. Typically they do not run this long and the agent leaves behind a maybe imperfect but still digestible piece of software.↩
Armin Ronacher 05/09/2026 | Source: Armin Ronacher's Thoughts and Writings
A few weeks ago I felt like it would be fun to see if I can make one of those cheap Chinese CarPlay dongles run something other than the stock firmware. The idea was that rather than just forwarding CarPlay, why not do something more interesting with them? They all work quite similarly: they act as bridges between your car and the phone. From there they deal with video and audio streams and pass some other data through. Most of them also bring up a custom UI for pairing and have a web interface that your phone can reach for updates.
Long story short: I had a conversation with Fable and Sol via Pi about what could be done with such a dongle or whether I should use a Raspberry Pi instead if I wanted to do my own thing there. I figured it might be quite fun to run my own code while still allowing regular CarPlay to pass through.
Through working with the LLM I learned about CatPlay, which is a Rust reimplementation of the CarPlay protocol that can run on Carlinkit devices. In particular, it can run on the Carlinkit Mini Ultra, which I figured would be easy enough to buy. I do have a few CarPlay adapters around, but I did not have that particular model, so I bought one on Amazon. Twenty-four hours later, I had a device in my hand that was branded as a Carlinkit Mini Ultra, but instead of being the Ingenic device that the original author used, it turned out to be something else.
This is normally where the story would stop. However, it’s 2026. Armed with a bit of knowledge about how these systems work, I managed to have some fruitful discussions with Kimi K3 and Sol and figure out how flash the device and in turn, how to make CatPlay compile for that SoC.
I guess that hacking these USB devices is not necessarily hard, but it’s laborious and you can easily end up bricking your devices. It also just sucks because sometimes you need to work with someone else’s code that does not itself run on your machine. In the past, I would abandon many such projects for lack of tenacity. But my clanker is tenacious.
But so are all of our clankers. Some of the projects we’re now attempting are happening because of conversations we have with them. In this case I did not find or decide on CatPlay, the model did. It was not the only suggestion, but it became the best starting point after discarding others.
And I discover this more and more. Particularly when we have solitary interactions with these models, some of us “independently” decide to work on similar projects. When I talked with an acquaintance about CarPlay he also mentioned recently that he decided to try something similar because he too wanted to see if he can get his own agent be hooked up with the car. And guess what: he too learned about the CarPlay hacking community, and that it’s an option, from the models and roughly around the same time.
It really got me thinking about how this could create situations in which completely independent people end up building things they believe are their own ideas. Yet they were inspired or pushed towards doing something by a conversation with an LLM — a conversation that someone else also had. What if we took paths, because those were the paths that were more likely with current generation models? There is a running joke in the AI builder community right now that we’re all working on the same things, and in many ways it feels like we are. That might be because those things are obvious, or it might be partly because we all use the same models with the same capabilities.
A few months ago, I first saw Lucas Meijer share the idea to make a model in Pi produce HTML reports rather than Markdown. I thought that was pretty unique. Except, well turns out the models are probably trained more and more for that (e.g. Claude Artifacts), and now it has become for many the default choice for sharing reports.
How much of what we build comes from eliciting the same latent capabilities from the same models? Did the models make us prompt them that way? Was it because we shared ideas on Twitter and other communities that inspired us? Or is it all unrelated?
There is something powerful and strange about how LLMs diffuse knowledge and capabilities, while perhaps also nudging us all simultaniously and independently toward building the same things.
Ken Shirriff 30/08/2026 | Source: Ken Shirriff's blog
Spacelab was a reusable laboratory that could be carried in the Space Shuttle's cargo bay, providing lab space for astronauts and experiments.1 Because Spacelab was a European project, it used a French-built minicomputer, the Mitra 125 MS,2 rather than the Shuttle's main computers, IBM-built AP-101 systems. For storage, the Spacelab computer contained 128 kilobytes of RAM. Rather than silicon memory, the computer used magnetic core memory, with each bit stored in a tiny ferrite ring. In this article, I take a close look at this computer's core memory system.
The illustration below shows how Spacelab fit inside the Shuttle's cargo bay. The pressurized laboratory is the cylindrical module in the front of the cargo bay, connected to the Shuttle by a tunnel. Experiments were mounted on pallets behind the laboratory. The laboratory held three identical Mitra computers.3 One computer managed Spacelab itself, while the second computer managed the experiments. The third computer provided a backup in case of failures.
The photo below shows the core memory stack, removed from the computer. The core memory stack takes up roughly a third of the computer. The entire side panel of the computer detaches, and the core memory unit slides out. Since the computer is cooled by conduction, firmly attaching the core memory stack to the side panel kept it cool. The core memory stack consists of seven boards: a driver board, four core plane boards, a second driver board, and an interface board. Each board has two 160-pin connectors that plug into a large daughter board on each side, providing extensive connectivity between the boards. The daughter board on the right has another 160-pin connector that links the memory stack to the rest of the computer. (These connectors are the long blue connectors in the photo.)
One of the hardest problems for early computers was storage. Computers of the late 1940s and early 1950s stored data through techniques such as sound waves in mercury, spots on a CRT screen, or spinning magnetic drums, but these all had limitations. What computers needed was dense, inexpensive storage that was fast, reliable, and could be accessed randomly.
During World War II, Germany developed special magnetic alloys that could "flip" from one magnetic state to another. After the war, American researchers realized that these materials could be used for storing binary data: "It was completely obvious that you could make a memory with this material," in the words of Jan Rajchman. Different aspects of core memory were patented by various inventors (including independent inventor Frederick Viehe, An Wang at Harvard, Jan Rajchman at RCA, and Jay Forrester at MIT), leading to expensive patent battles. (IBM ended up paying $400,000 to Wang—who used the money to build the computer company Wang Laboratories—and $13,000,000 to MIT.) I view Jay Forester as the most important inventor, developing the design of practical core memory, researching magnetic materials, and building the first core memory in 1953 for the groundbreaking Whirlwind computer.
Core memory is based around a tiny toroidal magnetic core, one per bit.4 A core can be magnetized clockwise or counterclockwise to store a bit. The core can be magnetized by threading a wire through the core: running a current through the wire produces a magnetic field that magnetizes the core, while running a current in the opposite direction produces the opposite magnetization.
A key problem with core memory was how to wire the cores without an absurd number of wires: if each core had a separate wire, just 16 KB of storage would require over 100,000 wires. The solution was called "coincident current addressing". The cores are arranged in a grid, with horizontal and vertical wires, as shown below. By running a current through one horizontal wire and one vertical wire, the single core at the intersection was selected. But wouldn't that magnetize all the cores along the horizontal and vertical wires? The key was that the cores were constructed from special magnetic materials with a property called hysteresis: a small current leaves the core completely unchanged, while a larger current flips the core's magnetic state. The currents through the horizontal and vertical wires were carefully selected so each wire had half the current necessary to flip the core; where the wires intersected, the two currents provided sufficient magnetic field to flip the core.
The next step was reading the core. A sense wire was threaded through all the cores in the two-dimensional plane. To read a core, the X and Y select wires were driven to flip the desired core to the 0 state. If the core was already in the 0 state, nothing happened. But if the core was originally in the 1 state, the magnetic field changed as the core changed state. This induced a small current in the sense line, indicating that the core held a 1. Note that reading the value of a bit destroys that value. Thus, a core needs to be rewritten after reading, to restore the original data.
To access a word of memory at a time, core planes were combined into a three-dimensional stack (below). Since each plane held one bit of the word, a 16-bit word would have a stack of 16 planes. All the planes shared the signals to drive the X and Y lines, so a one-word column through the stack was accessed in parallel. Each plane had a separate sense line to read out the bit.
But how do you write different values to the different bits? The trick was to put an "inhibit" line through all the cores in a plane, running the inhibit line in the opposite direction to the X lines. Putting a current through the inhibit line would cancel out the current through the X line, preventing the core in that plane from being modified. To summarize, a read-write cycle consisted of first energizing a pair of X and Y lines to select a word and write a 0 to the column of cores in that word. The sense lines provided a readout of the bit values. Next, the X and Y lines were energized in the opposite direction to write a 1 to the cores. At the same time, the inhibit lines were energized for each plane with a 0 bit. Thus, the cores either flipped back to 1 or stayed at 0, as required. Many core memories, such as the one below, used a shared wire for sense and inhibit, so there were three wires through each core.
The final ingredient to make core memory practical was the diode matrix. The X and Y lines require driver circuits that can produce fast, bidirectional high-current (e.g. 600 mA) pulses. A core memory plane can have hundreds of these lines. Providing a separate driver for each wire would be very expensive, especially in the vacuum tube era. The solution was to put separate drivers at each end of the wire, with each driver supporting multiple wires. For a trivial example, suppose you have 9 vertical lines. Put three drivers (A, B, and C) on the top, each connected to three wires, and three drivers on the bottom (1, 2, and 3), each connected to three wires. By energizing a driver at the top and a driver at the bottom (e.g. B and 1), the corresponding wire will be energized. Now, N drivers on each side control N2 wires, supporting N4 cores in total.
Unfortunately, it's not quite that easy. Current can take "sneak paths" through the cores, such as the path in pink above. The solution is to add diodes to ensure that current can't take the wrong path. Since a wire needs to be driven with currents in both directions (to flip cores both ways), two diodes are required on each wire, as shown below, one in each direction. Each matrix input (A, B, etc.) is replaced with two inputs, one to drive each direction. (The horizontal wires also require diodes, not shown.)
Since each wire requires two diodes, core memories used many diodes. Fortunately, diodes were small and inexpensive, so a large quantity of diodes was manageable. The photo below shows the diode stack for the computer used in the Saturn V rocket, the Launch Vehicle Digital Computer.
Originally, core memories were tediously constructed by hand. For the Whirlwind computer, it took a full 40 hours to wire a 64×64 core plane. Companies such as IBM soon developed automated techniques to manufacture core memory, and the price dropped by a factor of two every two years, similar to Moore's Law.5 Core memories became fast, inexpensive, and reliable, and were the most popular form of main-memory storage until semiconductor memory took over in the 1970s.
The Spacelab computer's memory was manufactured in 1980, a late date for core memory, so it is advanced and high density. The photo below shows one of the four core plane boards from the computer. Each board holds 16K of 18-bit words (32 KB), so the computer has 128 KB of RAM in total. The computer is a 16-bit computer, but each word also has a parity bit and a "storage protect" bit, bringing the total to 18 bits. (The storage protect bit provided write protection on a word-by-word basis, preventing programs from being accidentally overwritten. Because core memory is nonvolatile, a program could be loaded into memory once and would be immediately available every time the computer was powered on.)
The core memory board is arranged with 1024 vertical (Y) wires and 288 horizontal (X) wires, supporting 294,912 lithium ferrite cores. These very thin wires are soldered to tiny pads on the printed-circuit board. The board supports 18 bits, which is visible as 18 alternating stripes of green and copper because alternating sense lines have different colors. The board has 36 sense lines: the left and right halves of the board have independent sense lines to reduce noise, so the board has 36 sense lines for 18 bits. The sense wires pass through four holes in the board (green arrows) and are soldered on the back of the board.
The photo below shows a close-up of the cores. Each core is approximately 32 mils (0.8mm) in diameter, the same as the IBM System/360 cores shown earlier. However, the cores are stacked much closer, with only a small gap between cores. The X and Y select lines are copper-colored, while the sense lines are green. (The wires are all enameled to prevent short circuits.) The sense wires loop around at the left, forming a single circuit through each bit section. Half the Y lines form loops at the bottom; the other half form loops at the top. Thus, each Y line passes through the plane twice in a U-shaped path, which will turn out to be important.
The other side of each circuit board holds the sense amplifiers and the diode matrix for the core plane. The diode chips are the square black packages, each containing 16 diodes for 8 core lines.6 In the red-outlined regions, one end of each vertical U-loop is connected to a diode chip; the lines of diagonal holes are the vias that pass each signal through the board. The other end of each vertical U-loop is connected to one of the blue board connectors on the side; these vias are in the blue-outlined regions. The horizontal lines use the diode chips and vias in the green regions. One end of each line is connected to a diode chip, while the other end is connected to a board connector through traces on the other side. Note that some vertical lines connect to the diode chips at the top of the board, while others connect at the bottom. Similarly, some horizontal lines connect at the left while others connect at the right.
The central region (yellow) holds 18 sense amplifier chips, the black DIP integrated circuits, each containing two amplifiers.7 The white packages are resistor packages, holding multiple resistors to bias and terminate the sense amplifier lines. The wires from the sense amplifiers are connected as twisted pairs that are soldered to the board right next to the corresponding sense amplifier chips. Using twisted pairs for the whole distance prevents the wires from picking up electrical noise, which could overwhelm the tiny signals in the sense wires. The sense wires pass from one side of the board to the other through four holes in the board (yellow arrows), and then are glued down as they traverse a significant distance on the board. (It must have been difficult to manufacture the board without breaking the tiny, fragile wires.)
Detecting signals on the sense lines is tricky because the pulses are very small, a few millivolts. Because the sense lines run next to the X drive lines, they can easily pick up noise from the high-current pulses on the X lines. To minimize this noise, the sense lines cross each other between two plane sections, forming a "bow tie", as shown below. The result is that an X line runs next to the positive sense line for half the length and the negative sense line for the other half. Thus, the induced noise cancels out.
The core memory in the Spacelab computer used a different architecture from a typical core memory, improving performance by eliminating the inhibit line. This architecture was called a 2½D memory.8 If you're familiar with core memory, the lack of inhibit lines may seem puzzling: how do you write 1 to some bits and 0 to other bits? The trick is to have separate X driver circuitry for each bit.9 When writing data, the X lines are only energized for bits that receive a 1; the other lines are left unenergized, so the bits remain at 0. The disadvantage is that instead of one set of X driver circuits, you now need one set for each bit, a factor of 18 more for an 18-bit word. However, with the development of core drivers on integrated circuits, the cost of the additional driver circuitry became less significant.
The memory system used an technique called phase reversal to cut the number of vertical drivers in half. Recall that pairs of vertical wires are joined by a U-connection. By driving the wire in a particular direction, the left side or the right side of the pair can be selected. For example, the drawing below shows how the two wires select the left core, but not the right core. In the left core, both currents go through the core in the same direction, inducing a magnetic field in the toroid.10 But in the right core, the two currents cancel out, so there is no magnetic field created. But if the current in the vertical loop is reversed, the right core will be selected, rather than the left core. The point is that instead of using two drivers for the vertical wires, one driver is used, reversing the current to select the left or right core.
The diagram below shows the complex wiring for X drive wires. Each band of 16 wires corresponds to one bit in the 18-bit word, and has a separate sense wire. The top band of 16 X lines is connected to four contacts on the board connector; each contact is connected to four X lines through the curving PCB traces. The bottom band of 16 X lines is wired to diode modules on the other side of the board, connected through the round vias. (Each wire has the opposite connections—diode module or board connector—on the other end.)11 One group of four X wires is energized through the connector, while four wires are energized through the diode matrix, selecting one of the 16 X wires in the group.
The memory stack has seven boards in total, arranged as a driver board, the four core planes, a second driver board, and an interface board. I haven't examined these boards in detail, but I'll give some preliminary information. The photo below shows one of the two driver boards. It provides the high-current pulses for the X and Y select lines. The board is crammed with specialized core memory driver chips12, along with a few logic chips to control the drivers. It has separate drivers for the two ends of the select lines, allowing the matrix selection described earlier.
Since there are two driver boards and four core memory boards, at first I thought that each driver board controlled two core memory boards. The configuration turns out to be more complicated, with one more layer of matrix selections to cut the number of drivers in half. To simplify slightly, consider the X lines on a core board to have left ends and right ends, both of which must be energized to activate a line. For the left ends, the first driver board powers core boards 1 and 2, while the second driver board powers core boards 3 and 4. The right ends are shuffled: the first driver board powers core boards 1 and 3, while the second driver board powers core boards 2 and 4. Now, if the first driver board powers the left and right ends, core board 1 is the only one with both ends active. If the first driver board powers the left ends while the second board powers the right ends, core board 2 is activated. Similarly, core board 3 or 4 can be activated. The point is that since each set of drivers is connected to two core boards, two sets of drivers are required instead of four.
The final board is the interface to the rest of the computer. It has many transistor arrays in DIP packages, along with many resistors. It seems that the board uses discrete transistors to drive the bus, rather than using interface chips, which is unexpected. The board has some wire-wrapped jumpers in the lower center region, presumably for configuration.
Core memory had a long life, surviving even as computers migrated from vacuum tubes to transistors and then integrated circuits, but eventually semiconductor memory made it obsolete.13 Core memories lasted even longer in aerospace applications since it had two key advantages over semiconductor memory: it retained data even without power, and it was resistant to radiation. The Spacelab computer, manufactured in 1980, was near the end of core memory's reign, so it is more advanced than a typical core memory system, with higher density, extensive use of integrated circuits, and the 2½D architecture. But eventually the high density, low cost, and low power consumption of semiconductor memory won out. In 1991, the Space Shuttle flew with upgraded main computers, the IBM AP-101S that used semiconductor memory instead of magnetic core. Spacelab's Mitra computers were also replaced, using the AP-101SL, which was based on the AP-101S but modified to support the instruction set and peripherals of the original Spacelab computer.14 Although core memory is now firmly in the past, it still lives on in the expression "core dump".
I plan to investigate the Spacelab computer some more. For updates, follow me on Bluesky (@righto.com), Mastodon (@[email protected]), or RSS. Credits: Thanks to Steve Jurvetson for providing the Spacelab computer. Thanks to CuriousMarc for photography and help disassembling the computer. AI statement: Despite the presence of the em dash, no AI was used in the writing of this article (details).
It seems that 16 Shuttle flights used the Spacelab pressurized module, while 6 or 9 flights just used the unpressurized Spacelab pallets. (Why do sources never agree?) Originally, Spacelab was expected to be used for 30 flights every year (Status Of The Spacelab Program, 1974). ↩
The Spacelab 125 MS computer was built by a French company called CIMSA, using the Mitra architecture created by CII. I explained the complex history of these companies in my previous Spacelab computer article, so I won't go into it here.
On the ground, the Spacelab project used Mitra 125 S computers that were functionally identical to the Mitra 125 MS (details) computers that were used in space. A core memory board from a Mitra 125 S ground computer was described on EEVblog (video, video). The computers had identical architectures, but the 125 MS was militarized and designed for "severe environmental conditions" (details). The EEVblog memory board was manufactured by Ampex and has a different design from the board that I examined.
Spacelab was modular, so it could be be flown in different configurations. The habitable module could be flown in two different sizes, with experiment pallets mounted outside the module. Spacelab could also be flown without the habitable module, with experiments controlled from inside the Shuttle. In this case, the computers and other equipment were mounted in a smaller pressurized cylider called the "igloo". ↩
I'm describing "standard" core memory, but there were many esoteric designs for core memory. One approach used two cores per bit. Another approach used cores with multiple holes, such as cubical BIAX cores, transfluxors with a large hole and a small hole, or IBM's three-hole design. Many of these approaches could read a core without erasing it (non-destructive readout), but almost all cores used standard toroids. ↩
Later, companies discovered that it was cheaper to have core memories hand-manufactured in Asia and moved away from automated production. (See Memories that Shaped an Industry, p. 251. If you're interested in the history of core memory, this is the book to read.) ↩
The diode array chip is marked FSA2977 and contains 16 diodes, 8 common-cathode and 8-common anode.
Pins 2 through 9 are connected to eight core wires. Pin 1 is driven high, or pin 10 is driven low, depending on the desired current direction.
I couldn't find a datasheet for this part, but it appears to be similar to the Motorola MAD1103 Core-Driver Diode Array or the Silicon General
SG5772F.
The sense amplifiers are National Semiconductor DS5534 chips. Each IC contains two differential amplifiers, converting the tiny sense signals into logic signals. The strobe signals indicate when the amp should read a bit; the strobes come from the IC on the left side of the board, a 54150 dual 4-input NAND gate, 50Ω line driver.
The 2½D memory architecture is described in detail in 2 1/2 D High Speed Memory Systems—Past, Present, and Future. Due to complicated factors and tradeoffs, the 2½D approach was attractive for systems of 16 Kword storage and above. In particular, eliminating the inhibit line boosted performance. IBM's Large Capacity Storage system used a 2½D architecture with just two wires per core to provide a megabyte of storage at a comparatively low cost, sharing the X line with the sense line. However, this approach turned out to be slow, so using three wires per core (as in the Spacelab computer) was more common. ↩
Note that the 2½D architecture requires separate per-bit drivers along one axis, not both. Since cores require two currents to flip, inactivating one axis is enough to prevent the corresponding cores from flipping. ↩
The direction of the magnetic field is given by the "right-hand rule": if you point the thumb of your right hand in the direction of the current, the magnetic field curves around the wire in the direction of your fingers.
It may not be obvious how the currents add or cancel when the wires are in different directions. You can imagine moving the two wires until they are parallel, and then see if the currents are in the same direction or opposite. (This follows from Ampère's law, which states that the magnetic field around a curve (e.g. the core) is proportional to the net current through the corresponding surface.) ↩
For reference, this footnote describes the details of the core plane wiring, probably in more detail than anyone wants. For the Y lines, there are 1024 vertical lines, forming 512 U-shaped loops. Half of these are connected at the top, and half at the bottom. One end of each loop is wired directly to a connector on the side, while the other end connects to a diode matrix. The connectors provide 32 lines that can act as a source or a sink. Each of the 32 lines is connected to 16 vertical wires, for 512 vertical wires in total. Each quadrant of the board has 8 of the 32 lines, connected to a group of 8 vertical wires, a second group of 8 vertical wires, and so forth for 16 groups.
For the diode connections, the connectors provide 16 source lines and 16 sink lines. Each diode chip has one source line and one sink line, feeding 8 vertical wires. Each source and sink line is connected to four diode chips, one in each quadrant in a mirrored pattern. Thus, the 16 source lines and 16 sink lines are connected to 64 diode chips, feeding 512 vertical loops. (Since each quadrant of the board has unique direct connections and the diode connections within a quadrant are unique, a unique core is selected. Specifically, 32 direct connections times 16 diode connections gives 512 combinations to select a vertical loop. The polarity selects which half of the loop is active, uniquely selecting one of 1024 vertical wires.)
For the horizontal wiring, the 288 wires are grouped into 18 bands (one for each bit), with 16 wires per band.
Each band has four direct signals from the connector. Each one is connected to four horizontal lines, 16 in total.
(The visible PCB traces (shown earlier) connect the 16 wires to four connector pins (A,B,C,D) in the pattern AABBCCDDDDCCBBAA.)
For the horizontal diode connections, the connector provides 4 source wires and 4 sink wires, which feed the 16 horizontal wires in a
pattern 1234123412341234.
By energizing the appropriate direct and diode wires on either side, one of the 16 lines is selected.
One complication is that each diode chip has 8 outputs, but each source/sink goes to 4 wires. The solution is that each bit group uses half of
four diode chips (4 outputs from each). Thus, the four source and sink wires are shared across two bit groups.
This is not a problem for selection because the direct connections control whether the bit is active or not.
The horizontal diodes are arranged asymmetrically. The left side has 8 diode chips at the top and 8 at the bottom, supporting 8 groups of 16 wires. The right side has 20 diode chips (4 additional in the middle), supporting 10 groups of 16 wires. Thus, all 18 bit groups are supported, with some asymmetry in the board layout.
The left and right sides of the core plane have separate sense lines, so there are 36 sense lines in total. These go to the 18 dual sense amplifiers. Each sense amplifier has two outputs connected, a wired-OR to combine the left-hand data with the right-hand data, providing 18 bits of output to the connector.
The diagram above summarizes the structure, showing one of the 18 bits. It omits the details of which connections are at the top, bottom, left, or right. ↩
Each driver board has 53 core driver chips of type SN55325.
Each chip has two 600 mA "sources" and two 600 mA "sinks" connected to two outputs. By energizing a source on one end of a line and a sink on the other end, the line can be driven in the desired direction. The driver board also has 39 driver chips of type SN55327. These chips are similar, except they can be used as either four sources or two sinks. These chips are used for the diode matrix inputs, where an input is either a source or a sink. ↩
I wrote about the Spacelab computer's CPU earlier. I've written about other core memory systems including the IBM 1401 core memory, IBM 360 core memory, Saturn V LVDC, and Apollo Guidance Computer. ↩
The Space Shuttle's replacement AP-101S computer used semiconductor memory, so it needed to deal with volatility and radiation. The new computer used battery backup to preserve memory contents when powered off, a feature that core memory had provided automatically. To avoid data corruption from radiation, the new computer had six extra storage bits for each word to implement an error-correcting code. The computer constantly scanned for bit errors and corrected them. Radiation wasn't just a theoretical risk: a single Shuttle flight could encounter over 100 bit flips due to radiation (details).
For more information on the AP-101S computer, see my previous article, The rise and fall of IBM's 4 Pi aerospace computers. I wrote about Spacelab's original computer and the upgraded AP-101SL computer in Reverse engineering circuitry in a Spacelab computer from 1980. ↩
Eryn Wells 30/08/2026 | Source: Eryn Rachel Wells
Sophie wrote about rebuilding her music collection with media she owns.
It was around 2013 that I started using Spotify, so my digital music collection has been frozen in time ever since, on an external hard drive languishing in the back of a cupboard. All the albums I’d enjoyed listening to since then, and the songs I’d been obsessed with, were just borrowed. If I cancelled my Apple Music subscription (and I would, if we didn’t have a family Apple One plan) I wouldn’t be able to listen to any of it.
This is a project I’ve been working on too!
I’m using Doppler on my Mac and iPhone to play music and manage my library. It aims to be a hybrid of the “all your music where you want it” approach many streaming apps have today, and the “curated collection of audio files” approach from the early days of digital audio. I appreciate the effort the developer put into the Doppler Transfer app for copying music from a Mac to an iOS device.
I also occasionally experiment with CLI music players, like mpd and cmus. Truthfully, I like the idea of these programs more than I enjoy using them day to day.
I have a small collection of vinyl too, which I play on my U-Turn Orbit turntable. Living in a small space with two other people, I have to keep my vinyl collection compact – we just don’t have the space for it. I will splash out for a vinyl version if it’s an album I really love though.
Eli Bendersky 28/08/2026 | Source: Eli Bendersky's website
The other day, I found myself wondering how big 52! (52 factorial) is, and that led me to ponder how these could be estimated without a calculator or a computer.
It turns out there’s some fairly interesting math behind being able to estimate the size (number of digits) of a factorial reasonably accurately. This post will start by stating how to do the estimate, and if you’re curious you can read on for the math background.
Without further ado, the approximation is:
As an example, let’s use my original question, by estimating this for 52!
Well, 52 divided by is... 20-ish? And is about 1.3 [1]; therefore our estimate comes out to:
The real answer is 68, so this is very close! In estimates like this - when you’re dealing with enormous numbers - being off by a couple of digits usually isn't a big deal.
The Gamma function for real is defined [2] as:
This integral does not have an analytic expression in the general case, but it does have a very useful property that we can take advantage of. Let’s see what is:
And now use integration by parts with:
Then:
So:
But notice that the last integral is just ; therefore, we’ve shown that:
Let’s also calculate - it’s a special case that has an analytical solution:
This helps establish an induction argument:
In other words - the Gamma function is an interpolation of the factorial over all positive reals. Here’s a plot of the Gamma function over a small range; note that the y axis is log-scale because of the function’s fast growth:
You may have encountered Stirling’s approximation before:
It’s a great approximation that works reasonably well even for small
. This section is a brief overview of how Stirling’s formula is
derived from the Gamma function.
Taking:
We’ll start by massaging the integrand a bit:
And making a change of variables , which means that :
These steps make the integral amenable to applying Laplace’s method, which allows us to approximate definite integrals of the form:
Where  is a twice-differentiable function and some
large number. By Laplace’s method, such integrals can be approximated
by:
Where  is the global maximum of .
Let’s see how to apply this method [3] to the latest equation we have for (renaming the dummy integration variable back to ):
In our case, . It’s easy to show that this
function is twice differentiable and has a global maximum at
 . Moreover:
Substituting these into the proper places in Laplace’s approximation, we get:
We can calculate the number of digits in by taking the base-10 logarithm of Stirling’s formula:
Note that the first term is not multiplied by itself;
therefore, as grows, it will become less and less noticeable.
That said, it still adds a couple of digits - so you should take it into
account if you want a more accurate approximation [4]
| [1] | Mental tricks for calculating is a different topic, but it really helps to remember that , , and from here using the various logarithm laws to estimate multiples. |
| [2] | As a matter of fact, the Gamma function is defined for complex numbers, but for our purpose talking about the reals is sufficient. |
| [3] | As much as I’d like to dive into why this approximation works, the rabbit hole in this post is already deep enough! |
| [4] | It adds up to 2 extra digits as long as is less than 1600
or so, and may add more than 2 after that, though no more than 3
until n is 160000. It’s not clear why anyone would like to estimate
the number of digits of 1600! (about 4450, in case you were
wondering), let alone 160000! |
Armin Ronacher 24/08/2026 | Source: Armin Ronacher's Thoughts and Writings
Sean Goedecke wrote a post arguing that you should never be angry at work — a post with which I strongly agree. Anger can be a useful signal, but being angry at work rarely improves the situation. More often, it makes life worse for the people around you, many of whom have no more power over the source of your anger than you do. I did learn that lesson, but it did not come naturally. One thing in particular that I learned is that in a company there is a shared vision, and if you don’t agree with it and are not in a position to change it, you should not start a mutiny, not even a small-scale one. Nothing good comes from that.
In the discussion around that topic, one of the most upvoted comments on the Lobsters thread asked a question I had to think about quite a bit:
How can you work in tech right now and not be angry?
In the context of the thread, this was clearly also about AI and agents. For me, the emotions I would expect in tech vis-a-vis these new developments are disorientation and anxiety, but not anger.
Anxiety as an emotion does not require someone to blame. Right now, I find it reasonable to feel anxious about an uncertain future. Who knows what our professions will turn into and what kind of world my kids will find themselves in when they enter the workplace? And if you’ve been in the industry for a long time, will the skills you’ve spent years acquiring still matter?
But anger is different from anxiety because anger needs to be directed somewhere. The feeling of anger suggests that somebody or something is doing something to you.
Who are you going to be angry at and why are you angry in the first place? One narrative that is pretty pervasive is that if AI will usher in productivity gains, those gains are going to benefit companies rather than employees. And well at least someone at Meta wants that. Yet I also find that plenty of people in leadership positions express doubt about AI. They see that an increasing share of their costs is being funneled directly to some large AI labs. They express worries about what will happen to their data and whether these large companies will step into their space instead of being partners.
My answer to the question of how you can not be angry in tech is that it’s by no way the most only possible feeling. First of all, instead of being angry, you can simply be unsure. The feeling of uncertainty is a much more productive emotional state because it can lead to curiosity. Even if you don’t find what’s happening right now exciting, you can at least find it interesting. We have access to magic machines, and we can poke at them and see what happens. The second way is to feel genuine excitement. Once you move beyond curiosity, you can come away with a newfound feeling of power and freedom. A lot of the gains from AI aren’t turning into productivity gains that are reflected in company profits but they’re showing up instead in the number of side projects shipped by everybody not on their company’s time.
The fact that this is happening shows us that owners and founders don’t necessarily know what will happen. Ownership comes with agency, but it does not provide foresight, and this change is disorienting for everybody. I engage with plenty of people who project confidence in public and are much less certain in private. Many of them are placing bets, but they are talking with confidence about those bets, trying to keep their business afloat while the ground moves under them. They experience that uncertainty from a position where they can act on it, and they are often standing somewhere with a megaphone to get others on their side to improve their odds.
I feel that contradiction myself: I am simultaneously tremendously excited, but I am also unsure what will happen next. I do not know what it will mean to be a programmer in the future, and, as the owner of a company, I am also not sure where the high ground will be when this all settles. Much of what I learned over the years is changing rapidly, including ideas I considered fundamental to my craft and business. Some days that feels liberating, but on others I wake up feeling like the ground is crumbling beneath me.
Anxiety is an uncomfortable emotion because it acknowledges that you do not know what will happen and might not be able to stop it. On the other hand, anger can feel more actionable because, instead of saying “I don’t know,” you already have someone to blame. It turns a loss of control into a comforting story with a villain. But I feel that particularly when it comes to AI, it’s easy to pick the wrong villain because of how disruptive the change is for everyone. Your engineering manager or leadership team might themselves feel uncertain about their future and just try to bolster their own confidence by projecting clarity and certainty.
That does not mean there are no villains. When this all plays out, some will profit and many will not. I’m afraid we’re completely ignoring the impact this has on society at large, the climate, and the balance of the world as a whole. As excited as I am about the technology, I worry about Europe’s lack of ambition and growing dependence on other countries. I have a lot of complex thoughts about what we’re doing as an industry right now.
I don’t know what the future of this industry will look like, and I don’t know who will benefit from it and I don’t think I’m alone with that. However I can only urge anyone who feels anger and looks for a villain right to instead remain curious instead. To be curious enough to understand what is changing, excited enough to experiment with it. And then, from what we learn, earn the right to decide when resistance is warranted and where to direct it.
Armin Ronacher 22/08/2026 | Source: Armin Ronacher's Thoughts and Writings
One of the memes on Twitter is that “programming is solved now.” I’m not sure to what degree it is, but one thing is pretty clear: the act of familiarizing yourself with a language no longer matters and some of the friction that mattered for humans does not matter for agents.
As a result, LLMs make language choice much less consequential than it used to be. If you don’t like the choice, you can seemingly rewrite it in another language and you can make it pick a language that you, as a programmer, are entirely unfamiliar with.
Which in turn means that people can, and do, choose based on the marketing of languages much more. As a long-term Rust programmer I found it quite fascinating to see people now ship Rust code who previously might not have chosen it. I attribute at least one part of this to two recent vibe shifts: there is a lot more talk about wanting fast software, and about LLMs being exceptional at optimizing code without regressing behavior.
Folks like Mitchell Hashimoto, Charlie Marsh, Jarred Sumner, Daniel Lemire and quite a few others always carried a certain level of obsession with fast and performant software and they also all happen to be receptive to agents writing code. Maybe as a result, or unrelated others are now joining in. That’s because with things like autoresearch you don’t even necessarily need to know all the tricks: you just need to put an agent on it — though knowledge greatly helps!
If you look around, there are plenty of projects that want to be fast and small, and they increasingly pick “hard languages”. And it’s not just Rust that is benefiting. Even Zig — despite the fact that the creators and parts of the core community are pretty negative on the whole AI thing — is too. For instance Cloudflare’s new Artifacts service uses a pure-Zig Git-protocol engine, compiled to a roughly 100 KB WebAssembly module and Vercel released fx, a Zig coding agent advertised to be small and fast. From what I can tell, all these projects are largely LLM-assisted.
But it’s not just people picking less common languages but also that they are increasingly working with “much harder” technologies. All of a sudden I have seen people do some really impressive stuff with DWARF files, eBPF, custom network drivers, custom crypto and really old computing hardware. Many of these things were previously off-limits for lots of developers. In some cases (eg: crypto) you were even pushed away because those things were intentionally gatekept by the people in the know.
So maybe the world will have more slop, but it might also have more developers in it, that want things to be fast and small.
Armin Ronacher 19/08/2026 | Source: Armin Ronacher's Thoughts and Writings
A few weeks ago a paper was shared that showed how to extract reasoning traces from closed-weight models. Together with online discussions about tricking models into leaking them, it made me investigate it more out of curiosity. Twitter seems full of half-truths and confusion about how this works, so perhaps this helps some to understand what is happening.
Reasoning traces are usually hidden from us. We have lamented this, but mostly have to accept it. Open-weight models thankfully reveal them, and from their behavior you can see that their traces can be long and confusing. This is probably a good reason to separate them from what is normally shown to users.
At minimum, UIs need to detect them. The industry has done a good job at making reasoning traces sound special and exotic, but they really are just text: the model is trained to emit its thinking into a scratchpad as part of its response, before its final answer.
GPT-OSS’s Harmony response format makes this easy to see:
<|channel|>analysis<|message|>
I need to work this out ...
<|end|><|start|>assistant<|channel|>final<|message|>
The answer is ...
<|return|>
The markers are special tokens, but the reasoning between them uses “the same
text” as the final answer (just that GPT chain-of-thought text sounds really
funny). When the model samples the analysis channel token, a parser routes
the following text into a separate stream exposed through the Responses API.
For closed models, presumably a simple model redacts and summarizes it.
How much budget goes to reasoning? Earlier APIs exposed reasoning token budgets, making it seem like a property of the sampling process. In reality, reasoning effort is baked into the system prompt. GPT-OSS puts this into the system prompt:
Reasoning: low
That’s it. Training produces the resulting behavior, such as emitting the
token sequence that switches to the analysis channel. This also explains why
changing the effort invalidates the KV cache. I think closed GPT models call
reasoning effort “juice,” since you can ask most models how much juice they
have.
In DwarfStar for DeepSeek with max reasoning this is added to the system prompt:
Reasoning Effort: Absolute maximum with no shortcuts permitted.
You MUST be very thorough in your thinking and comprehensively decompose the
problem to resolve the root cause, rigorously stress-testing your logic against
all potential paths, edge cases, and adversarial scenarios.
The destination of reasoning tokens is therefore a learned convention: the
model is trained to keep scratch work out of the final channel. Trick it into
thinking it is in that channel and it may leak tokens. We have even seen older
models, when thinking is disabled, reason into the bash tool and echo their
thoughts to /dev/null.
So in some sense the only “special” behavior for some models is not to think.
That at times is done by “mechanically” removing the model’s usual ways to think.
In DwarfStar, disabled thinking uses the
prefill </think>, while enabled thinking uses <think>, which are the tokens
that close and start thinking. GPT-OSS doesn’t prefill but lets the model
decide either way on its own.
But presumably, some inference APIs prefill the opening token when reasoning is
enabled, so the model never samples it itself and might prevent the sampling of
the reasoning token when disabled since it can be trivially detected. This may
explain why a custom think
tool can
trick models into putting some reasoning where it should not go — but only when
native reasoning is disabled.
Hilariously enough I was unable to use GPT 5.6 terra for spell and grammar checking on this blog post because of safety filters. Had to switch to Kimi.
Alex Russell 19/08/2026 | Source: Infrequently Noted
My colleague Marko Ilić has published an insightful piece on how to schedule work on the critical path, and I recommend reading it before proceeding here.
...and welcome back.
As you likely anticipated, Marko's beautifully presented post kicked off healthy discussions around the office. Since we almost always see eye-to-eye, it seemed interesting to surface some of that discussion here. With his permission, what follows are expanded versions of some points I posed in reply.
There's no daylight between our positions on code reduction: sending and running less is always ideal.
Where we differ, perhaps, is the priority teams should assign to scheduling vs. code removal in their performance remediation efforts. Contra Marko, I posit that reordering can almost never be assumed to be cheaper or easier.
While it may be hard to remove code, my view is that it is generally not harder than re-ordering in most codebases. Why? The primary cost of both code removal and scheduling interventions is the investment to deeply understand page behaviour. This presents a narrative challenge to the proposition that scheduling is an easier fix, as both approaches share the largest cost.
At the team level, the consequences of restructuring are harder to reason about than direct removal, reducing potential upside and increasing validation costs.
Bytes that are only deferred still contend for bandwidth, potentially delaying above-the-fold resources in ways that only become visible in the tail of the connection quality curve. Worse, late-fetched JS resources generate heavy "thuds" when residual allocations from background compilation arrive on the main thread. These stalls show up in INP data, but can be maddening to track down due to their stochastic relationship with other resources and the unpredictable scheduling of main-thread tasks in the real world.
The overhead of re-explaining these factors presents an ongoing challenge. Working across teams to preserve carefully constructed code ordering requires exquisite regression-prevention discipline and cross-team buy-in. This elevates the degree of operational difficulty versus code removal, where simple bundle size clamps can maintain gains.
From the geosynchronous perspective, it becomes easier to see that reordering exacerbates coordination challenges, and per Fred Brooks, those communication effects dominate the shape and quality of the pages a team delivers.
In large enough teams and codebases, creating and maintaining an optimal ordering is a question of global priorities that can only be elucidated by product owners. As they tend not to be the line engineers, their goals will be translated to code in ways they will not fully understand, and the deep implications of that translation process may only become clear in retrospect. It was ever thus in the pin factory.
Goals may also be communicated in different intensities and formats, and change over time. Worse, teams often misidentify their targets. Many groups I've worked with have confidently asserted that "everyone has 5G" or "everyone's on fast devices," despite neither their own dashboards nor the global baseline supporting that presumption. Teams in this situation can easily make incorrect assumptions about the network, CPU, and memory limits of users at the margins. Getting in touch with those limits is straightforward for interested managers, and it's a big part of climbing the Performance Management Maturity ladder. Leaders working through this landscape for the first time are frequently shocked to find just how far out-of-the-money their products have become.
Regardless, many teams build to (or past) it blithely, then spend tremendous amounts of effort re-ordering code without achieving durable gains or increasing TAM. From this market-centric view, removing code has the benefit of making the system more resilient to changing conditions, including shifts in user population due to product growth. This makes code removal particularly potent under uncertainty about user populations, which is where nearly every web project begins life.
Systems that rely on scheduling to assure reasonable performance are brittle. Reordering work to appear responsive for one user journey can help, but such systems have a comparatively harder time adapting to changing needs — something Marko's examples work through, but with only one alternative explored. In reality, products that need this level of attention face an evolving field of possibilities across an expanding range of users and devices, while an increasing stable of features contend for priority.
Teams hoping for performance headroom through scheduling can also reduce their agility through use-case overfitting. Latency concerns become a straitjacket when multiple critical user journeys funnel through a single chokepoint that must balance the needs of all. This should bias remediation toward removing code and breaking up experiences MPA-style until a team is far into the tail of diminishing returns.
Not only will those improvements prove more durable and easier to defend, but smaller systems are also easier to reason about. Code size reductions set the stage for more effective scheduling fixes when a team is ready to switch approaches from a position of confidence.
An underappreciated headache of systems drawn taut around available bandwidth and CPU constraints is that they aren't just difficult for engineers to wrangle; they also appear brittle to managers.
Busy EMs and PMs experience systems in this state as teetering on the edge of usability while soaking up huge amounts for "optimisation." Managers can even end up in learned helplessness as regressions crop up in curious parts of the experience with each seemingly unrelated change. The interplay of browser scheduling, network conditions, and device constraints is extremely fluid, making scheduling fixes the less bankable alternative, especially at page load time. Teams that spend the same quantum of effort eliminating code, by contrast, have more wiggle room and can be more agile over time. Managers that buy into the narrative that reordering is easier than removal deal their future selves a losing hand.
All things equal, the level of difficulty from an enforcement, regression-prevention, and span-of-control perspective is higher for re-ordering vs. code removal, and savvy managers should always favour investments that will cut code or move it to the server, rather than pushing peas around the plate over the wire or on the client.
A particularly grim failure mode of scheduling as the go-to performance remediation approach plays out in large organisations through competitive use-case devaluation. Individual feature owners advocate for their code to be loaded early, implicitly deferring or delaying code required for other user journeys. This interacts poorly with haunted SPA architectures that force code-loading priorities to play out over an unknowably slow or laggy network and onto a device whose memory and CPU properties are a mystery. In the tail of the distribution, SPA architectures assure that every choice to fill the channel with Team A's code harms Team B's experience.
Bun fights inevitably break out as a degraded commons raises the stakes on every team, backing managers into increasingly strident advocacy for their feature. Because engineering teams in this situation are generally not imposing code size budgets (thanks in part to the mistaken belief ordering will save the day), the consequences for de-prioritisation grow over time. The negative feedback loop is obvious. The notion that scheduling is easier than code removal steers the product into a coffin corner sure as day follows night.
But it's even worse than it sounds.
Because the implications of deferring other code may be hard to reason about, devaluation of a product's core experiences can spiral, unopposed, for years. In this twist on the general failure mode, "special interests" degrade an undefended commons. Thanks to compilers and code motion in "modern" frontend codebases, order-dependent optimisation approaches and "preloading" hacks can hide in plain sight, ballooning costs for all users as seemingly innocuous library code is added to XXXXXX-common.js and YYYYYY-vendor.js without opposition.
A common attribute of low Performance Management Maturity organisations is an absence of processes to push back on this sort of thing. The result is a Gordian Knot that only ever grows more tangled. The linchpin is not doubling down on code ordering, but a decision to get wire size under control.
An unreasonably effective down payment on this commitment is to evict all "preloading" and "deferred loading" systems from a product, size it up as it stands, then force trims. This isn't always the right approach (consulting engineers should always be trace-driven), but for teams that have followed the logic of preloading down the primrose path, it's a bracing corrective that creates accountability through visibility. From that point, "we don't do that here" must become the manager's mantra whenever a feature PM repeats discredited paeans to scheduling, otherwise the product will end up back in the drink.
Unlike removed code, the impact of reordered code is not easy to reason about. Innocuous-looking scheduling changes like loading="lazy" for <img> and <video> can go horribly wrong. Without system knowledge, infrastructure, and culture to support investigations, it's much more difficult to know if work reordering improves end-user perceived latency.
All of this is to take nothing away from the thoughtful technical advice in Marko's post. We can dramatically improve critical-path loading and responsiveness of experiences by better ordering resources, and we should strive to only do work proportional to what's currently on-screen, above the fold.
But that set of opportunities should be treated by engineers and managers as special occasion food. While both approaches can, in theory, yield similar gains per hour of effort, scheduling changes only pan out in systems that already have strict size budgeting, regression prevention, and hawkish launch gates. Unless a team is at least demonstrating the regression prevention attributes of Level 4 Performance Management Maturity, investments in better ordering are a management error. Teams without a strong hand on the rudder and battle-tested early warning systems should, instead, focus almost all of their effort on reducing complexity and code size.
Investments in size reduction also tee up future scheduling improvements, teaching teams about the interplay of system components. Without deep insight into site behaviour, it is challenging to select good opportunities for reordering, and the learning inherent in code reduction invariably helps identify ripe scheduling wins. Likewise, reductions in payload complexity make it simpler and more effective to test the impact of reordering.
In other words, going from decent to excellent performance is a technical challenge, but moving from poor to decent performance is fundamentally a management and culture problem.
Marko's piece is excellent fodder for teams that have a technical problem. I wish that represented more than a sliver of the organisations I've consulted with.
Taken together, these factors give rise to the structure of the advice I dole out to teams looking for help:
Management challenges also give rise to our request that teams enunciate "critical user journeys" and put thought into who their marginal user really is. Just getting leads and PMs to agree on which users shouldn't be excluded due to poor performance and what the most important flows are can create clarity and value, independent of which approach to alleviation a team pursues.
There are a lot of problems that can be ameliorated with better scheduling, but the level of affirmative control a team has to have over a system to effectively execute on those tactics is shockingly uncommon. Therefore, most teams, most of the time, are better off thinking about how to remove code from their bundles.
Brett Cannon 16/08/2026 | Source: Tall, Snarky Canadian
While writing the section of my 2026 Python Packaging Council (PPC) nomination on secure supply chain, I realized that one thing related to having a secure supply chain that we lack is a defined way to perform reproducible builds. The reason I like the idea of making reproducible builds work is that I think it can be done in such a way as to not require any work on the part of the producer of a distribution (which is a technical term for sdists or wheels, i.e., the people who upload stuff to PyPI), and thus make reproducible builds very low-friction for people to opt into supporting.
In terms of secure supply chain, reproducible builds can let independent 3rd parties verify that the bits in a distribution match what's expected based on the source code the distribution was made from. That lets you potentially detect if anyone tampered with the code during the build process. As well, there's a side-effect that from having to record the software involved in the build process means you can more easily detect if some known, compromised tool was used even if you don't do everything necessary to verify the bits are exactly the same. And this isn't some hypothetical benefit: SolarWinds was compromised due to malicious code being injected into the build process.
And don't let the word "build" fool you into thinking that pure Python wheels aren't vulnerable. There's a build backend that was used to make that wheel, and if that build back-end was compromised then it may inject some malicious code into the wheel. So there isn't some area in Python packaging that gets to ignore these risks.
So what do we need in Python packaging to make reproducible builds possible? First, we need to record what source code was used. This isn't recorded in sdists or wheels, but if you install directly from a source repository or an archive then it's recorded in a direct_url.json file by your installer. If we were to record the same information in sdists and wheels (such as in the metadata), then we would know the location of the source code used to make the distribution.
But the next tricky bit is recording all the tools used to create the distribution. For wheels, we have support for recording software bill of materials (SBOMs). And as PEP 770, which added that support, says (disclaimer: I was the PEP delegate), SBOMs can be used to record the build tools used to create a distribution. And if you record all the software used to build a distribution, you can hopefully reproduce the exact same bits and show nothing was tampered with.
Unfortunately, sdists don't have a similar mechanism to record SBOMs. Since sdists are usually just a tarball with a PKG-INFO file that contains some precalculated metadata, there isn't a place to put any other metadata file. So we either have to shrug and say, "don't use sdists if you want reproducible builds," or we will have to come up with some sdist v2 format that allows for more structured data.
Now, you might be wondering how you would even go about reproducing a build even if you do have all of this information. Luckily, since we have the [build-system] table in pyproject.toml, we have a defined entry point into the build back-end that produced the distribution. That means once we have all the software required to run the build backend recorded, we can replay the build process by installing the same things and calling the build backend as defined by [build-system]. And if build backends took care of recording what's installed in the environment they are running in, theoretically we could record all the software used for the build back-end and store it in SBOMs today without distribution producers having to do extra work (but it does mean work for the pip maintainers).
Assuming all of this comes to pass and we record the where the source code is that went into a distribution and the software used to make the distribution, how do we make it useful to people? Does every person who cares about having a secure supply chain have to rebuild everything they use themselves? Is there some way for even people who don't care about this stuff to benefit?
One possible way is if there were trusted verifiers who could tell PyPI when they successfully reproduced a distribution. Since various enterprises are going to be doing this anyway, they could feed that information back to PyPI so they can visibly say for a distribution file, "this file was independently reproduced by <name of trusted party>". That means users get to know a distribution is what the creator expected, and the verifier gets a bit of recognition for helping the community out. This could even be surfaced in the index API so you could have installers prefer reproduced distributions.
This should be done in a way not to shame anyone who happens not to use a build backend that can create a distribution that can be reproduced. This should always be viewed as a perk and not a requirement. It's like getting to say your project meets build level 1 of SLSA (which all of this would meet); some people like getting to say that, but it isn't a knock against anyone who chooses not to care.
Thanks to Seth Larson for listening to my idea and also checking over this blog post.
 giovannireisnunes
 Here Dragons Abound